

Research Infrastructure & Lab Automation· Evidence · Frontier
Anthropic Opens a Research Preview of MHS, a Common Hardware Interface for AI Agents
Anthropic's MHS proposes a shared Interact layer for the AI4S loop: agents can discover, control and coordinate physical instruments through one interface, then return states, measurements and errors upstream. It is a research preview, open to a first group of partners; the spec and drivers are not yet public.
◐Research preview + prospective physical-device demonstrations
Current boundary: Real devices demonstrate orchestration, parameter adjustment, automated retries and control optimization, but not complete autonomous discovery; the standard remains a research preview and the evidence is primarily reported by Anthropic and its first partners
This work advances: Lets AI agents operate and coordinate physical instruments through a common interface
- MODELUnderstand / predict
- DECIDEChoose next
- INTERACTTest against reality
- UPDATEChange next round
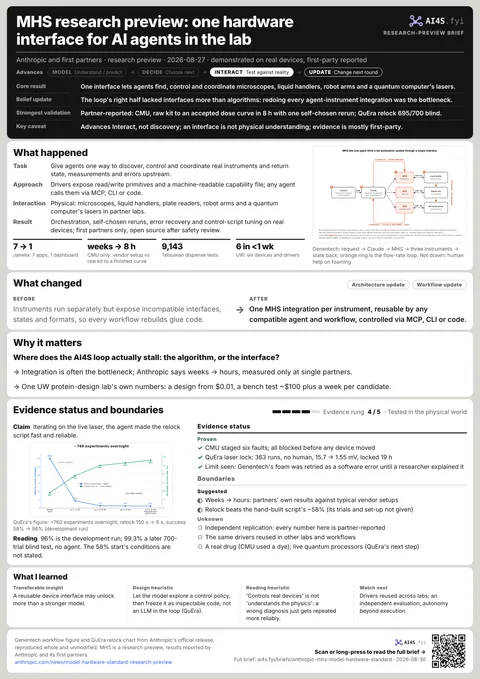
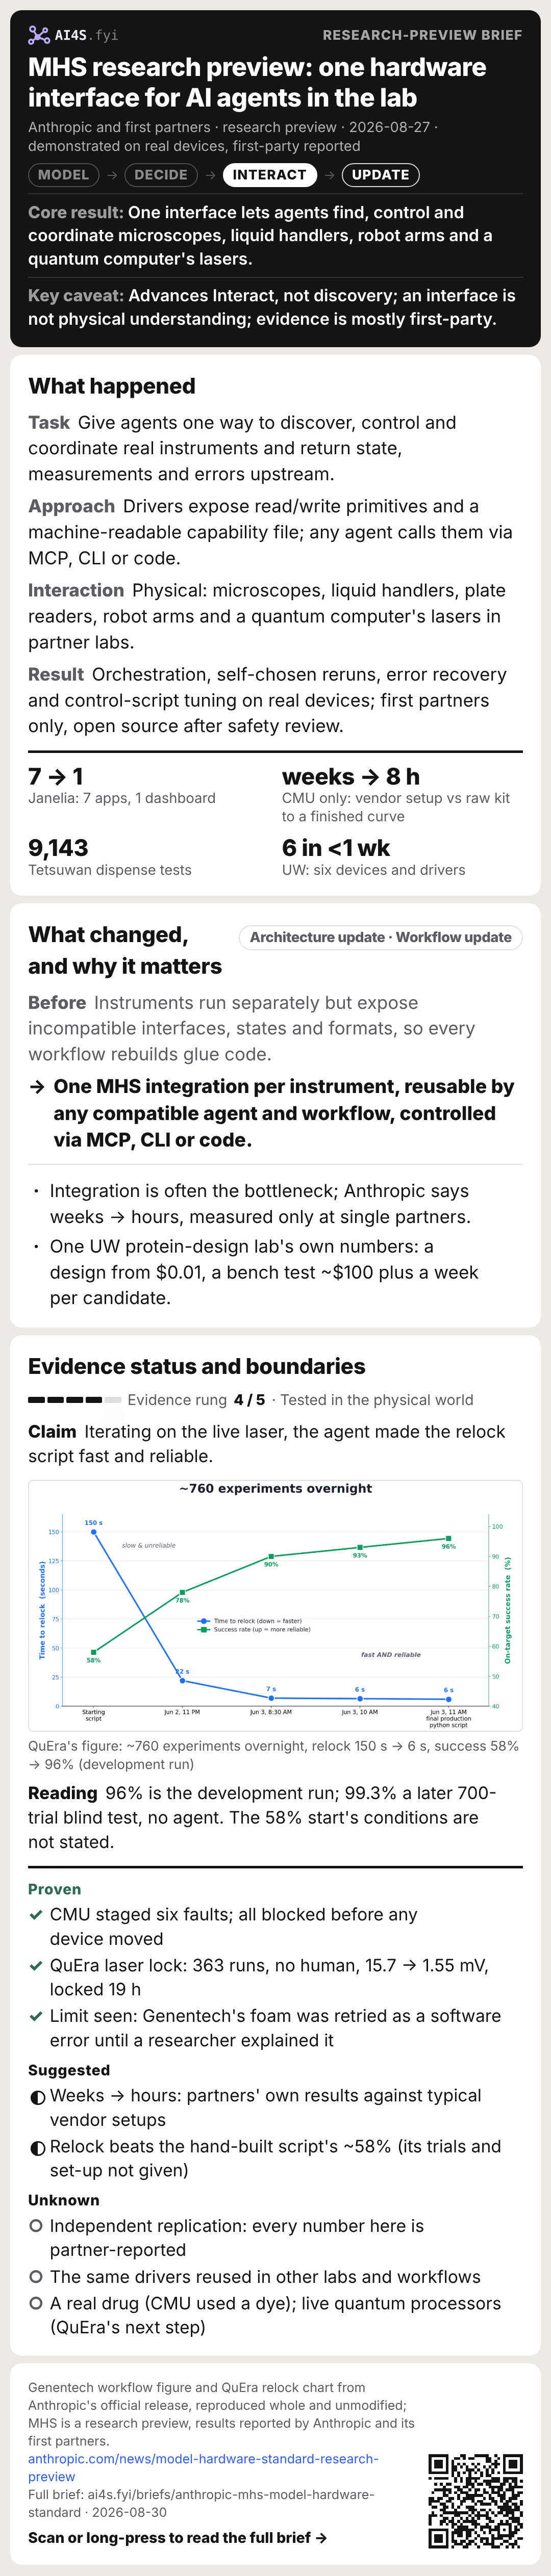
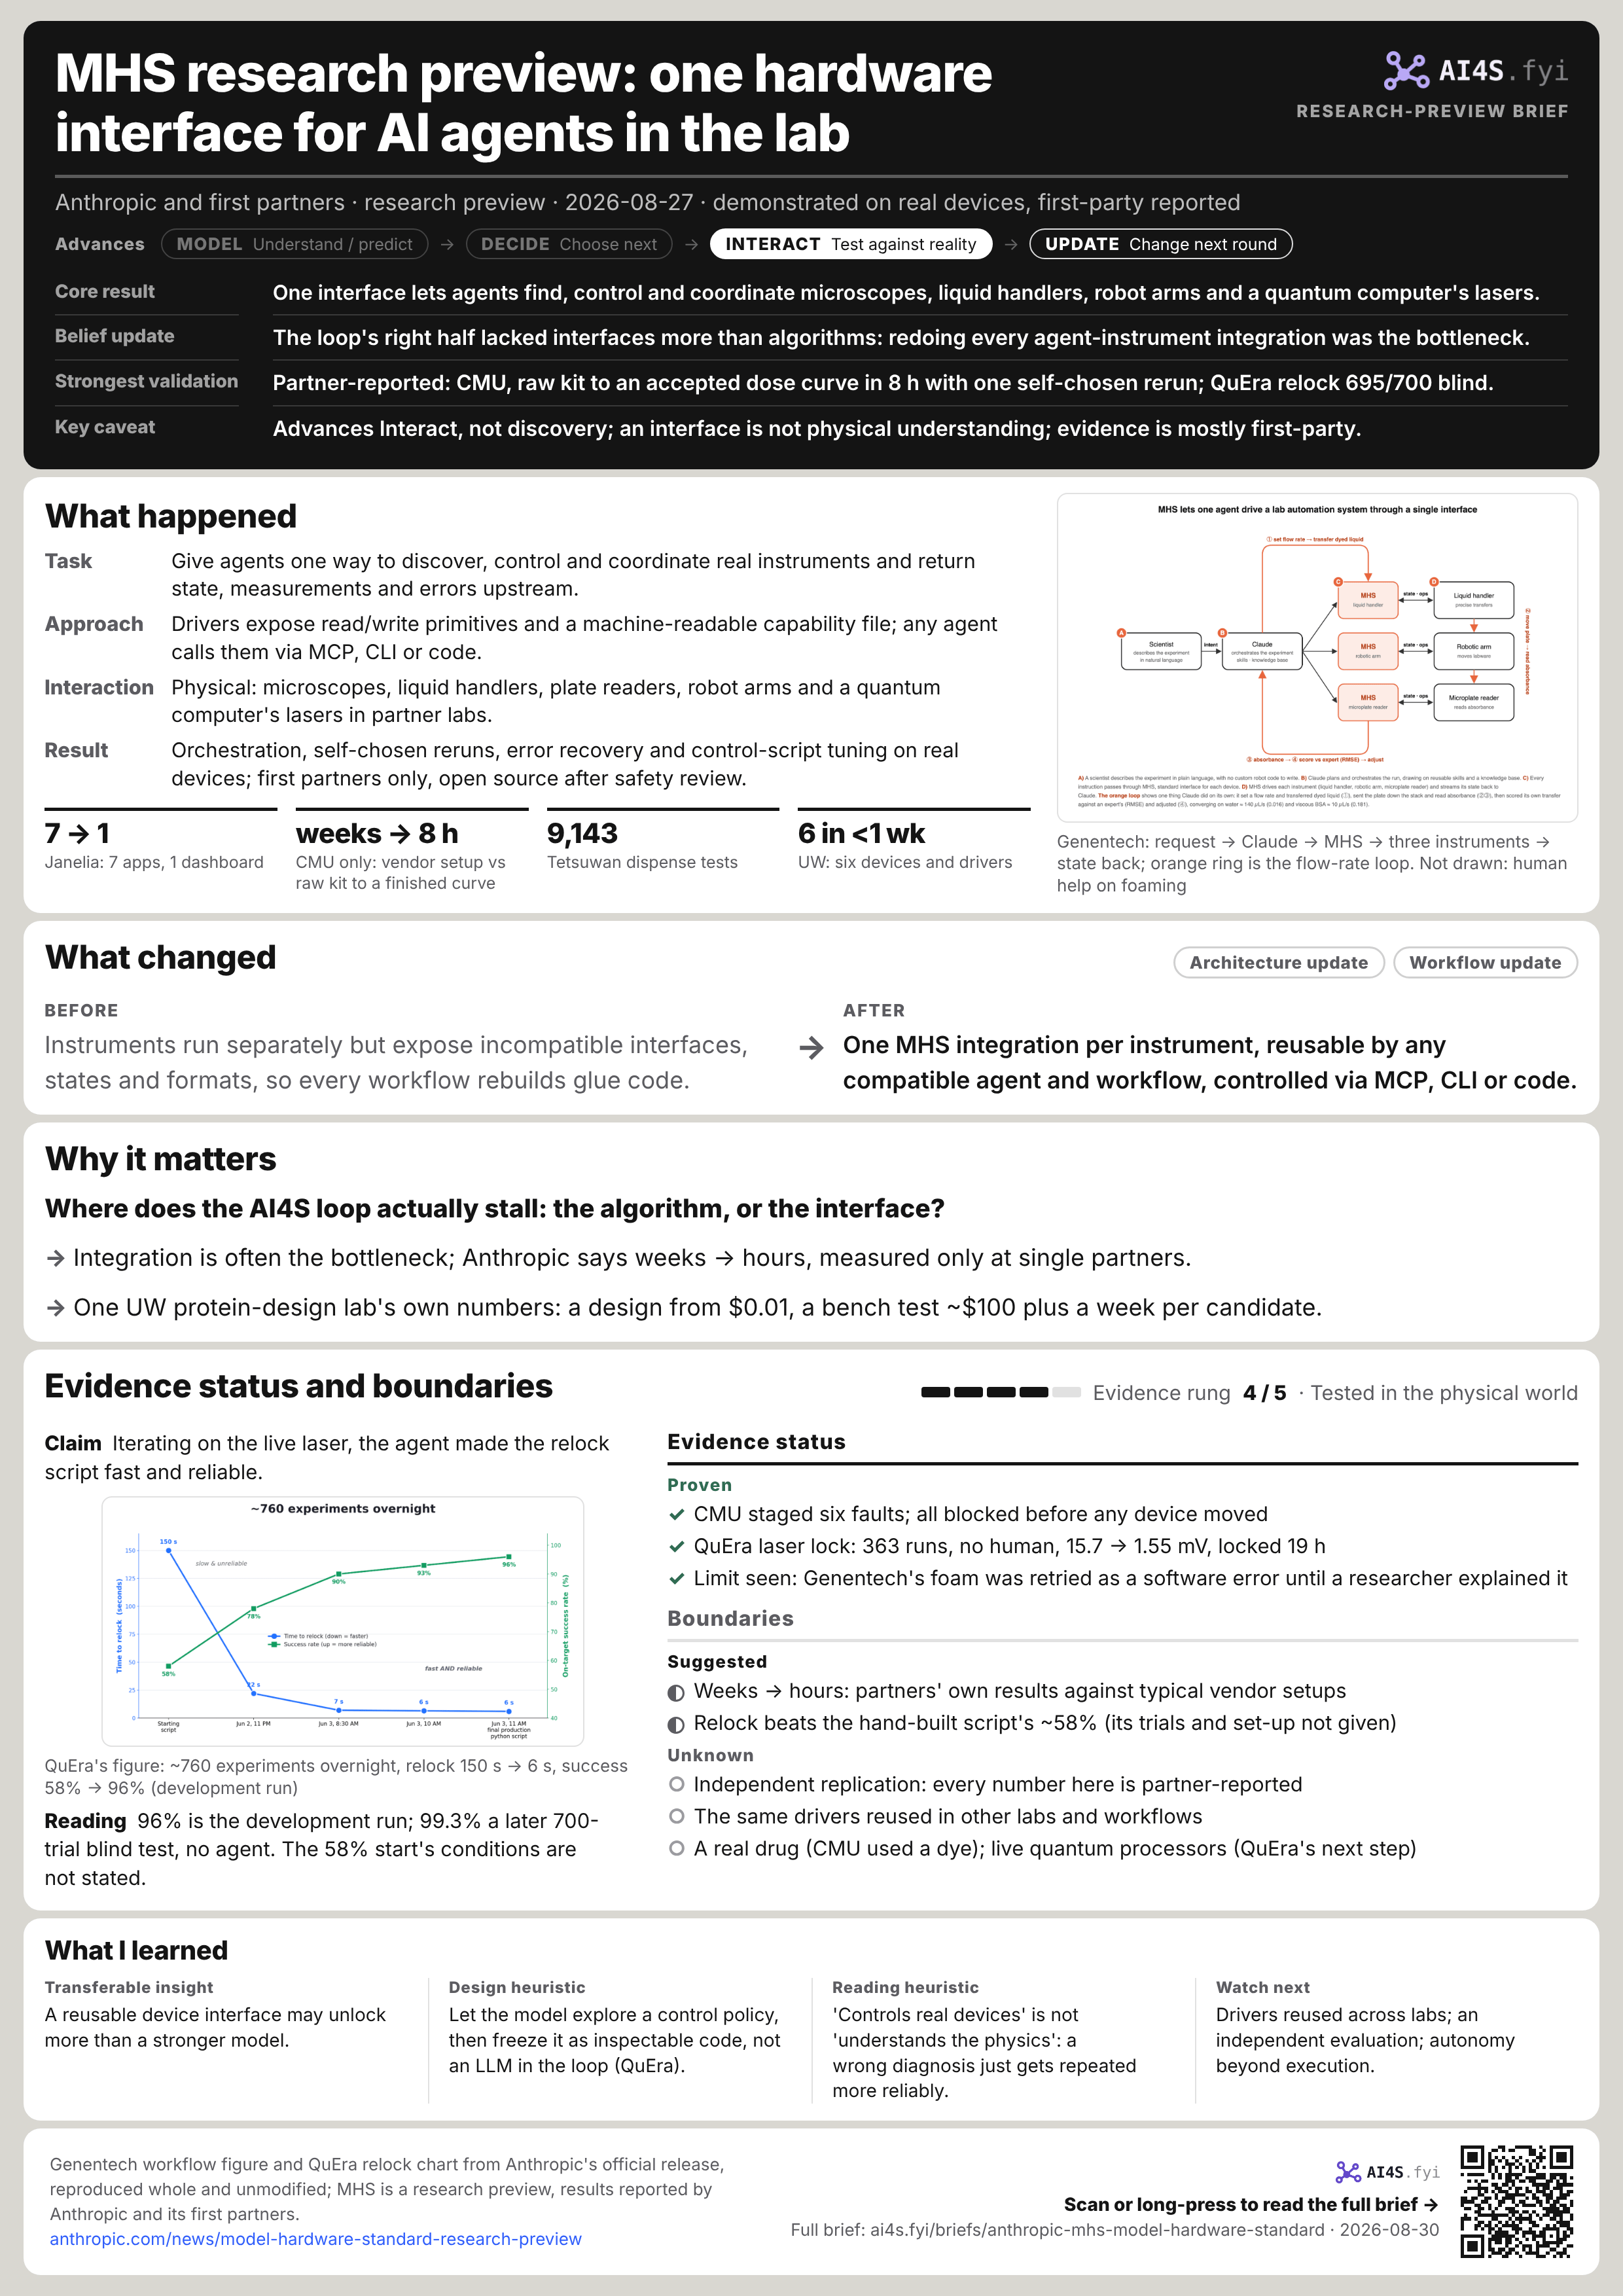
One interface lets agents find, control and coordinate microscopes, liquid handlers, robot arms and a quantum computer's lasers.
- Belief update
- The loop's right half lacked interfaces more than algorithms: redoing every agent-instrument integration was the bottleneck.
- Strongest validation
- Partner-reported: CMU, raw kit to an accepted dose curve in 8 h with one self-chosen rerun; QuEra relock 695/700 blind.
- Key caveat
- Advances Interact, not discovery; an interface is not physical understanding; evidence is mostly first-party.
01What happened
- Task
- Give agents one way to discover, control and coordinate real instruments and return state, measurements and errors upstream.
- Approach
- Drivers expose read/write primitives and a machine-readable capability file; any agent calls them via MCP, CLI or code.
- Interaction
- Physical: microscopes, liquid handlers, plate readers, robot arms and a quantum computer's lasers in partner labs.
- Result
- Orchestration, self-chosen reruns, error recovery and control-script tuning on real devices; first partners only, open source after safety review.
7 → 1Janelia: 7 apps, 1 dashboard
weeks → 8 hCMU only: vendor setup vs raw kit to a finished curve
9,143Tetsuwan dispense tests
6 in <1 wkUW: six devices and drivers
On August 27, 2026, Anthropic opened a research preview of MHS, the Model Hardware Standard, to a first group of research labs and advanced manufacturers. The shared specification lets AI agents operate physical devices; early projects span microscopes, liquid handlers, microplate readers, robotic arms and laser-control systems for quantum computers. The spec, drivers and code have not been published.[S1]
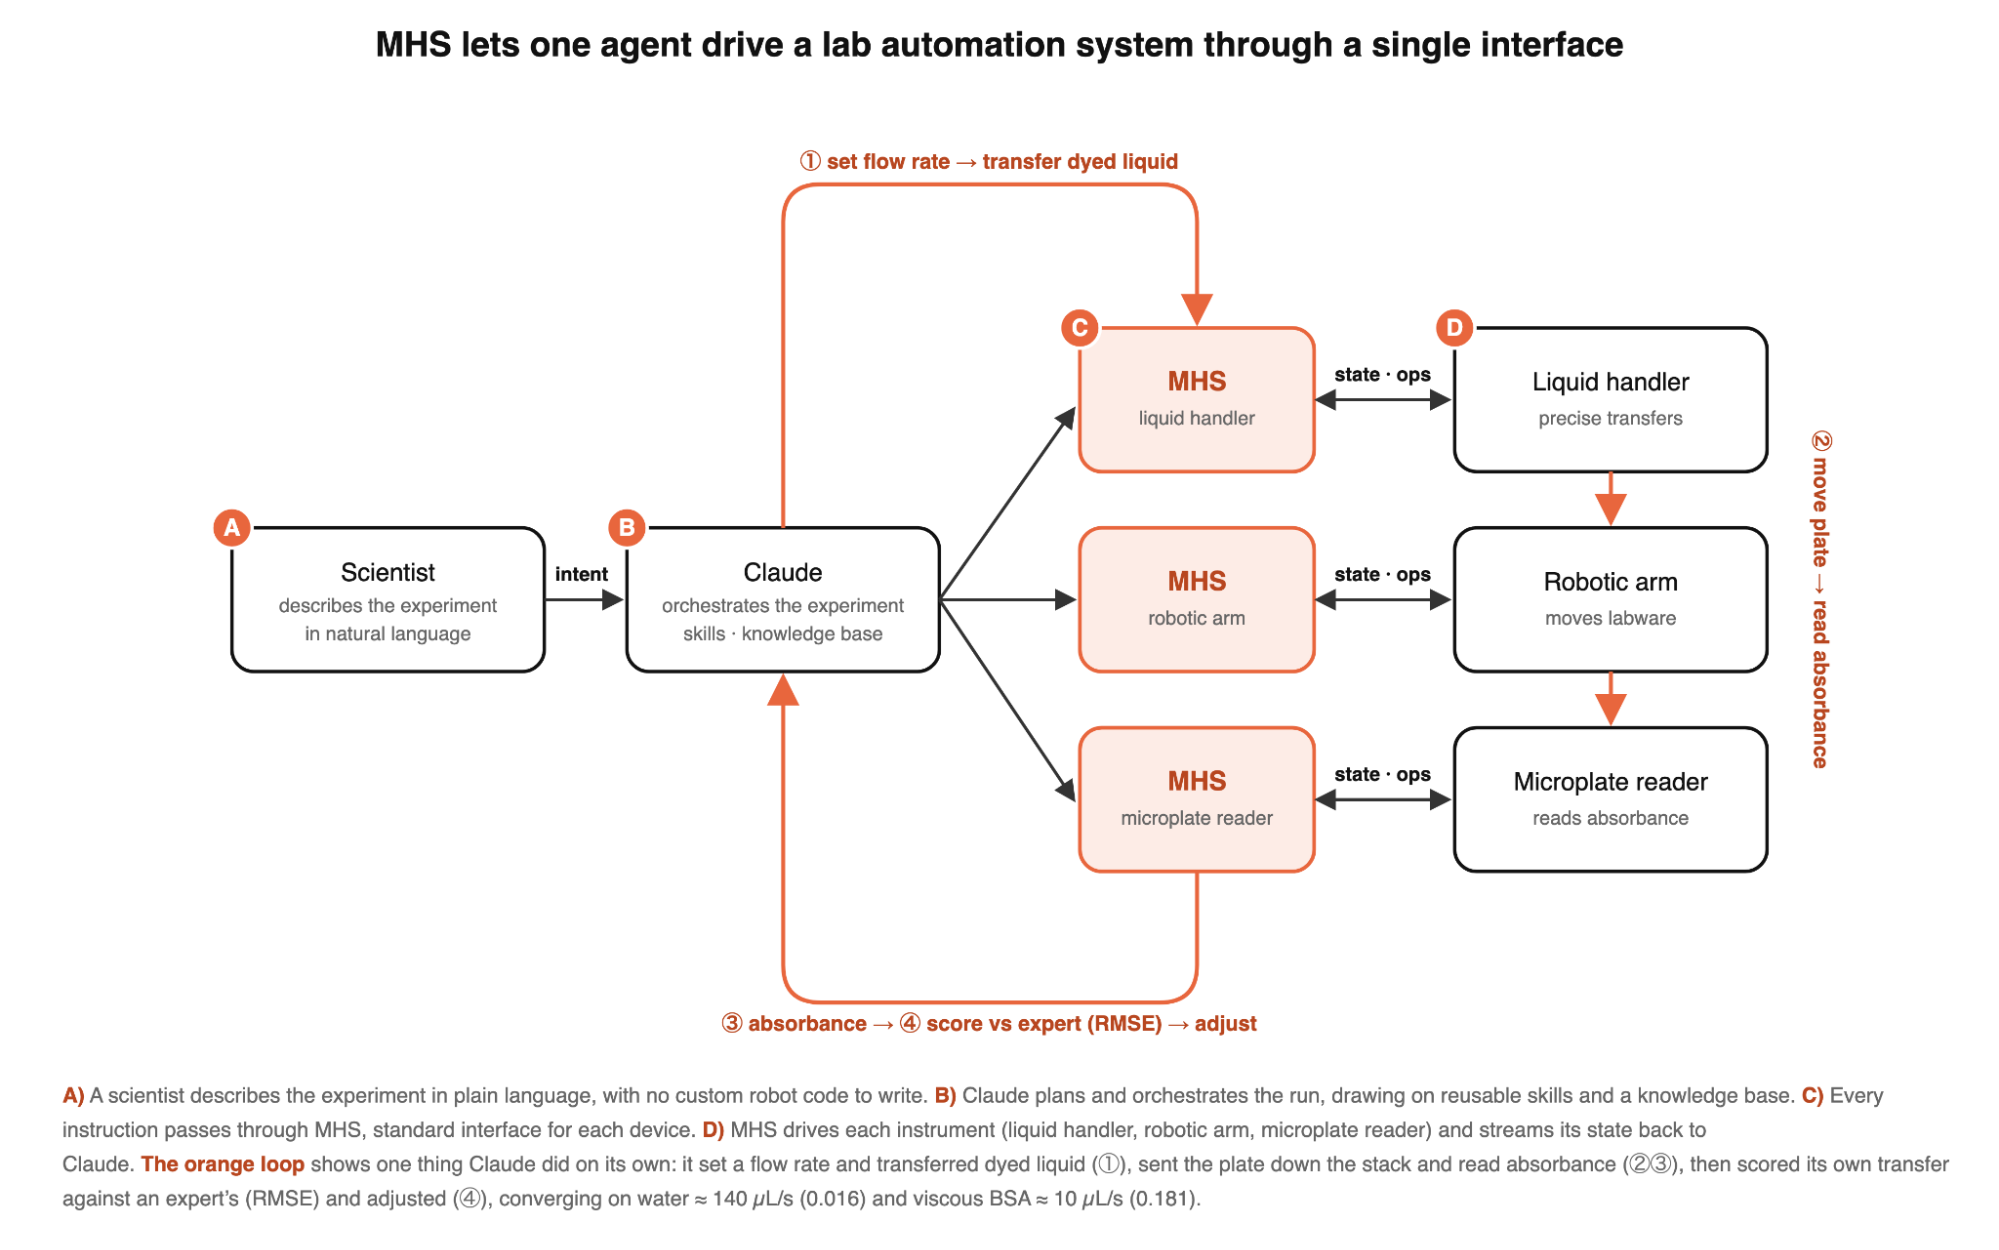
The basic path is scientific agent → MHS interface → device driver → instrument or robot, with state, measurements and errors returned upstream. Drivers expose common primitives such as read and write and generate a machine-readable reference file describing capabilities, adjustable parameters, current state and safety limits.[S1]
One useful mental model is MHS as an extension of MCP into the physical world. MCP gives models a common way to discover and call software tools; MHS applies a similar interface idea to instruments and robots. The analogy stops there, because physical devices must also handle live state, motion limits, hardware faults and safety interlocks.[S1]
Agents can control devices through MCP, a command-line interface or code. For low-latency or long-running work, an agent can package an operating sequence into deterministic code so the device executes without language-model reasoning at every time step.[S1]
MHS is model-agnostic rather than Claude-specific; any compatible agent harness can in principle use it. Access is currently limited to an initial group of research and manufacturing partners, with open sourcing planned after further physical-safety evaluation and deployment guidance.[S1]
02What changed
Architecture updateWorkflow updateInstruments run separately but expose incompatible interfaces, states and formats, so every workflow rebuilds glue code.
One MHS integration per instrument, reusable by any compatible agent and workflow, controlled via MCP, CLI or code.
Which part of the scientific loop does MHS advance?
Its primary contribution is Interact. Once an upstream system decides what to do, MHS converts that decision into multi-instrument operations, reads device state and returns measurements and execution errors. It supplies neither a new scientific model nor the hypothesis or experiment-selection policy.[S1]
Some projects already form bounded loops of execute, measure, adjust and retry. Sustained scientific learning still requires an external model to interpret results, a decision layer to choose the next experiment, an update layer to change a model or policy, and safety and exception handling for long-running operation.[S1]
The narrower conclusion is that MHS reduces integration cost between Interact and Update, making autonomous loops easier to build without itself demonstrating autonomous scientific discovery.
Why a common interface still needs device drivers
The analogy to USB for laboratory hardware is useful but incomplete. MHS does not eliminate drivers or make a manual instrument programmable. A device still needs an API, SDK, CLI, COM interface, file-drop system or automatable GUI, and its low-level differences still require a driver.[S1]
MHS standardizes how agents discover and call devices, not the devices' internal implementations. It translates capabilities, live state, operations and safety constraints into a discoverable interface for upstream systems.
From one-off glue code to a reusable device interface
Many instruments are already software-controllable. The hard part is that vendor software, programming languages, data formats and state representations differ. A new device often requires fresh glue code, protocol handling, state synchronization and recovery logic, work that Anthropic and its partners say commonly takes weeks or months.[S1]
MHS attempts to replace one integration for every agent–instrument pair with one MHS integration per instrument that compatible agents and workflows can reuse. The immediate advance is interoperability, not stronger scientific reasoning.
Model exploration, deterministic execution
MHS also demonstrates a useful division of labor for physical systems: a model explores a device, observes feedback and improves a control policy, then writes inspectable, testable deterministic code. QuEra used this pattern for laser control, with the final script running without the agent remaining online.[S1]
The language model handles open-ended exploration and improvement; deterministic code handles speed, stability and auditable execution. That is more realistic than keeping an LLM permanently inside a millisecond-scale control loop.
This division of labor improves execution efficiency and auditability; it does not supply physical understanding. A model can turn a useful procedure into code, but if it misdiagnoses a failure, deterministic execution may simply repeat the mistake more reliably. The Genentech case below exposes exactly that boundary.[S1]
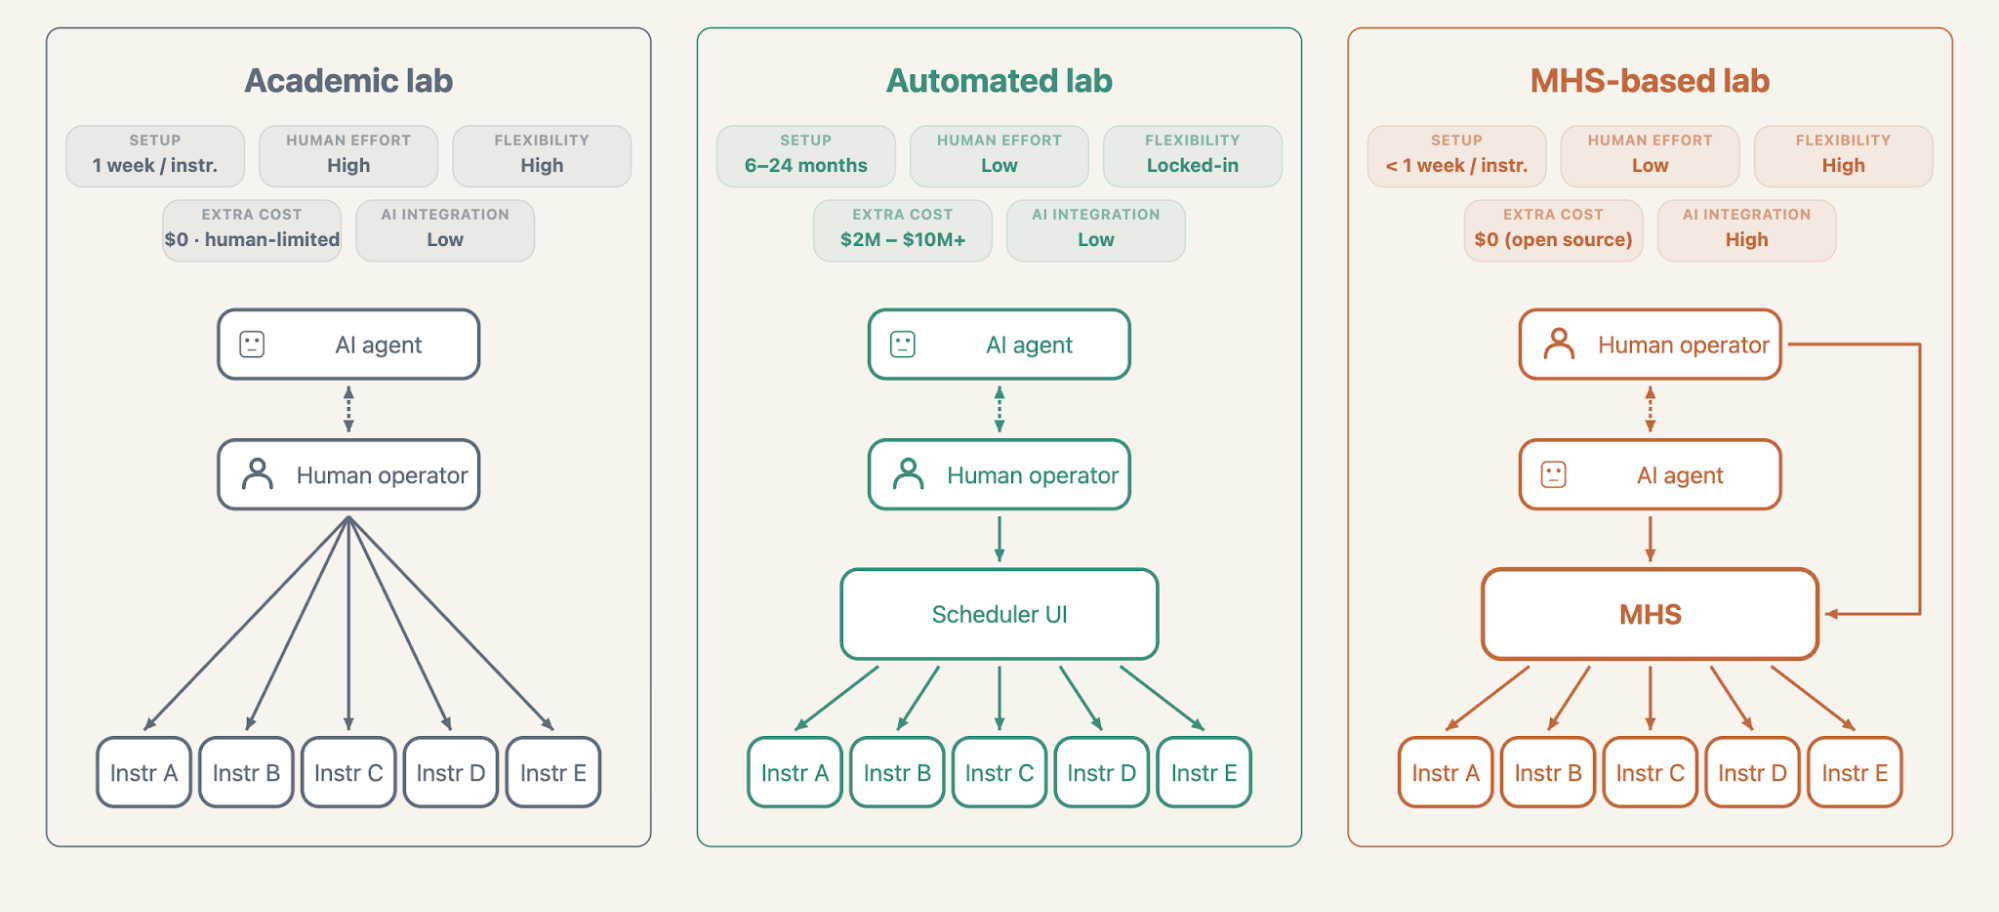
Anthropic / UW Baker and Pinglay labs, Fig. 1: MHS connects distributed instruments through a common scheduling and monitoring layer while preserving research flexibility. Image from Anthropic's official release. [S1]
03Why it matters
Where does the AI4S loop actually stall: the algorithm, or the interface?
- Integration is often the bottleneck; Anthropic says weeks → hours, measured only at single partners.
- One UW protein-design lab's own numbers: a design from $0.01, a bench test ~$100 plus a week per candidate.
The bottleneck is often not whether one instrument can be programmed, but whether different instruments can share state, respect dependencies and form one research workflow. If researchers still move results manually between vendor tools, even a strong experimental plan cannot continuously become physical evidence.[S1]
Traditional automation excels at repeating a fixed protocol thousands of times. Research changes samples, device combinations and conditions, and the next step may depend on the latest result. MHS places a reusable interface between deterministic equipment and changing research goals rather than replacing mature device control with an agent.
The economics at the UW Baker and Pinglay labs make the bottleneck concrete (these are the lab's own de novo protein-design figures, given by its PhD student in the release, not a general cost). Designing a protein such as PETase can cost as little as $0.01, while testing one candidate at the bench costs around $100 and a week of labor, and the lab tests 1,000 candidates at a time. The team connected six devices, including driver development, in under a week to narrow this widening gap between computational proposals and physical feedback.[S1]
Within design–build–test–learn, MHS primarily covers Build and Test plus device coordination and data handoff. Design still comes from scientific models or researchers, while Learn still requires an external model to interpret results, update strategy and choose another round.[S1]
Tetsuwan provides a larger-scale example of device characterization: the system ran 9,143 dispense tests, and its precision model improved on the manufacturer's specification by 12% on held-out conditions. A common interface can therefore do more than issue commands; it can return operational data to calibration and control workflows.[S1]
Partners announcing support, pilots or integration plans at launch included AWS (Strands Robots), Automata (LINQ), Danaher, Doosan Robotics, MBF Bioscience (ScanImage), QIAGEN (QIAsymphony Connect), Tecan (Fluent), Universal Robots, Hugging Face (LeRobot) and Raspberry Pi. That signals supply-side willingness to experiment with the standard; it is distinct from evidence that the same driver already works safely across laboratories and projects, which requires real deployments.[S1]
04Evidence status and boundaries
Evidence rung 4 / 5 · Tested in the physical world · Closed-loop experimentationEvidence status
Proven
- CMU staged six faults; all blocked before any device moved
- QuEra laser lock: 363 runs, no human, 15.7 → 1.55 mV, locked 19 h
- Limit seen: Genentech's foam was retried as a software error until a researcher explained it
Boundaries
Suggested
- Weeks → hours: partners' own results against typical vendor setups
- Relock beats the hand-built script's ~58% (its trials and set-up not given)
Unknown
- Independent replication: every number here is partner-reported
- The same drivers reused in other labs and workflows
- A real drug (CMU used a dye); live quantum processors (QuEra's next step)
ClaimIterating on the live laser, the agent made the relock script fast and reliable.
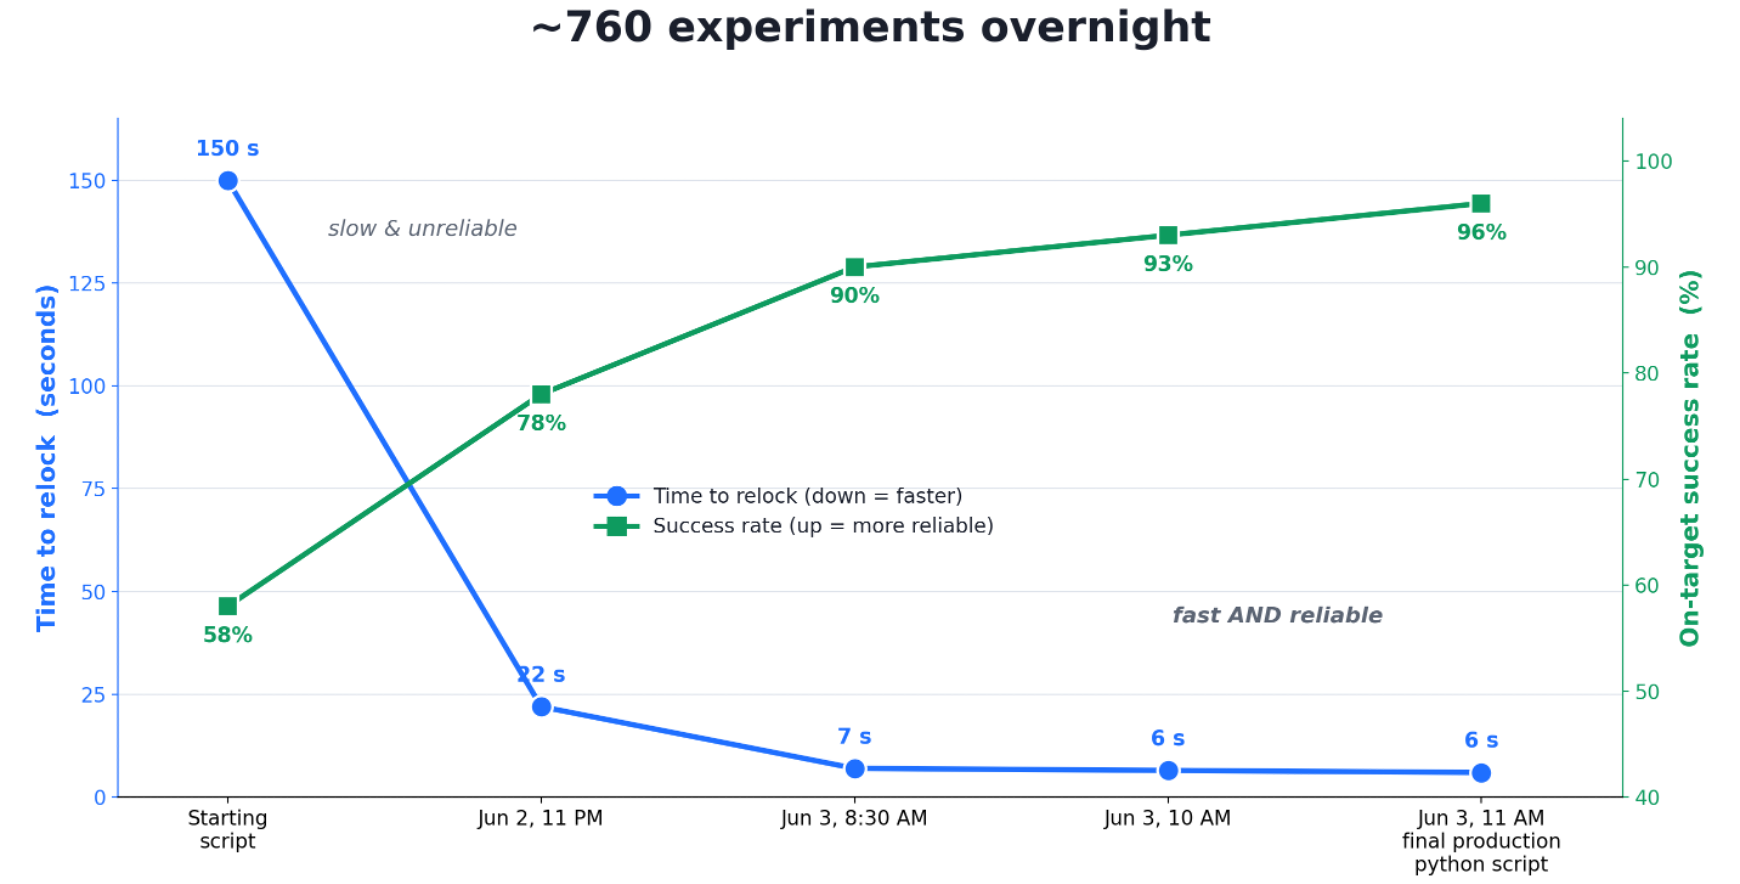
Reading96% is the development run; 99.3% a later 700-trial blind test, no agent. The 58% start's conditions are not stated.
These are not software-only simulations.
MHS has operated liquid handlers, robotic arms, plate readers, microscopes, lasers and quantum equipment. CMU and QuEra include prospective real-device runs, making the evidence stronger than an ordinary product demo or a simulation-only agent workflow.[S1]
The evidence remains first-party and partner-reported.
The results appear inside Anthropic's official release rather than a shared benchmark, independent evaluation or peer-reviewed study. This page treats CMU's fault blocking and QuEra's 700 blind trials and 363 tuning experiments alike, as partner-reported measurements: measured on real devices, none replicated outside. Devices, tasks, safety boundaries and metrics differ, so no single result transfers automatically to another lab; "weeks to hours" is likewise individual partners comparing their own result with typical vendor setups, not a reduction that holds for every instrument.[S1]
CMU demonstrates bounded closed-loop execution.
The "self-chosen rerun" was the whole dose-response run: the first plate topped out at 200 µg/mL, saturated at high concentrations and fit at R² < 0.9, so the system rejected it, discarded the plate, cut the top concentration to 100 µg/mL and reran on a fresh plate, reaching R² > 0.98 with no human input. From unautomated instruments to a finished curve, rerun included, took 8 hours, against the multiple weeks the team says a vendor-built setup typically takes: one case at CMU, not a general reduction for every instrument. That moves beyond fixed automation. The team also induced six failures (a missing plate, a rotated plate, a busy reader, a disconnected camera, an unreachable device and an emergency stop), and every one was blocked before robotic motion. But the experiment used a colorimetric dye in place of a drug, validating operational, safety and decision structure rather than autonomous drug discovery.[S1]
UW demonstrates lower-cost, faster laboratory integration.
The Baker and Pinglay labs connected six distributed devices in under a week, including driver development, and linked a dashboard, qPCR stop recommendations and multi-device workflows. This is a strong demonstration of integration speed and real demand, but the same drivers have not yet been replicated across independent laboratories and different protein workflows.[S1]
QuEra demonstrates equipment-control optimization.
The agent improved a control strategy through hundreds of real experiments and validated the script through blind tests and extended runs: the relock script succeeded in 695 of 700 blind trials (99.3%), run on the same randomized set of induced disturbances with no agent involved. The earlier hand-built script, several months' work by a four-person team, worked about 58% of the time at about 150 seconds an attempt; it was also the starting point of the overnight development run (about 760 experiments, ending at 96%). The release does not say how many trials the 58% rests on or whether it faced the same disturbances, so the two are not a strictly like-for-like comparison. It then tuned 12 PID parameters over 363 experiments and 16 unattended hours, taking the specialist's standing tune from 15.7 mV of residual error to 1.55 mV (roughly 10 times lower on the RMS measure it optimized); on a phase-noise analyzer it matched the specialist's blind retune across the band except for a resonance near 220 kHz, and over a 19-hour run its parameters never lost the lock while the expert's unlocked about 1.6 times an hour. The task had a defined objective, observable state and success criterion; it did not generate a new quantum-physics hypothesis. QuEra's next step is to deploy the relock system on live quantum processors, which has not yet happened.[S1]
A physical interface is not physical understanding.
In Genentech's foaming example, Claude initially treated a physical problem as a software error and retried in the same well with new parameters, which made more bubbles. This is an observed limitation, not an open question. A researcher had to explain the cause before it moved to a clean well and reduced mixing. The interface says what can be done and what the device reports; it does not explain why the physics failed.[S1]
Execution autonomy is not full scientific autonomy.
Humans still define goals, candidate spaces, success criteria and exception boundaries. MHS supports substantial automated execution and local parameter updates, while scientific-model updates and the direction of the next research round remain external.
Fully manual legacy equipment still needs modification.
MHS requires a software-operable entry point. Instruments that depend on manual knobs, manual loading or non-digital state still need vendor drivers, extra sensors, robotics or hardware modification.
05What I learned
- Transferable insight
- A reusable device interface may unlock more than a stronger model.
- Design heuristic
- Let the model explore a control policy, then freeze it as inspectable code, not an LLM in the loop (QuEra).
- Reading heuristic
- 'Controls real devices' is not 'understands the physics': a wrong diagnosis just gets repeated more reliably.
- Watch next
- Drivers reused across labs; an independent evaluation; autonomy beyond execution.
Interact is an underappreciated layer of AI4S
Generating an experimental plan does not make the experiment happen. Plans must become device instructions, state must be observable and measurements must return in usable form. MHS frames that layer as an infrastructure problem that can be standardized.
Programmability is not the only bottleneck
Many devices are already software-controllable; the problem is that they cannot share state or combine flexibly. Lowering cross-device and agent–device integration cost may matter more than adding another isolated automated instrument.
Execution autonomy is not decision autonomy
An agent can operate equipment with little intervention while humans define the objective, candidate space, success criterion and risk boundary. When a system runs unattended, we should still ask who chose the experiment and how its result changed the next decision.
Model exploration plus deterministic execution may be more practical
QuEra's pattern combines open-ended model exploration with the speed, stability and inspectability demanded by physical control. The model need not remain in the loop forever if it can produce a better deployable control policy.
An automated rerun is not yet scientific Update
Parameter adjustment can close a control loop, but a scientific loop must interpret what the result means and let new evidence change a model, hypothesis or experimental choice. MHS opens the return path; the upstream system still has to learn.
As one imageTo save and share→Sources
Factual claims link to original announcements, project lists, trial records or journal papers where possible. Research plans are kept separate from completed results.