

Paper Brief · Molecular Representation· Evidence · Frontier
Information Can Be Lost Before a Molecule Reaches the Transformer
Wadell and colleagues at the University of Michigan and Carnegie Mellon find that coverage gaps in molecular tokenizers can stay hidden on conventional drug benchmarks, then grow rapidly when rare elements, isotopes and complex stereochemical information combine. Their Smirk closes this gap with 165 base tokens.
◆Peer-reviewed paper + public benchmarks + same-team follow-up preprint
Current boundary: Complete OpenSMILES syntax coverage does not cover 3D conformations or physical environments.
This work advances: Preserves rare elements, isotopes, charge and geometry as molecular strings enter a model
- MODELUnderstand / predict
- DECIDEChoose next
- INTERACTTest against reality
- UPDATEChange next round
165base tokens constructively cover valid OpenSMILES
>28Ttheoretical bracket-atom grammar combinations, not real molecules
Unlike closed atom vocabularies, Smirk emits no [UNK] for valid but rare combinations.
- Belief update
- A model's ceiling starts with what the input preserves: a closed atom vocabulary silently erases rare chemistry.
- Strongest validation
- Measured on REALSpace, MoleculeNet and tmQM; 18 RoBERTa-style encoders pretrained and fine-tuned from scratch.
- Key caveat
- Same-team computation on public benchmarks, not independently replicated; coverage is not an isolated tokenizer gain.
01What happened
- Task
- Audit the step before the Transformer: how much chemistry does each tokenizer keep?
- Approach
- Loss by [UNK] and information lost; Smirk splits bracket atoms.
- Interaction
- Strings and code only: SMILES text; no 3D shape, solvent or intermolecular forces.
- Result
- Smirk-GPE: merges learned on ~262M molecules run out at ~2,300 tokens.
35 / 20tokenizers / chemistry-specific (v3: 34 / 19)
18.9%of the tokens SPE/APE emit on MoleculeNet are [UNK]
≈50%same token share on tmQM
Strong performance on MoleculeNet does not mean a molecular model's tokenizer preserved all input information.
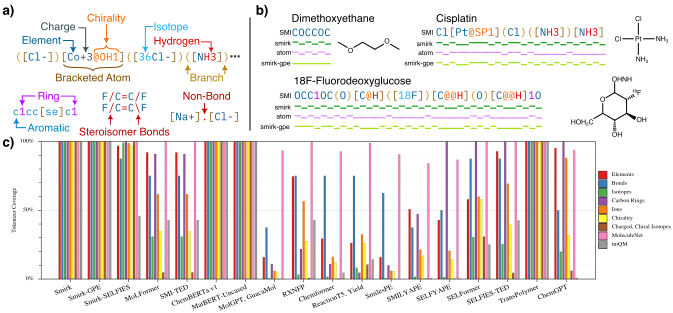
Many chemistry models use atom-wise tokenization, applying regular expressions to split SMILES into atoms and chemical symbols. This usually works for common organic molecules. Blind spots arise mainly in rare combinations of low-frequency elements, isotopes, charge, explicit hydrogen and complex stereochemical information. When the vocabulary lacks a combination, the model may receive only [UNK]. Training does not fail, but the original chemical information is gone, for example in [Au], [Ru], [U], [13CH3], [C@H] and [NH3+].[S1]
OpenSMILES requires brackets for any atom outside the organic subset (B, C, N, O, S, F, Cl, Br, I), and for any atom written with an explicit isotope, chirality, charge, hydrogen count or class. Existing atom-wise tokenizers commonly split SMILES with one widely used regular expression, whose leading pattern treats the whole bracket atom as a single, indivisible token.[S1]
The team evaluated 35 tokenizers, including 20 chemistry-specific tokenizers and general NLP tokenizers such as GPT-4o, LLaMA and Gemma, measuring coverage and information loss across REALSpace, MoleculeNet and tmQM.[S1]
Version note: arXiv v3's abstract and Fig. 2 count 34 / 19 (the n values in Fig. 2 sum to 34); the peer-reviewed abstract updates this to 35 / 20. The paper figures on this page and the sheet are from v3.[S2][S1]
Three measures, three denominators
The paper uses three measures, and they do not mix. One is the [UNK] share of tokens: 18.9% of the tokens SPE/APE emit on MoleculeNet are [UNK], about 50% on tmQM. Another is coverage (Fig. 1c): the proportion of molecules processed without any [UNK]. The third is information loss (Fig. 3): a KL divergence against a reference 5-gram model, in nats per molecule: MoLFormer loses 0.1 on MoleculeNet and 40.3 on tmQM.[S2]
The paper's own example shows the difference: OC[C@@H][OH] is first split into atoms, then into OpenSMILES glyphs. An atom-wise tokenizer stops at the first step and looks up [C@@H] whole. If it is not in the vocabulary, it becomes [UNK]. Smirk takes the second step; every glyph is among its 165 tokens, and the pieces join back into the original string.[S2]
O C [C@@H] [OH] → O C [ C @@ H ] [ O H ]02What changed
Evaluation updateBottleneck updateCommon benchmarks did not fully expose closed vocabularies' coverage gaps; rare valid atoms silently became [UNK].
Coverage becomes a measured property of the input pipeline, one a tokenizer can guarantee by construction.
Why bracket atoms create a combinatorial vocabulary problem
The problem: counting every permutation of isotope, chirality, charge, hydrogen count and class, the OpenSMILES grammar allows more than 28 trillion bracket atoms in theory, while current atom-wise tokenizers have fewer than three thousand tokens. The figure is a ceiling on grammatical combinations, not 28 trillion real, usable molecules, but it is enough to show that a closed atom vocabulary cannot achieve complete coverage.[S1]
[isotope][element][chirality][hydrogen count][charge][class]To address this, the team proposes Smirk, which stops treating a bracket atom as one unit and decomposes it further into the glyphs OpenSMILES defines: [C@@H] becomes [, C, @@, H and ]. The result is a 165-token base vocabulary that covers every valid OpenSMILES expression by construction. It needs no training on a corpus, so there is no closed list of bracket atoms to learn, and a valid but rare combination never becomes [UNK].[S1]
A boundary has to be drawn: the “complete coverage” here is coverage of the OpenSMILES grammar, not of the physical world. SMILES itself cannot adequately express 3D conformations, solvent, environments, intermolecular interactions or dynamics; they sit outside what this coverage guarantee covers, rather than being an open question about tokenizer performance.[S1]
Compressing sequences without recreating the blind spot
Fine-grained decomposition lengthens sequences, increasing Transformer attention cost. Smirk-GPE therefore learns merges over chemical-glyph token IDs. Common combinations compress, while rare combinations fall back to base glyphs without reintroducing [UNK].[S1]
Smirk-GPE was trained on roughly 262 million molecules. Although the target vocabulary was 50,000, usable merges were exhausted at about 2,300 tokens. It is an engineering trade-off among completeness, sequence efficiency and semantic boundaries.[S1]
03Why it matters
What to audit first: what the input pipeline preserves, before parameters, reasoning or autonomy.
- Blind spots sit where rare elements, isotopes, charge and stereo meet: radiopharma, metal catalysts, some battery materials.
- A public leaderboard can miss it: MoleculeNet looks normal while the problem grows sharply on tmQM.
Why MoleculeNet can hide the failure
Common @ / @@ chirality in drug-like molecules is not a universal tokenizer failure. Risk concentrates in combinations of rare elements, isotopes, charge, explicit hydrogen and complex geometry. MoleculeNet mostly reflects conventional medicinal chemistry, so aggregate leaderboards can look normal. tmQM contains more transition-metal complexes and exposes the coverage problem much more strongly.[S1]
The paper gives cisplatin as an example: cisplatin is an effective chemotherapy drug, but its stereoisomer is not. If a representation pipeline erases the information that distinguishes their coordination geometry, the model loses a clinically meaningful difference. Similar risks arise in isotope-labelled radiopharmaceuticals, industrial catalysts and electrolyte materials: the new regimes molecular foundation models are now entering, not the drug-like comfort zone they first relied on.[S1]
The paper also identifies a benchmark limitation: even the relatively diverse tmQM does not cover the full periodic table, all isotopes, charged species or rare structures such as quadruple bonds. If a research direction falls into these blind spots, a public leaderboard may say little about whether the model can read that chemical regime.[S1]
The paper measures silent loss with [UNK] frequency and KL divergence, then pretrains and fine-tunes 18 RoBERTa-style encoders for extrinsic validation. N-gram rankings correlate with downstream rankings at roughly 0.667–0.8 Spearman: useful as a low-cost filter, not a replacement for full training and task evaluation.[S1]
04Evidence status and boundaries
Evidence rung 2 / 5 · Computed · Retrospective computational validationEvidence status
Proven
- Coverage of valid OpenSMILES by construction (a counting result)
- MoLFormer [UNK] loss: 0.1 → 40.3 nats/molecule, MoleculeNet → tmQM
- Code and data are public
Boundaries
Suggested
- Gains clearer on tmQM; may not show on drug-like tasks
- Cheap pre-filter by n-gram (ranks agree ~0.667-0.8)
Unknown
- Tokenizer's own share of MIST gains (all else changed too)
- Where no benchmark reaches: full periodic table, isotopes, charges, quadruple bonds
ClaimCoverage failures grow rapidly with chemical diversity.
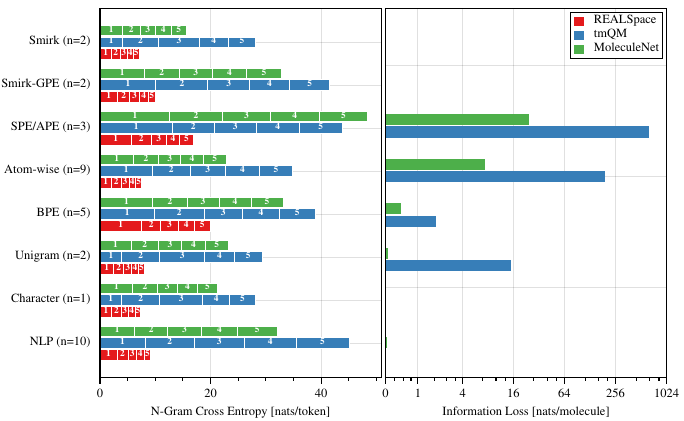
ReadingClosed vocabularies lose far more on tmQM than MoleculeNet; Smirk keeps coverage.
Performance gains are conditional
Smirk is broadly comparable to atom-wise tokenization on MoleculeNet. Its value is clearer in distributions such as tmQM with rarer, more complex chemistry. Conventional drug-like tasks may show little visible gain.[S1]
The SELFIES comparison reveals another boundary
In tmQM, 54% of molecules could not be converted to the evaluated SELFIES representation because of enhanced stereochemistry. String validity, grammar coverage and physical information completeness are three different questions.[S1]
MIST scales Smirk to 1.8B parameters without isolating causality
The later MIST preprint uses Smirk in 28M- and 1.8B-parameter encoders trained on roughly 245 million and 2 billion molecules, then evaluates them through fine-tuning on more than 400 structure–property tasks. This shows that Smirk can operate inside a much larger training pipeline; fine-tuned on tmQM, validation R² rises from 0.76 for MIST-28M to 0.80 for MIST-1.8B.[S3]
MIST changes model scale, training data, compute and fine-tuning setup at the same time, so its gains cannot all be attributed to the tokenizer. It demonstrates scale compatibility and adaptability. Its results across chemical regimes come from task fine-tuning, not zero-shot generalization.[S3]
Peer review strengthens provenance, not physical evidence maturity
Smirk remains retrospective computational and public-benchmark evidence, without wet-lab or physical closed-loop validation. MIST remains a preprint.[S1][S3]
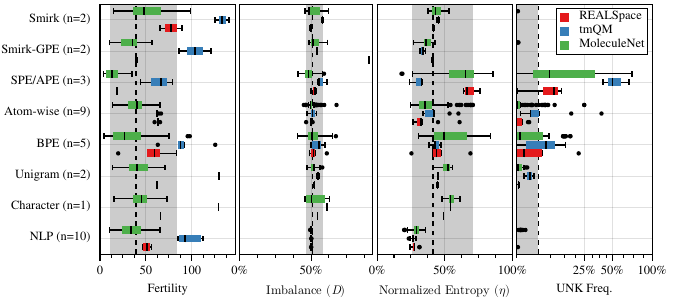
Paper Fig. 2: fertility, imbalance, normalized entropy and [UNK] frequency expose coverage differences across tokenizers and datasets. The figure shows v3's 34 tokenizers; the peer-reviewed version counts 35. Wadell et al., arXiv:2409.15370 (v3). [S2]
05What I learned
- Transferable insight
- Information can be lost before it reaches the Transformer, and training will not flag it.
- Design heuristic
- Decompose into a finite glyph set rather than learn a closed vocabulary, so rare combinations fall back.
- Reading heuristic
- '100% robust' or 'complete coverage': grammar, string validity or physical completeness? Three things.
- Watch next
- Independent replication outside the original team; a test that changes only the tokenizer.
As one imageTo save and share→Sources
This brief is based primarily on the peer-reviewed paper, its corresponding arXiv version, the MIST preprint and the official Smirk repository.