

Paper Note· Evidence · Frontier
SAPP + DMX (Baker Lab): AI Can Design Thousands of Proteins. How Does the Lab Keep Up?
David Baker's team did not build another protein generator. It focused on a more physical AI4S bottleneck: models can produce candidates far faster than laboratories can validate them.
●Peer-reviewed paper + public research materials
Current boundary: it remains an IPD screening workflow, without validation on complex proteins, cross-lab replication or automated next-round selection
This work advances: Moves protein candidates into physical production and standardized measurement faster
- MODELUnderstand / predict
- DECIDEChoose next
- INTERACTTest against reality
- UPDATEChange next round
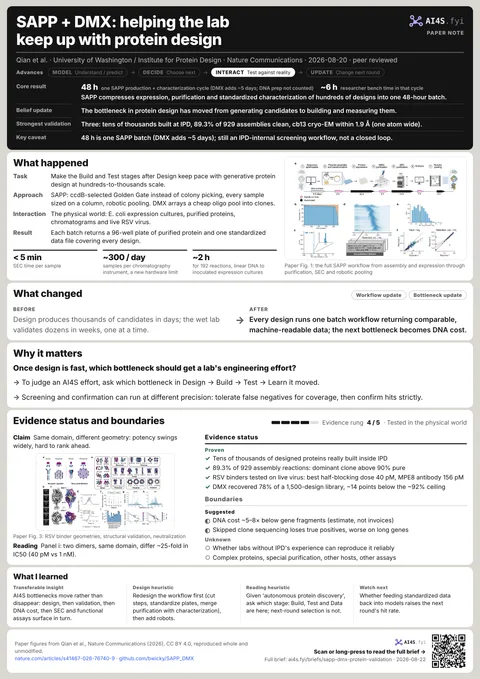
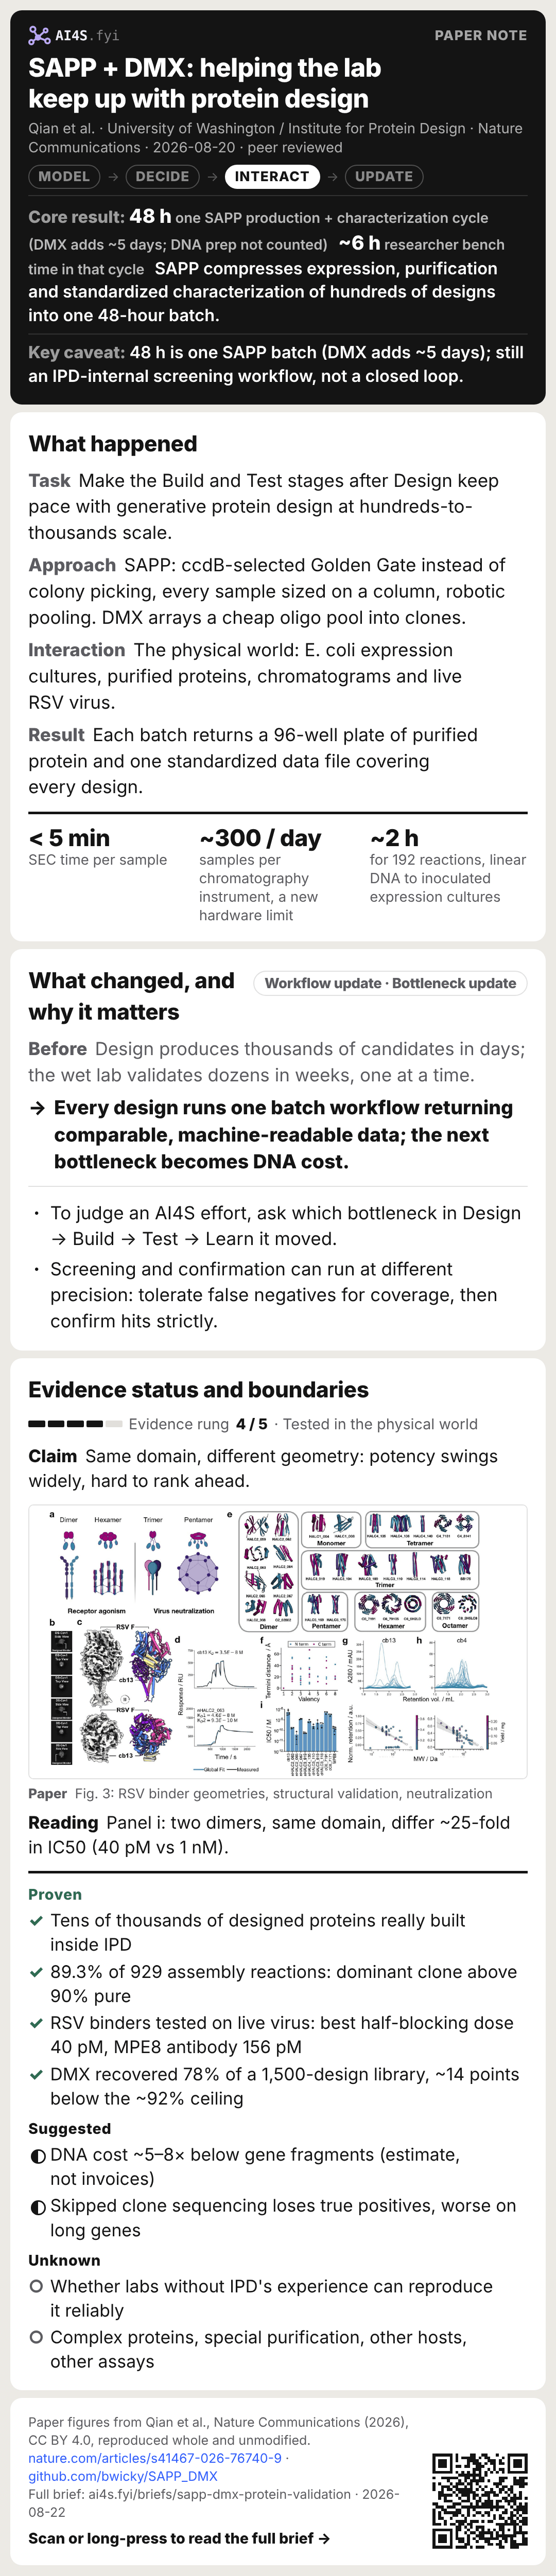
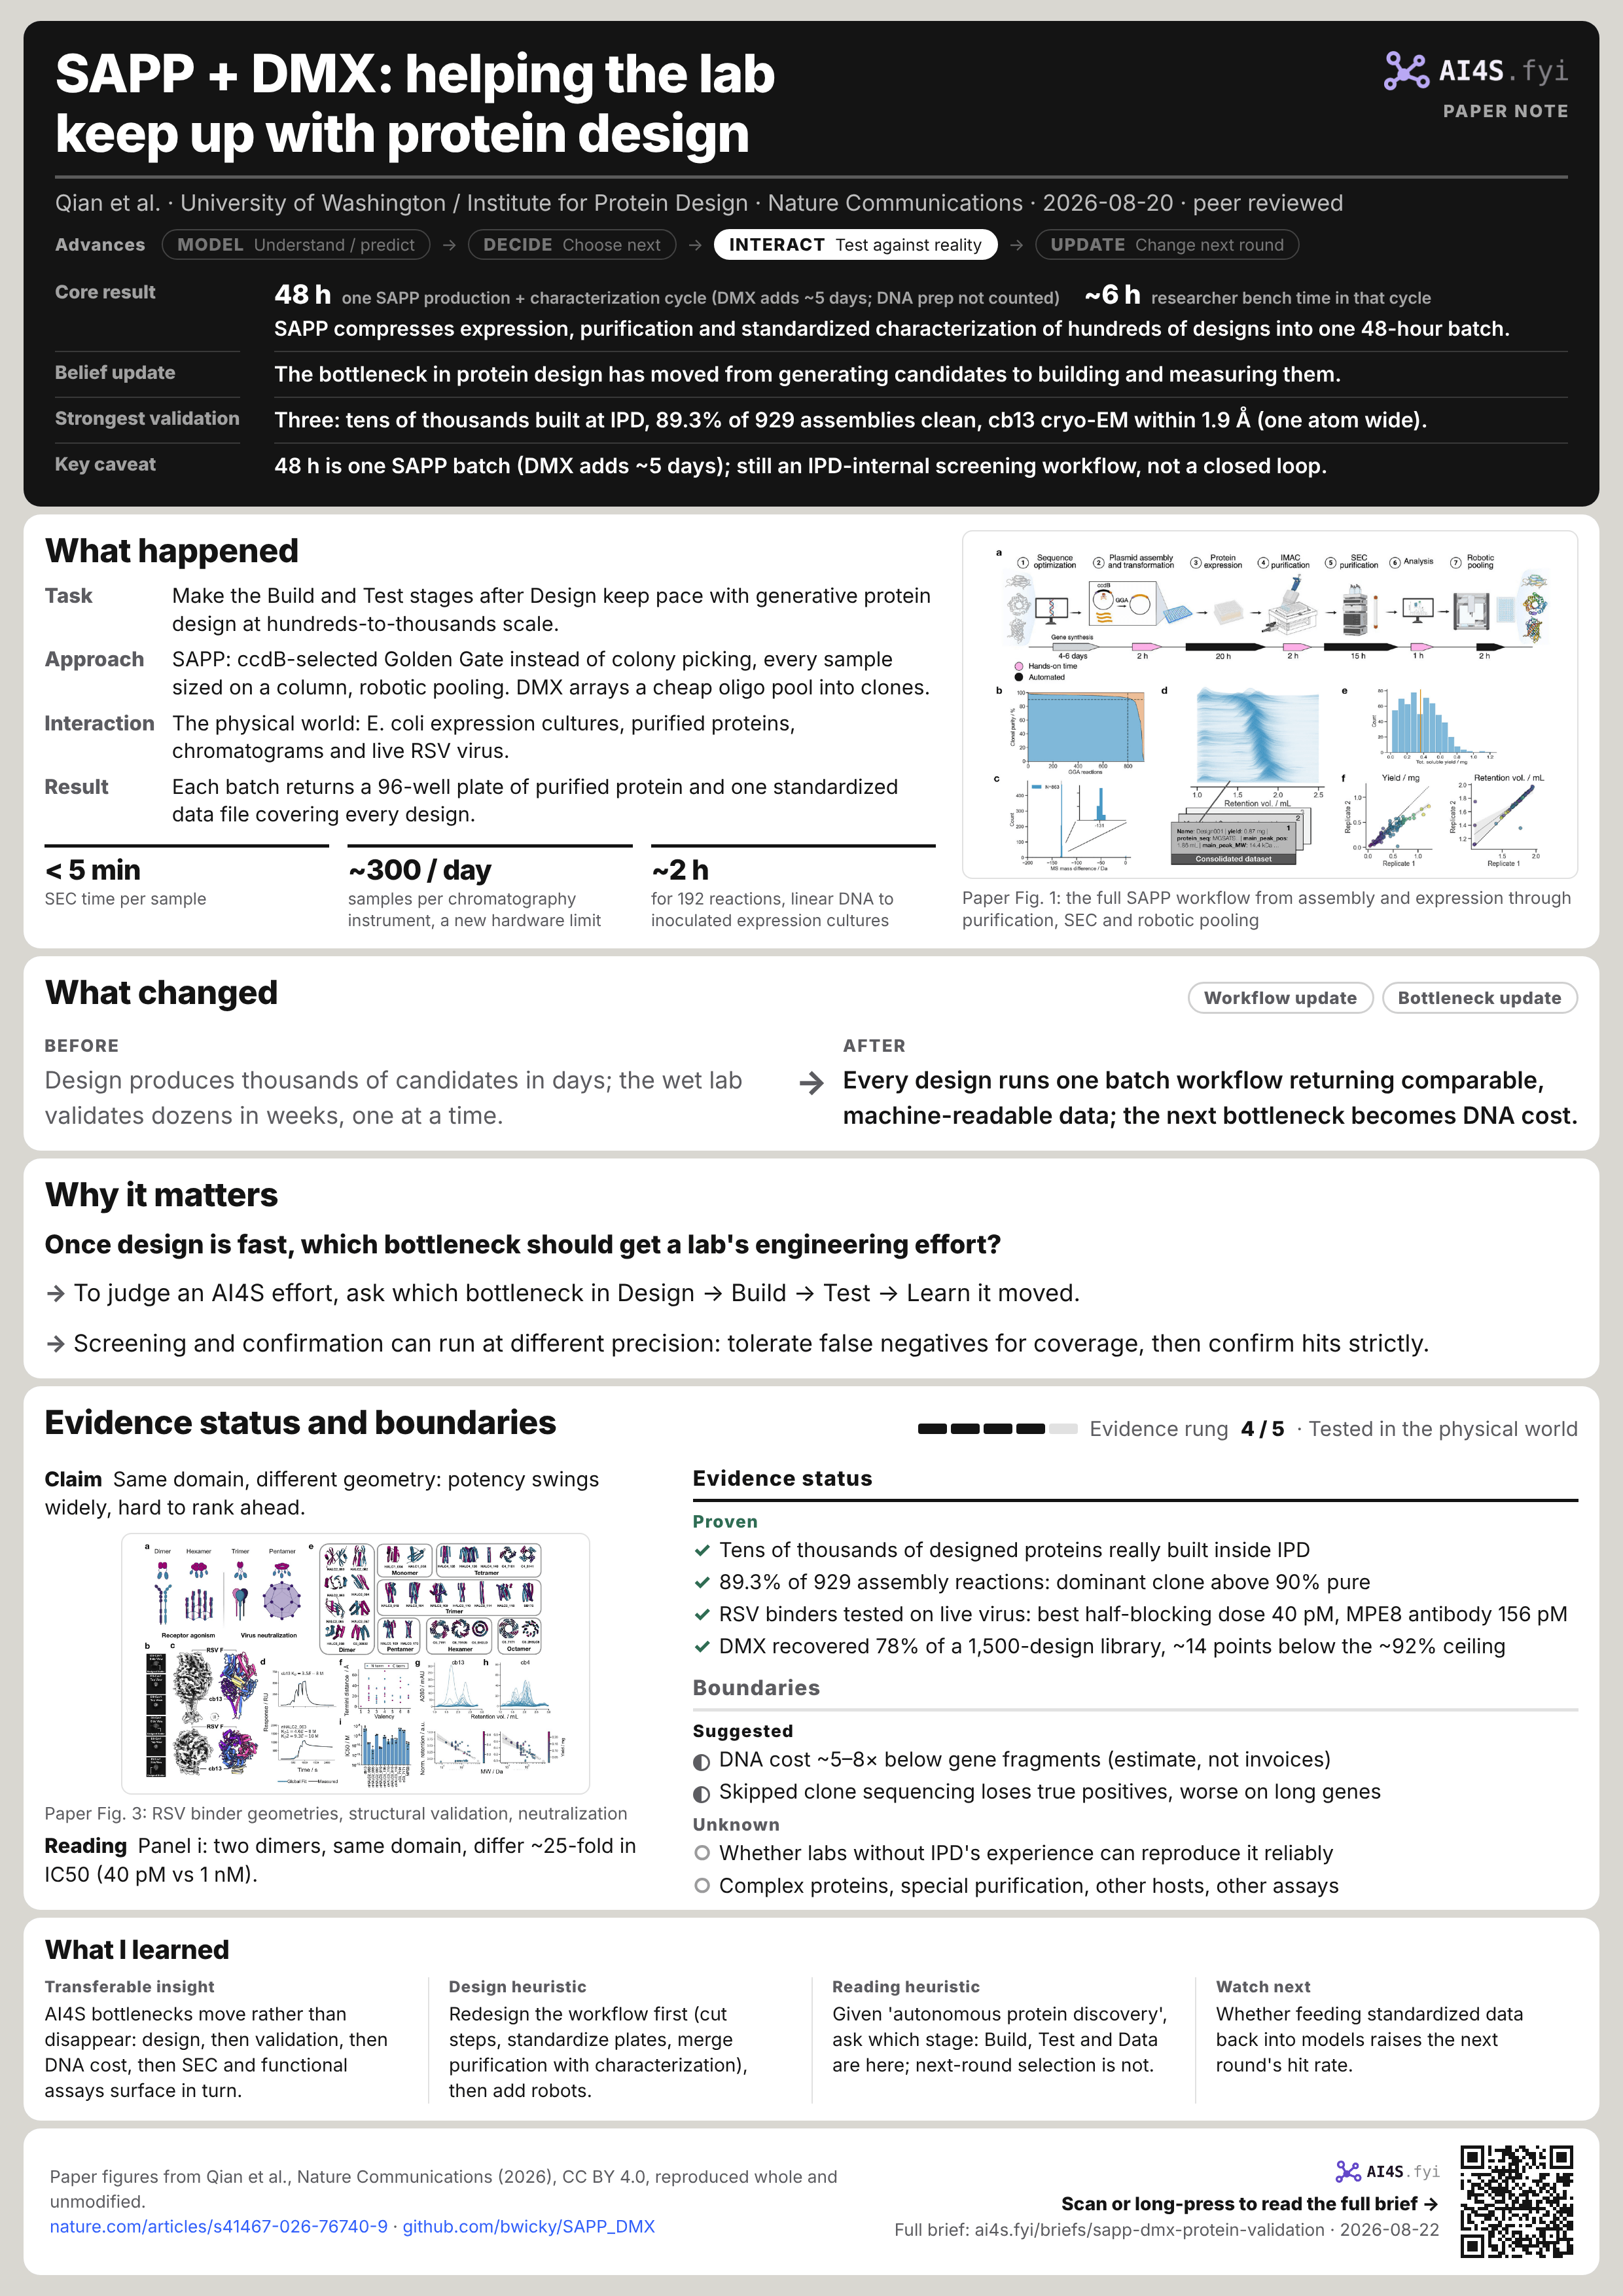
48 hone SAPP production + characterization cycle (DMX adds ~5 days; DNA prep not counted)
~6 hresearcher bench time in that cycle
SAPP compresses expression, purification and standardized characterization of hundreds of designs into one 48-hour batch.
- Belief update
- The bottleneck in protein design has moved from generating candidates to building and measuring them.
- Strongest validation
- Three: tens of thousands built at IPD, 89.3% of 929 assemblies clean, cb13 cryo-EM within 1.9 Å (one atom wide).
- Key caveat
- 48 h is one SAPP batch (DMX adds ~5 days); still an IPD-internal screening workflow, not a closed loop.
01What happened
- Task
- Make the Build and Test stages after Design keep pace with generative protein design at hundreds-to-thousands scale.
- Approach
- SAPP: ccdB-selected Golden Gate instead of colony picking, every sample sized on a column, robotic pooling. DMX arrays a cheap oligo pool into clones.
- Interaction
- The physical world: E. coli expression cultures, purified proteins, chromatograms and live RSV virus.
- Result
- Each batch returns a 96-well plate of purified protein and one standardized data file covering every design.
< 5 minSEC time per sample
~300 / daysamples per chromatography instrument, a new hardware limit
~2 hfor 192 reactions, linear DNA to inoculated expression cultures
On August 20, 2026, David Baker's team published “Accelerating protein design by scaling experimental characterization” in Nature Communications. The work comes mainly from the University of Washington Department of Biochemistry and Institute for Protein Design, with live RSV neutralization experiments performed by collaborators at Karolinska Institutet. It introduces two connected experimental workflows, SAPP and DMX.[S1]
The problem this paper addresses
RFdiffusion and ProteinMPNN can propose thousands of candidates in days; a conventional wet lab may take weeks to express, purify and measure dozens. The faster design becomes, the longer the queue for physical feedback grows. A sequence that looks promising in silico may still express poorly, aggregate or form the wrong oligomeric state.[S1]
Those questions return to the lab. Large pooled assays can screen many sequences, but often read only a small number of properties such as binding or stability and do not reveal whether each individual protein is easy to produce, purify and recover in the intended state.[S1]
Baker's team did not build another design model. It redesigned the Build and Test stages after Design. The paper says SAPP and DMX have already been used inside IPD to produce and characterize tens of thousands of de novo designed proteins. Their job is to let the physical world answer more quickly: which designs actually work?[S1]
SAPP turns protein experiments into a batch workflow
Where the old queue stalled
After DNA assembly, a conventional workflow still transforms, plates, picks a single colony, grows it, prepares plasmid, verifies the sequence and then moves the confirmed construct into an expression strain. This takes days and colony picking is difficult to parallelize at scale.[S1]
Engineering tradeoff
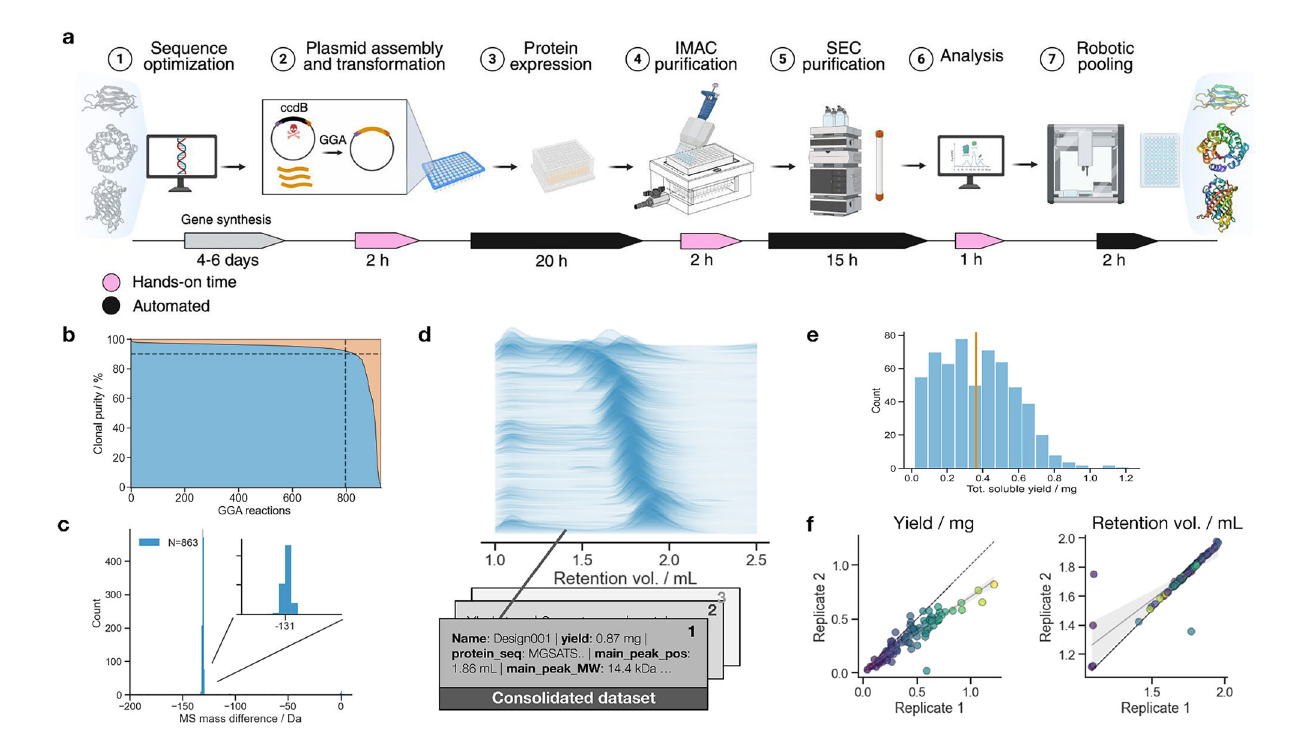
SAPP uses Golden Gate Assembly and places the lethal ccdB gene in the destination vector. A correct insert replaces ccdB, while empty background vector is strongly suppressed. The assembly can therefore enter an E. coli expression strain directly. Moving 192 reactions from linear DNA to inoculated expression cultures takes about two hours.[S1][S4]
Is the shortcut reliable?
The shortcut does not eliminate DNA synthesis and cloning errors. Across 929 assembly reactions, 89.3% had a dominant clone above 90% purity. Mass spectrometry of 863 purified proteins found about 90% within ±1 Da of the expected mass. The intended construct usually dominates enough for screening, at the cost of occasional false negatives. Screening and final validation are designed as separate stages: a faster first pass tolerates some missed positives, while final hits still receive strict clonal and sequence confirmation.[S1]
SEC for every sample turns experiments into a data line
Traditional 96-well screens often stop at SDS-PAGE to see what expressed, then scale up a few candidates. Expression is far from proving that a protein is good. SAPP sends every sample through affinity purification and then directly into size-exclusion chromatography (SEC). SEC is not only purification: each chromatogram reports soluble yield, dispersity, estimated molecular weight, aggregation and oligomeric state. A batch of 192 samples runs overnight in about 15 hours, under five minutes per sample.[S1]
A Python pipeline analyzes chromatograms in batches and generates liquid-handler instructions for fraction pooling and concentration normalization. The output is not only a 96-well plate of purified proteins but also a standardized file containing the results. The full SAPP workflow takes about 48 hours, with roughly six hours of bench work. Every design therefore returns comparable, machine-readable physical data in the same format.[S1][S3]
02What changed
Workflow updateBottleneck updateDesign produces thousands of candidates in days; the wet lab validates dozens in weeks, one at a time.
Every design runs one batch workflow returning comparable, machine-readable data; the next bottleneck becomes DNA cost.
This is the paper's clearest systems story: bottlenecks move. Once protein expression, purification and initial characterization accelerated, DNA synthesis became the dominant cost of large campaigns. Ordering individual gene fragments is convenient, but at hundreds or thousands of designs DNA absorbs most of the budget.[S1]
Oligo pools are much cheaper, but all sequences arrive mixed together. DMX solves this format mismatch: cheap DNA is pooled, while experiments need it arrayed, one known construct per well.[S1][S2]
DMX: one sequence per well, with its identity known
DMX clones a DNA library into a common vector and picks colonies into 384-well plates. Genes in each bacterial lysate receive combinatorial barcodes, are pooled again and sequenced with Nanopore long reads to map barcodes to gene sequences. An automated pipeline outputs a pick list, and a liquid handler re-arrays confirmed colonies into new plates.[S1][S3]
Four sets of 24 barcodes can theoretically identify 24⁴, or 331,776 wells. In a test library of 1,500 designs, the team analyzed 4,608 colonies and recovered 78% of target variants, approaching the roughly 92% theoretical limit at that sampling depth.[S1]
The paper estimates that DNA for a 500-design campaign is about fivefold cheaper than individual gene fragments, and an approximately 2,000-design campaign about eightfold cheaper. The cost is roughly five extra days. SAPP alone is simpler for one or two hundred designs; at thousand-design scale, DMX followed by SAPP becomes more attractive.[S1][S2]
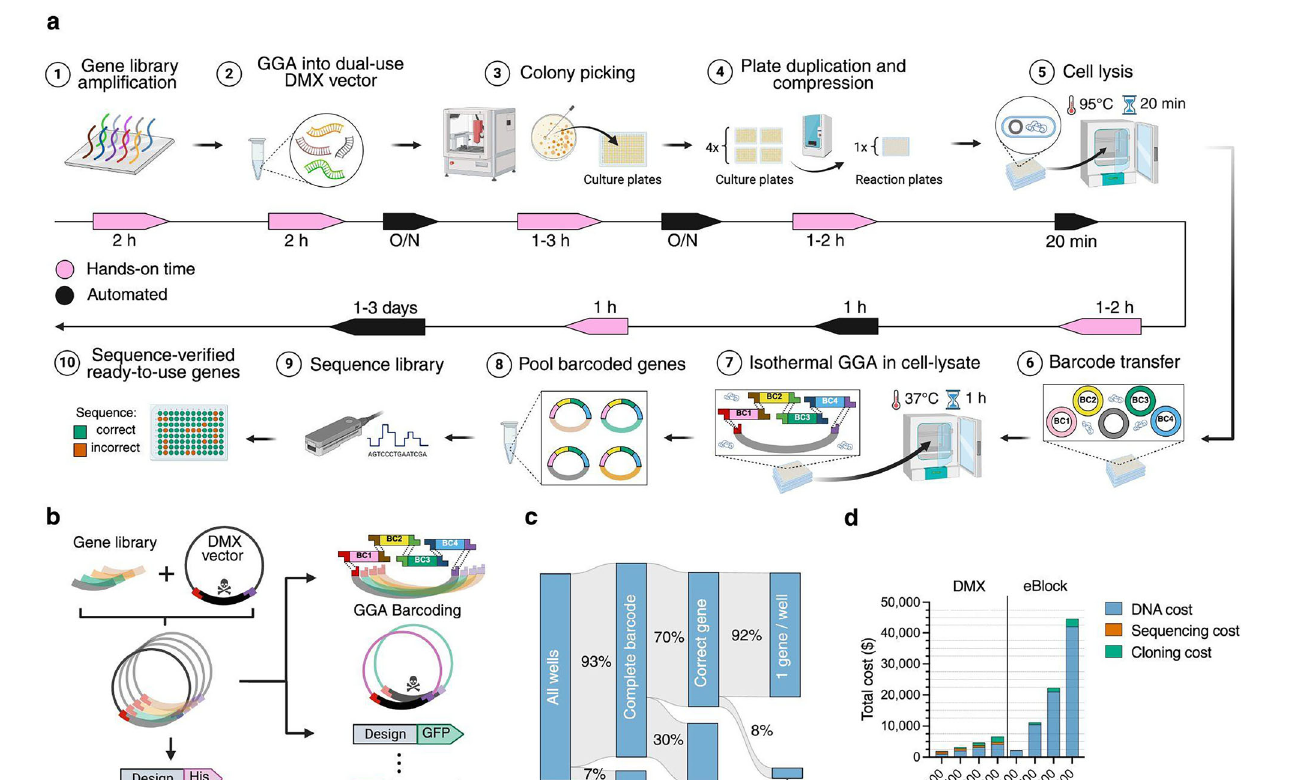
Paper Fig. 4, whole (a–d). Reading focus: follow oligo pool → colony picking → combinatorial barcode → Nanopore mapping to see how DMX returns a mixed pool to an arrayed, sequence-identified clone library. Qian et al., Nature Communications (2026), CC BY 4.0. [S1]
03Why it matters
Once design is fast, which bottleneck should get a lab's engineering effort?
- To judge an AI4S effort, ask which bottleneck in Design → Build → Test → Learn it moved.
- Screening and confirmation can run at different precision: tolerate false negatives for coverage, then confirm hits strictly.
SAPP passes each design through a comparable production and characterization workflow, with soluble yield, dispersity, estimated molecular weight, aggregation and oligomeric state organized into a common data structure. The wet lab can then repeatedly return format-consistent ground truth: models propose candidates, the lab builds and measures them, and the results can feed a future round of model training or active learning.[S1][S3]
SAPP and DMX are experimental infrastructure required for a self-driving protein lab, not a completed self-driving lab. They advance Build, Test and Data, but do not yet automate selection of the next experiments from the previous round's results.[S1]
04Evidence status and boundaries
Evidence rung 4 / 5 · Tested in the physical world · Physical validationEvidence status
Proven
- Tens of thousands of designed proteins really built inside IPD
- 89.3% of 929 assembly reactions: dominant clone above 90% pure
- RSV binders tested on live virus: best half-blocking dose 40 pM, MPE8 antibody 156 pM
- DMX recovered 78% of a 1,500-design library, ~14 points below the ~92% ceiling
Boundaries
Suggested
- DNA cost ~5–8× below gene fragments (estimate, not invoices)
- Skipped clone sequencing loses true positives, worse on long genes
Unknown
- Whether labs without IPD's experience can reproduce it reliably
- Complex proteins, special purification, other hosts, other assays
ClaimSame domain, different geometry: potency swings widely, hard to rank ahead.
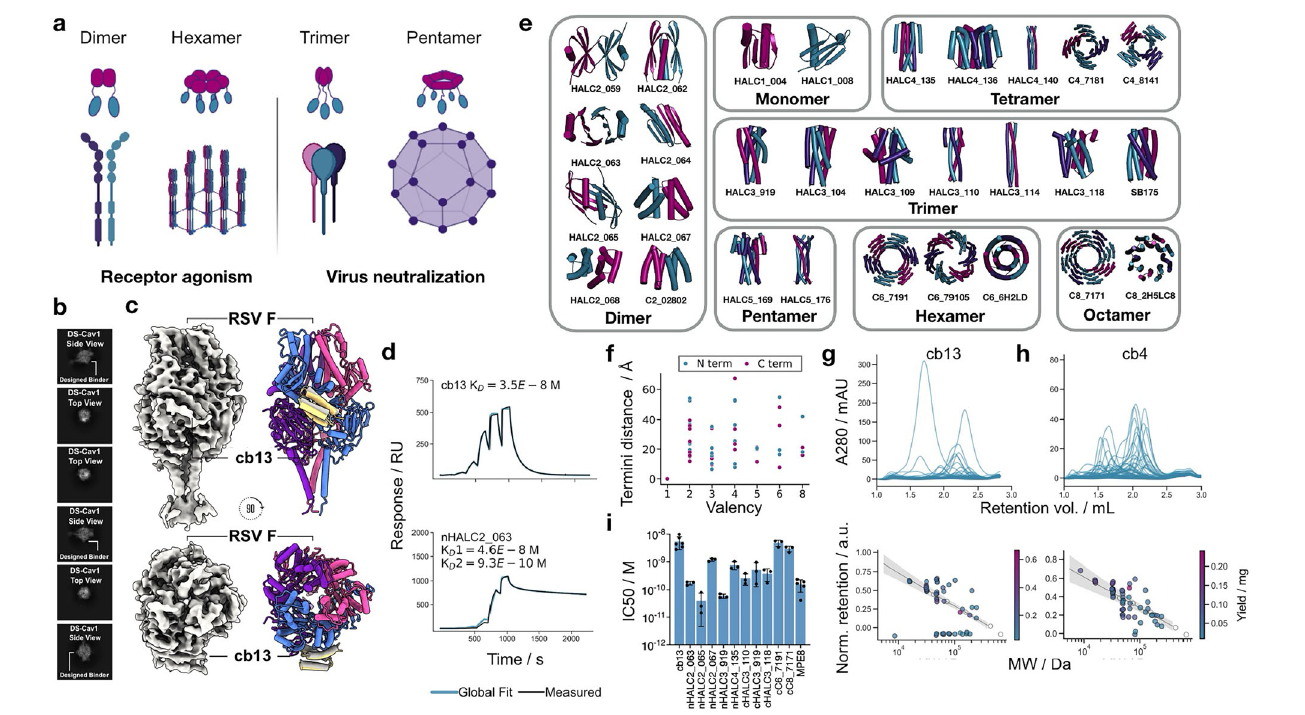
ReadingPanel i: two dimers, same domain, differ ~25-fold in IC50 (40 pM vs 1 nM).
A fluorescent-protein study first showed that SAPP could return comparable data for 96 redesigned constructs within a week. Some variants shared only 50–80% sequence identity with the wild type yet remained monomeric and retained absorbance after one hour at 95°C; others showed clear shifts in emission spectra.[S1]
The RSV study makes the case most clearly. The team screened about 31,000 minibinders targeting site III of RSV F, identified cb13 at 35 nM affinity and found by cryo-EM that the observed complex closely matched the design, with a binder-backbone Cα RMSD of 1.9 Å. They then placed cb13 on 27 oligomerization scaffolds to make 58 constructs. SAPP selected 19 with suitable expression and assembly for live-virus neutralization.[S1][S5]
The best two constructs reached IC50 values of 40 pM (nHALC2_065) and 59 pM (nHALC3_919), compared with 5.4 nM for monomeric cb13 and 156 pM for the MPE8 antibody control. The failures and branches are more informative: two dimers with the same binding domain (nHALC2_065 vs nHALC2_067) differed by about 25-fold (40 pM vs 1 nM); on the same trimerization scaffold, moving the binding domain from the N to C terminus changed potency by about tenfold (59 pM vs 530 pM); and C6 or C8 architectures did not automatically improve activity. With throughput, researchers need not validate only a model's top few candidates; they can systematically compare geometries that are still hard to rank in advance.[S1]
A peer-reviewed methods paper, not proof of a complete closed loop
The paper provides workflows, scale measurements, case studies and public code, while experimental-data-informed design models and active learning remain future directions. It supports progress in experimental infrastructure, not a claim that autonomous protein discovery is already closed-loop.[S1][S3]
Screening, not final gold-standard validation
Skipping single-clone sequencing creates false negatives, and polyclonality from DNA synthesis errors becomes more pronounced as genes get longer. Final hits still require strict clonal and sequence confirmation.[S1]
Applicability remains bounded
The workflow is optimized for engineered or designed proteins that express at useful levels. Proteins requiring complex expression conditions, special purification, other hosts or application-specific functional assays do not fit directly. Whether labs without IPD's accumulated experience can reproduce it reliably also remains to be shown.[S1]
05What I learned
- Transferable insight
- AI4S bottlenecks move rather than disappear: design, then validation, then DNA cost, then SEC and functional assays surface in turn.
- Design heuristic
- Redesign the workflow first (cut steps, standardize plates, merge purification with characterization), then add robots.
- Reading heuristic
- Given 'autonomous protein discovery', ask which stage: Build, Test and Data are here; next-round selection is not.
- Watch next
- Whether feeding standardized data back into models raises the next round's hit rate.
AI4S bottlenecks move; they do not disappear
The most memorable result is not 48 hours or 40 pM, but a systems rule. Faster design exposes wet-lab validation; faster validation exposes DNA cost; cheaper DNA then exposes SEC, functional assays and harder expression systems. When evaluating an AI4S model or company, a useful question is: which bottleneck in Design → Build → Test → Learn did it move?
Screening and final validation need not use the same precision standard
SAPP accepts some false negatives to cover more design space, then strictly confirms final hits. Using different precision for screening and confirmation avoids being exhausted by cost and time in the first round.
Good lab automation redesigns the workflow before adding robots
SAPP's largest gains come from removing steps that do not scale, standardizing plate formats, reducing intervention with auto-induction and combining purification with characterization. Robots take over repetitive work such as pooling and normalization. Lab automation does not mean robots everywhere; process design is often the first lever.
Throughput changes which questions can be asked
In the RSV study, the same binder at the same valency differed by 25-fold when geometry changed. With only three or five constructs, systematic exploration is difficult. At dozens or hundreds, questions once left to intuition become experimentally searchable.
Closed-loop AI needs standardized physical data, not only faster experiments
If researchers must still inspect every image manually and each project uses a different format, faster experiments do not create a learning flywheel. SAPP organizes each design's result into a common structure; design, Build, Test and Learn can connect only when the wet lab repeatedly returns this kind of ground-truth data at low cost.
As one imageTo save and share→Sources
Factual claims link to original announcements, project lists, trial records or journal papers where possible. Research plans are kept separate from completed results.