

Model & Data Release· Evidence · Frontier
OpenBind-0 Is Fully Open, and Points to the Data Gaps That Actually Matter
OpenBind-0, released by the OpenBind Consortium with ASAP Discovery and Syngenta, matters for more than being fully open. Real drug-discovery projects expose a deeper problem: more data does not automatically produce a stronger model unless it fills the regions the model does not understand.
●Official model and data release + public benchmark evaluation
Current boundary: results come from the official evaluation rather than a peer-reviewed paper, and performance remains low on FatA and both RdRp targets
This work advances: Uses new structures to test data gaps in molecular-interaction models
- MODELUnderstand / predict
- DECIDEChoose next
- INTERACTTest against reality
- UPDATEChange next round
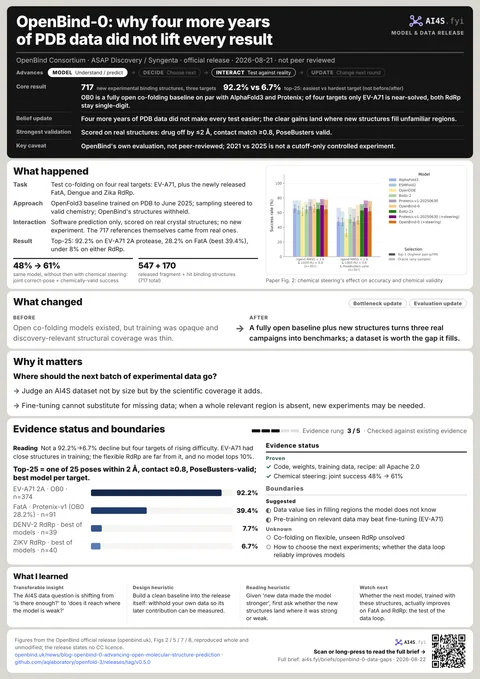
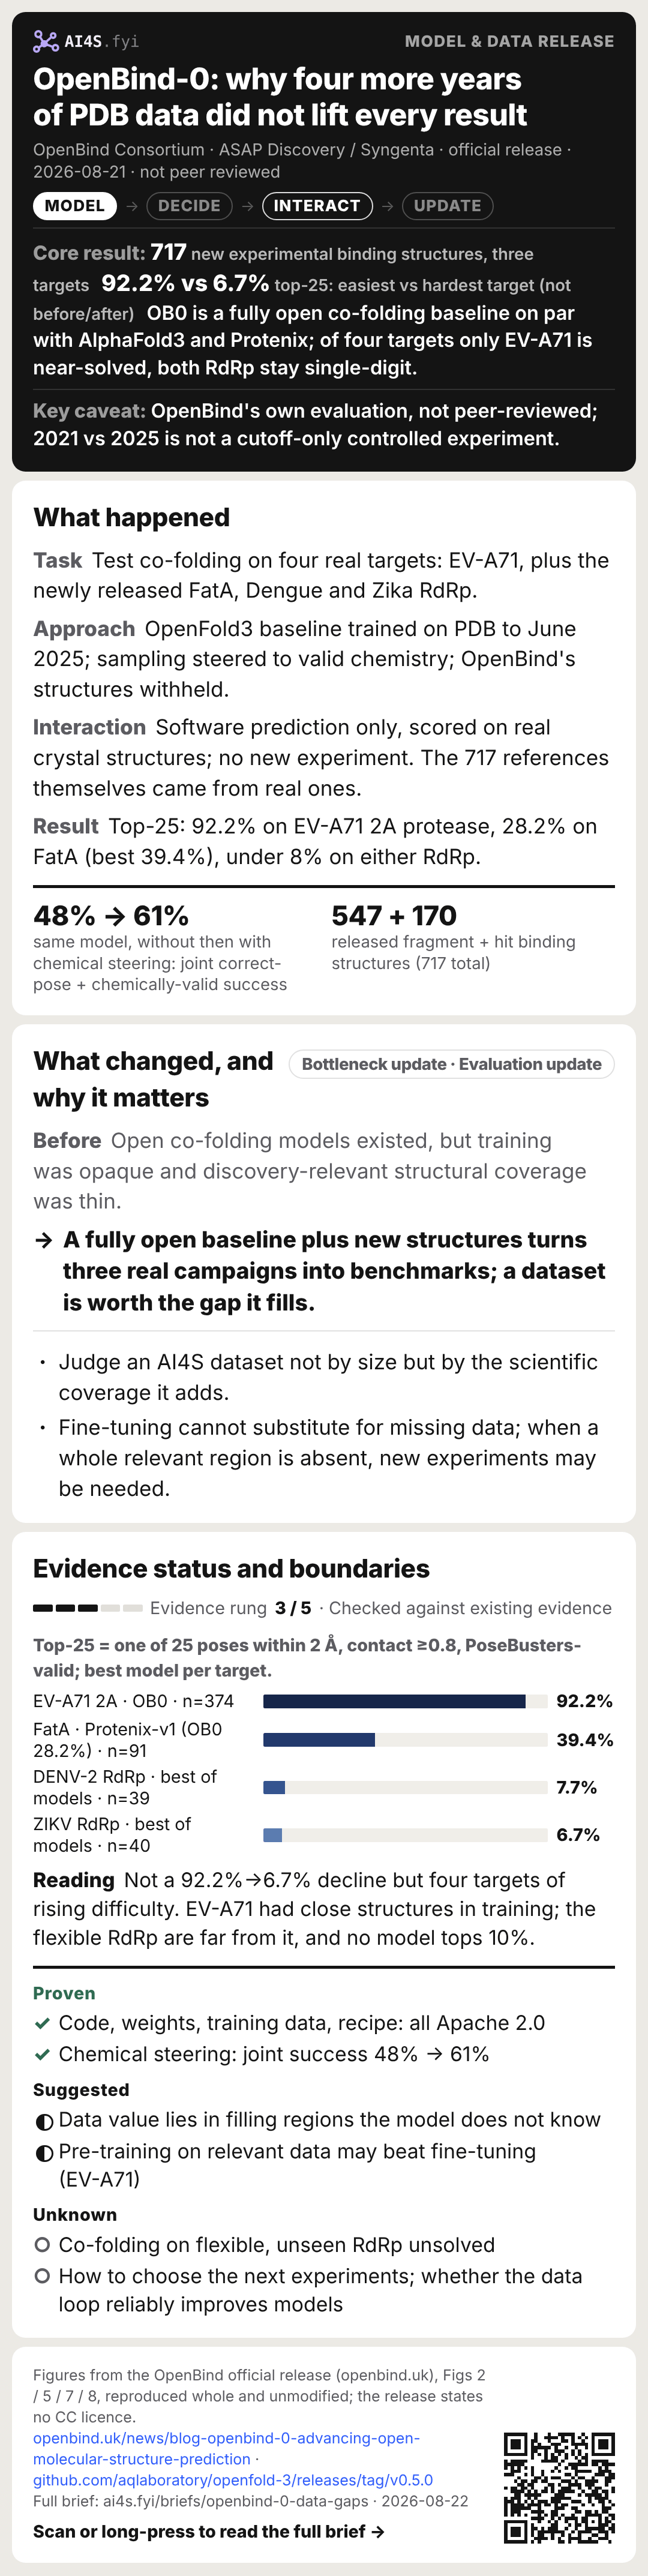
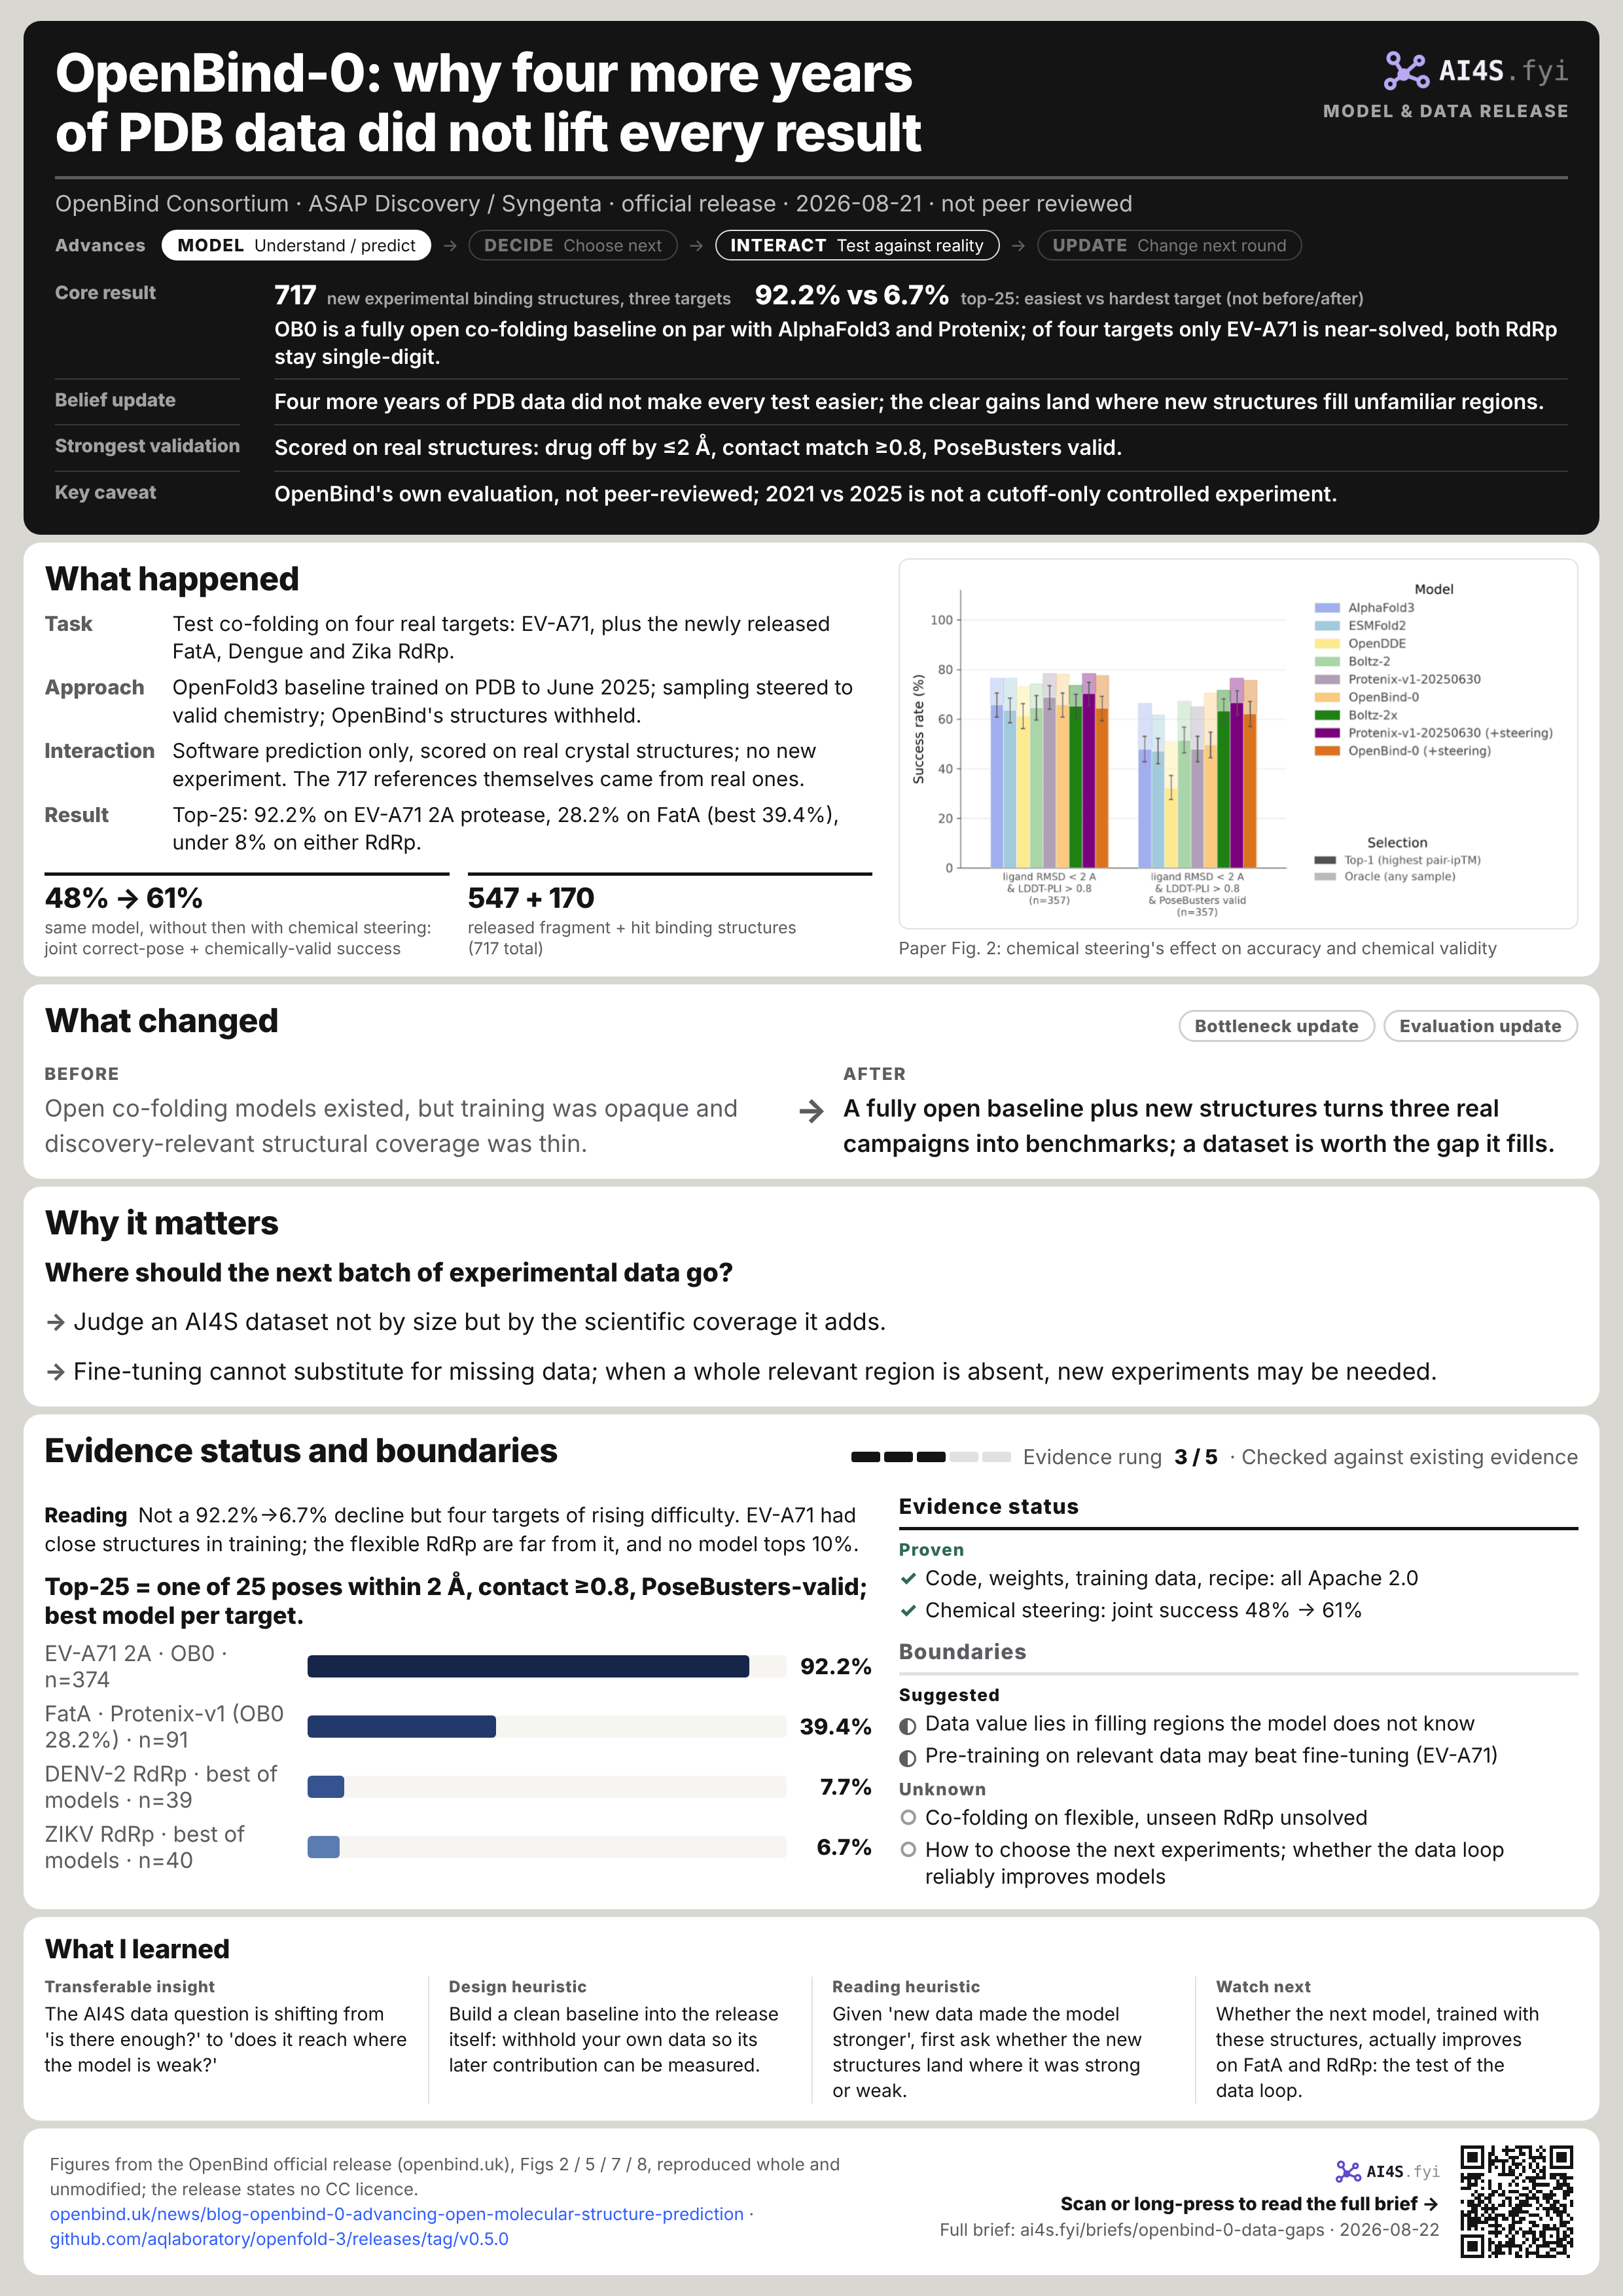
717new experimental binding structures, three targets
92.2% vs 6.7%top-25: easiest vs hardest target (not before/after)
OB0 is a fully open co-folding baseline on par with AlphaFold3 and Protenix; of four targets only EV-A71 is near-solved, both RdRp stay single-digit.
- Belief update
- Four more years of PDB data did not make every test easier; the clear gains land where new structures fill unfamiliar regions.
- Strongest validation
- Scored on real structures: drug off by ≤2 Å, contact match ≥0.8, PoseBusters valid.
- Key caveat
- OpenBind's own evaluation, not peer-reviewed; 2021 vs 2025 is not a cutoff-only controlled experiment.
01What happened
- Task
- Test co-folding on four real targets: EV-A71, plus the newly released FatA, Dengue and Zika RdRp.
- Approach
- OpenFold3 baseline trained on PDB to June 2025; sampling steered to valid chemistry; OpenBind's structures withheld.
- Interaction
- Software prediction only, scored on real crystal structures; no new experiment. The 717 references themselves came from real ones.
- Result
- Top-25: 92.2% on EV-A71 2A protease, 28.2% on FatA (best 39.4%), under 8% on either RdRp.
48% → 61%same model, without then with chemical steering: joint correct-pose + chemically-valid success
547 + 170released fragment + hit binding structures (717 total)
On August 21, 2026, OpenBind released its first molecular structure prediction model, OpenBind-0 (OB0). Built on OpenFold3 and specialized for protein–small-molecule co-folding, it was trained on public PDB structures through June 2025.[S1]
The release also includes 717 new ligand-bound experimental structures from three real fragment-to-hit projects: FatA, Dengue virus RdRp and Zika virus RdRp. They comprise 547 fragment binding events and 170 hit binding events.[S1][S3]
Why the zero matters
OB0 deliberately excludes OpenBind-generated structures from training. It establishes a public-data-only baseline so that future models can measure how much improvement actually comes from OpenBind's experimental data.[S1]
OpenBind-0 uses the Apache 2.0 license and releases training data, code, model weights and training recipes. Users can do more than run inference: they can retrain the model or experiment with proprietary data mixed into the original training distribution.[S1][S2]
A correct position is not enough; the molecule must also be chemically valid
A co-folding model may place a ligand in roughly the correct pose while producing unrealistic bond lengths, angles or local geometry. RMSD alone can count such a structure as correct, but chemically invalid geometry undermines free-energy calculations and medicinal-chemistry decisions.[S1]
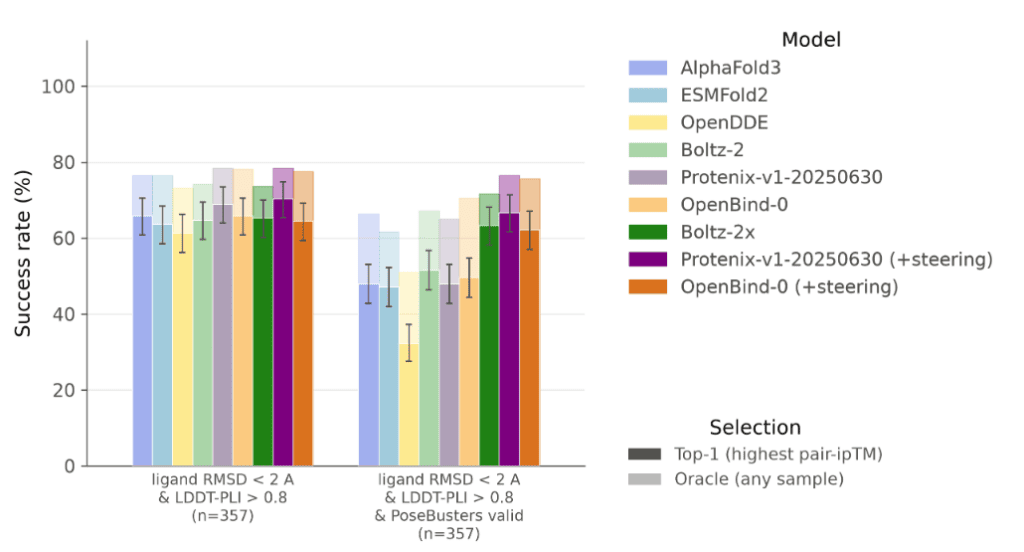
OpenBind adds inference-time chemical steering during diffusion sampling and uses PoseBusters to check ligand validity. The joint success rate for both correct pose and chemically valid geometry rises from 48% to 61%.[S1]
OpenBind blog Fig. 2: chemical steering leaves pose accuracy broadly similar while increasing the share that is both structurally correct and chemically valid.[S1]
02What changed
Bottleneck updateEvaluation updateOpen co-folding models existed, but training was opaque and discovery-relevant structural coverage was thin.
A fully open baseline plus new structures turns three real campaigns into benchmarks; a dataset is worth the gap it fills.
For a scientific foundation model, architecture is only part of the story. Data provenance, cutoff dates, modality mixtures, checkpoint selection and whether fine-tuning preserves the original distribution all affect behavior. Opening these components makes OB0 a baseline that can be studied and modified rather than a black-box service.[S1][S2]
Why four more years of PDB data did not improve everything
OB0's training cutoff is June 2025, while OpenFold3-preview2 stops in 2021. Intuitively, nearly four additional years of PDB data should make every test case easier. In practice, the two models perform similarly across many train-set-similarity bins.[S1]
The team then examined each test complex's distance to its nearest training structure. PDB added many protein–ligand structures, yet for many test cases the nearest neighbor did not become meaningfully closer. The dataset grew, but those targets did not become more familiar to the model.[S1]
Clear gains appear mainly when new data actually change a target's position in the training distribution: when a previously unfamiliar structure becomes more in-distribution. Data value therefore cannot be measured only by structure count; the key question is which chemical and structural space it fills.[S1]
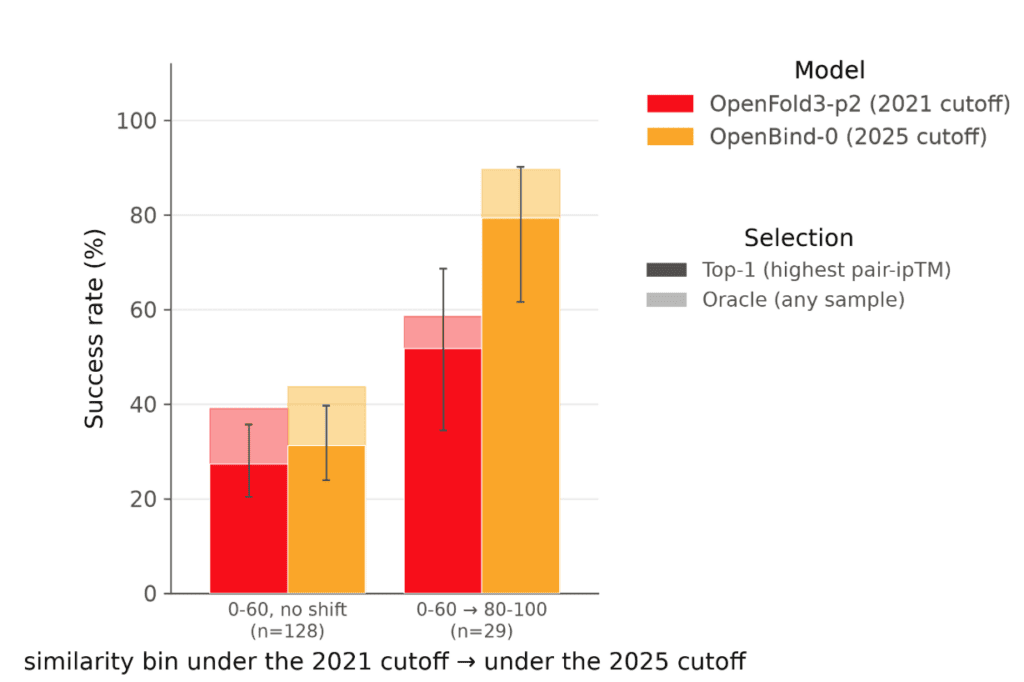
OpenBind blog Fig. 5: the x-axis measures whether 2025 data made a target closer to the training distribution than 2021 data. Gains are clearer when the new structures fill a relevant gap. Image from the OpenBind release. [S1]
03Why it matters
Where should the next batch of experimental data go?
- Judge an AI4S dataset not by size but by the scientific coverage it adds.
- Fine-tuning cannot substitute for missing data; when a whole relevant region is absent, new experiments may be needed.
OpenBind-0 would already be useful as another fully open co-folding model, but its deeper value is the data loop. OB0 deliberately excludes OpenBind's own data to create a clean baseline; the team can then find failure regions and decide which new structures are most valuable to generate experimentally.[S1]
OpenBind explicitly says model predictions are helping determine which experiments to run next. SAPP/DMX works on the neighbouring problem: OpenBind asks which data experiments should add, SAPP/DMX asks how experiments can return data faster.[S1]
Can fine-tuning close the gap? It depends on the target
The team fine-tuned models on target-specific fragment structures. On EV-A71, related data had clearly improved OpenFold3-preview2; OB0 then surpassed the fine-tuned model after absorbing those fragments into pre-training. In this system, incorporating relevant data into pre-training may be more effective.[S1]
The result does not generalize. FatA improves only modestly, and both RdRp systems remain poor after fine-tuning. The careful conclusion is not that pre-training always beats fine-tuning, but that training tricks may not substitute for missing experimental coverage.[S1]
04Evidence status and boundaries
Evidence rung 3 / 5 · Checked against existing evidence · Physical validationEvidence status
Proven
- Code, weights, training data, recipe: all Apache 2.0
- Chemical steering: joint success 48% → 61%
Boundaries
Suggested
- Data value lies in filling regions the model does not know
- Pre-training on relevant data may beat fine-tuning (EV-A71)
Unknown
- Co-folding on flexible, unseen RdRp unsolved
- How to choose the next experiments; whether the data loop reliably improves models
Top-25 = one of 25 poses within 2 Å, contact ≥0.8, PoseBusters-valid; best model per target.
ReadingNot a 92.2%→6.7% decline but four targets of rising difficulty. EV-A71 had close structures in training; the flexible RdRp are far from it, and no model tops 10%.
Evidence form
OpenBind-0 is currently a model and data release with official benchmark analysis, not a full peer-reviewed paper. The performance numbers here come from OpenBind's release and accompanying evaluation.[S1][S3]
What 92.2% means
It is not a general drug-binding prediction accuracy. Each binding event receives 25 structures; top-25 success means at least one satisfies ligand RMSD ≤2 Å, LDDT-PLI ≥0.8 and PoseBusters validity checks.[S1]
Three real projects, three failure modes
EV-A71 reaches 92.2%, FatA 28.2%, and the best models on both RdRp targets remain below 8% (the best top-25 is 7.7% on DENV-2 RdRp and 6.7% on ZIKV RdRp, every model scored on the same real structures). EV-A71 has relatively good coverage; on FatA models usually find the pocket but miss the ligand pose; on RdRp they often choose the wrong pocket, with receptor conformation and pose wrong as well.[S1][S4][S5]
OpenBind evaluates models on real fragment-to-hit campaigns. On EV-A71 2A protease, OB0 reaches 92.2% top-25 success and 73.8% top-1. Related fragment structures were already in PDB before OB0's cutoff, giving the model highly relevant structural information.[S1]
On FatA, OB0 falls to 28.2% top-25 success; the best model, Protenix-v1-20250630, reaches only 39.4%. Models usually identify the correct pocket and a reasonable protein conformation but often miss the ligand pose. The failure is not where the ligand should go, but how it should sit there.[S1][S4]
On Dengue and Zika RdRp, nearly every model fails. RdRp is large, has multiple surface pockets and is highly flexible around the primary site; both systems are also very dissimilar to known structures in the 2021 and 2025 training sets.[S1][S5]
Comparison boundary
The 2021-versus-2025 comparison is not a perfectly controlled data-cutoff experiment. OpenFold3-preview2 and OB0 are architecturally similar but not identical, a limitation OpenBind also notes.[S1]
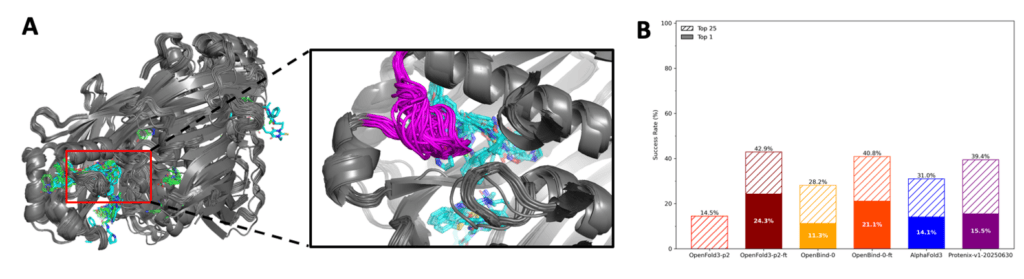
OpenBind blog Fig. 7: models often find the FatA pocket, while ligand pose remains the main problem; OB0 top-25 is 28.2%. Image from the OpenBind release. [S1]
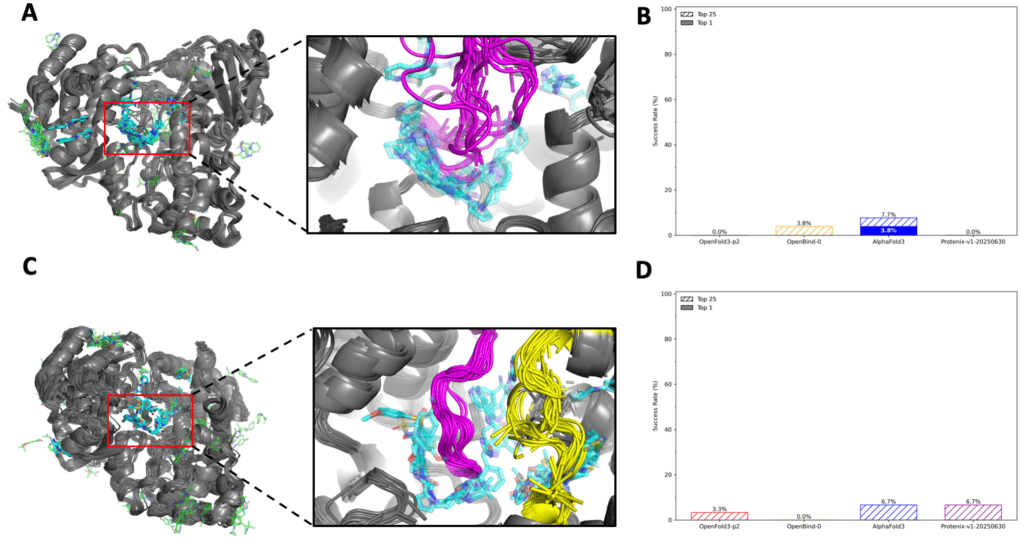
OpenBind blog Fig. 8: on Dengue and Zika RdRp, no model reaches 10% top-25 success (best 7.7% / 6.7%). Image from the OpenBind release. [S1]
05What I learned
- Transferable insight
- The AI4S data question is shifting from 'is there enough?' to 'does it reach where the model is weak?'
- Design heuristic
- Build a clean baseline into the release itself: withhold your own data so its later contribution can be measured.
- Reading heuristic
- Given 'new data made the model stronger', first ask whether the new structures land where it was strong or weak.
- Watch next
- Whether the next model, trained with these structures, actually improves on FatA and RdRp: the test of the data loop.
1 | The data question is shifting from quantity to coverage
Four additional years of PDB data did not make every test case easier. If new structures sit inside regions the model already knows, their marginal value for difficult targets may be low. Beyond size, an AI4S dataset should be judged by the scientific coverage it adds.
2 | Failure modes matter more than an average score
EV-A71, FatA and RdRp are all protein–ligand prediction problems, yet fail differently: good coverage, incorrect ligand placement, or even wrong-pocket selection. Knowing that a model failed is not enough; the useful question is why and where the next experimental budget should go.
3 | Fine-tuning is not a universal patch for missing data
The same fine-tuning strategy ranges from useful to nearly ineffective across systems. If an entire structural region is missing, a few dozen target-specific examples may not repair the gap; new experiments may matter more.
4 | Full openness makes the data–model relationship researchable
Weights alone let us compare predictions. Opening training data, recipes, code and weights makes deeper questions testable: which data are valuable, where should they enter training, and what does a particular mixture improve or damage?
5 | The hardest part of self-driving science may be choosing the next experiment
Valuable active learning is not merely choosing 100 candidates from 10,000. It asks whether those 100 experiments maximally reduce important uncertainty or fill the most consequential gap in the training distribution. A system that repeatedly answers which data to generate next may matter more than any single model or dataset.
As one imageTo save and share→Sources
Factual claims link to original announcements, project lists, trial records or journal papers where possible. Research plans are kept separate from completed results.
- S1OpenBind-0: Advancing Open Molecular Structure PredictionOpenBind · 2026.08.21 · Official model, data and benchmark release
- S2OpenFold3 v0.5.0 / OpenBind-0 model releaseAQLaboratory / GitHub · 2026.08.21 · Code and model weights
- S3OpenBind-0 model release infoOpenBind Consortium / GitHub · 2026.08.21 · Evaluation scripts and data documentation
- S4FatA fragment-to-hit dataFragalysis / OpenBind · 2026.08.21 · Experimental structure data
- S5DENV-2 and ZIKV RdRp fragment-to-hit dataFragalysis / OpenBind · 2026.08.21 · Experimental structure data