

Paper & System· Evidence · Frontier
How Does a Chemistry PDF Become Data an AI Can Use?
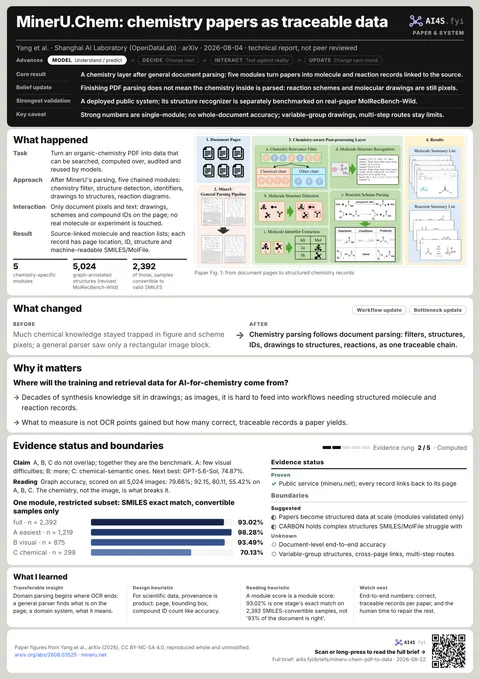
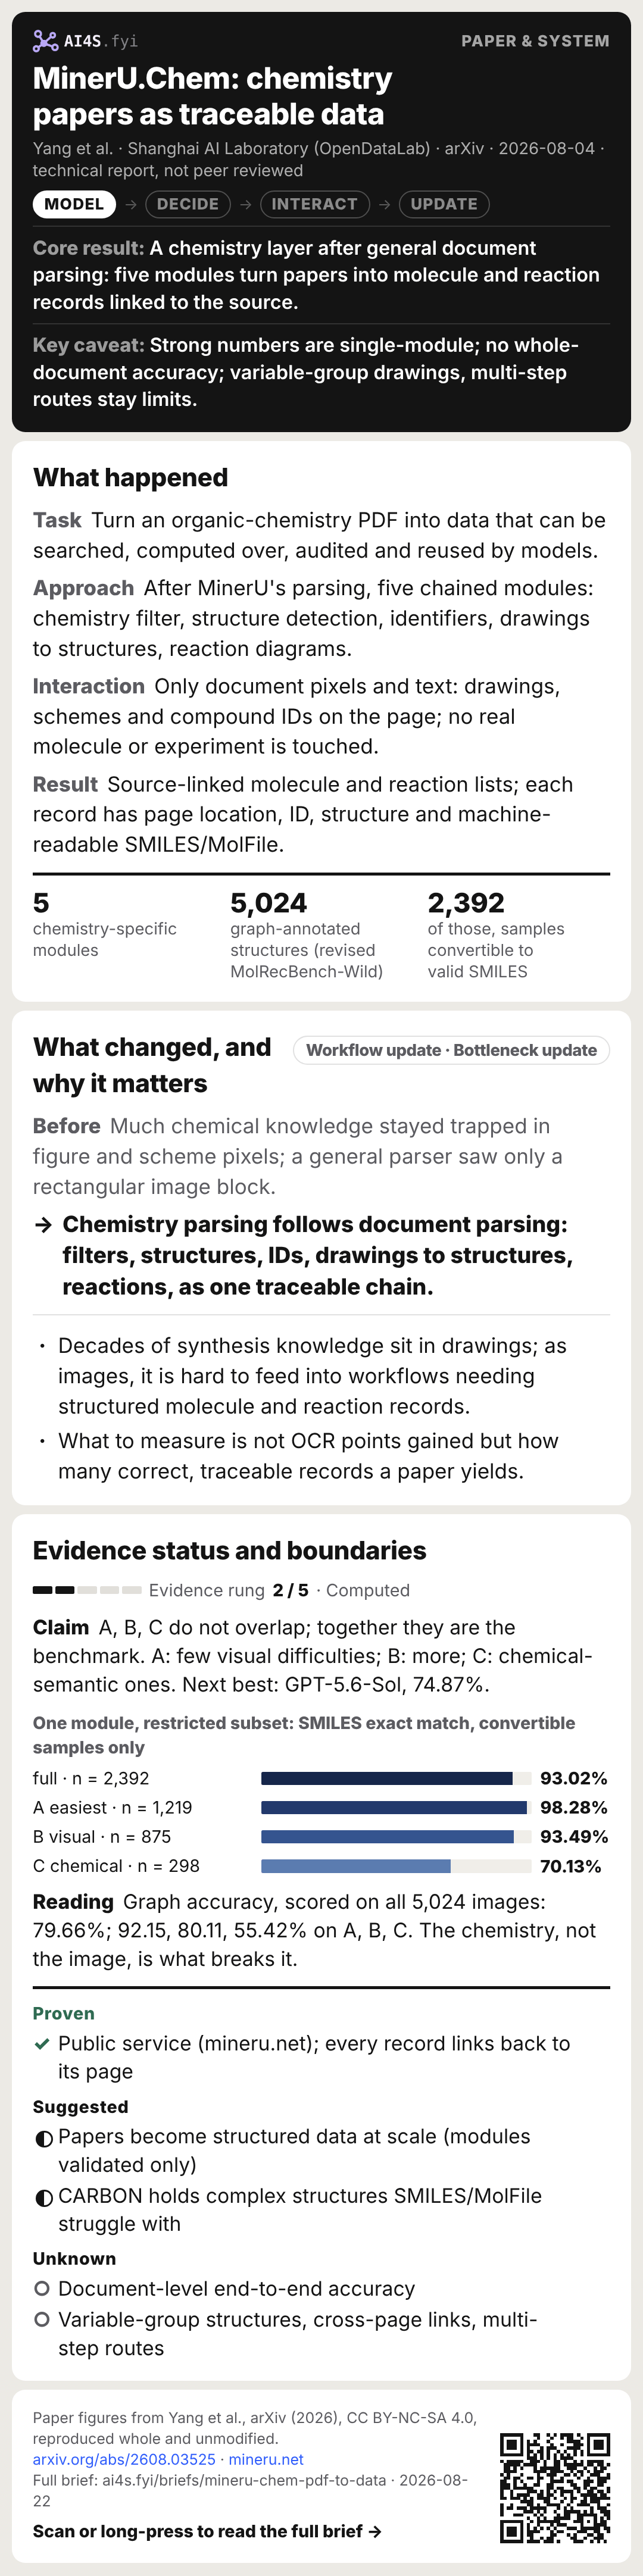
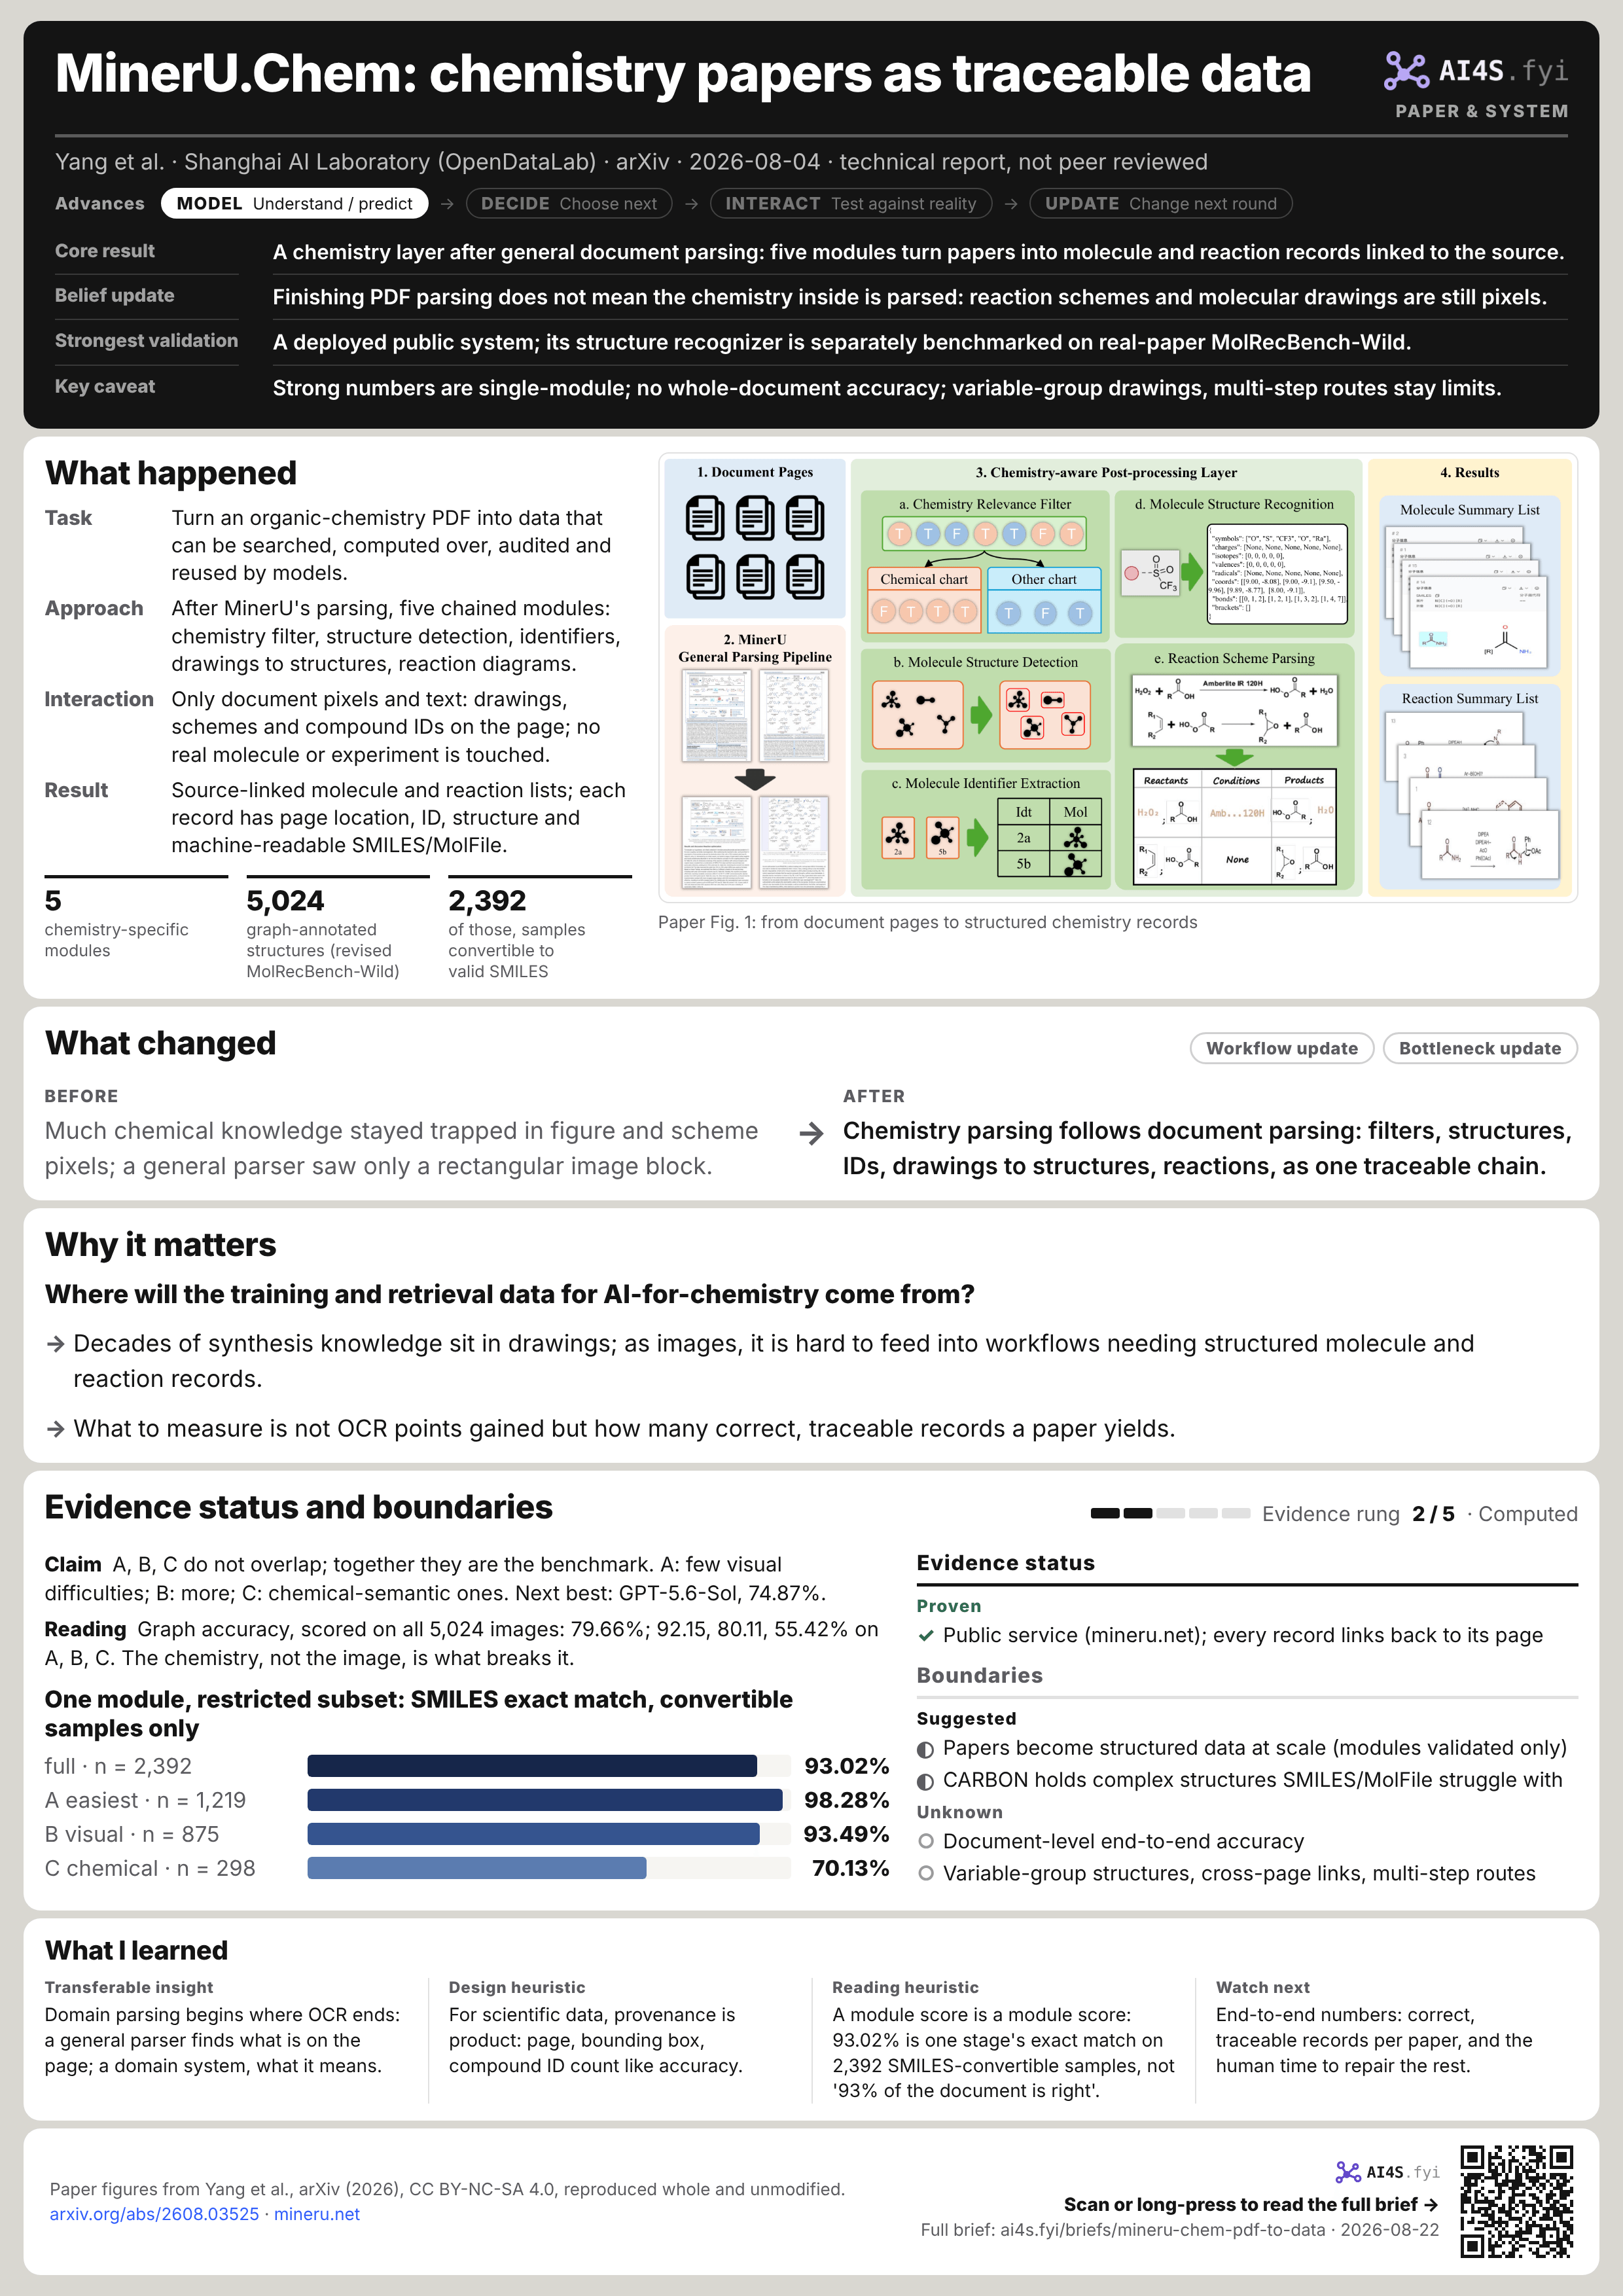
OpenDataLab at Shanghai AI Laboratory built MinerU.Chem to turn chemistry papers into traceable, auditable data that software can keep processing: from molecular drawings and SMILES to compound identifiers and reaction relationships.
●Technical report + public system + module evaluations
Current boundary: document-level end-to-end accuracy has not yet been reported
This work advances: Reads chemistry papers into traceable structured data
- MODELUnderstand / predict
- DECIDEChoose next
- INTERACTTest against reality
- UPDATEChange next round
Series Context
MinerU.Chem series | From chemistry PDFs to machine-usable reaction data
A chemistry layer after general document parsing: five modules turn papers into molecule and reaction records linked to the source.
- Belief update
- Finishing PDF parsing does not mean the chemistry inside is parsed: reaction schemes and molecular drawings are still pixels.
- Strongest validation
- A deployed public system; its structure recognizer is separately benchmarked on real-paper MolRecBench-Wild.
- Key caveat
- Strong numbers are single-module; no whole-document accuracy; variable-group drawings, multi-step routes stay limits.
01What happened
- Task
- Turn an organic-chemistry PDF into data that can be searched, computed over, audited and reused by models.
- Approach
- After MinerU's parsing, five chained modules: chemistry filter, structure detection, identifiers, drawings to structures, reaction diagrams.
- Interaction
- Only document pixels and text: drawings, schemes and compound IDs on the page; no real molecule or experiment is touched.
- Result
- Source-linked molecule and reaction lists; each record has page location, ID, structure and machine-readable SMILES/MolFile.
5chemistry-specific modules
5,024graph-annotated structures (revised MolRecBench-Wild)
2,392of those, samples convertible to valid SMILES
OpenDataLab at Shanghai AI Laboratory released the MinerU.Chem technical report with collaborators from East China Normal, Tongji, Fudan, Shanghai Jiao Tong, Peking University and other institutions. It asks a concrete question: how can an organic-chemistry PDF become data that can be searched, computed over, audited and reused by models?[S1]
General PDF parsers can already identify titles, paragraphs, formulas and tables. Chemistry introduces another layer. A reaction scheme contains substrates, products, catalysts, temperatures and sequence for a chemist, yet may remain a single rectangular image block to a document system.[S1]
Finishing PDF parsing does not mean the chemistry inside has been parsed. MinerU.Chem adds the missing layer after document parsing: chemistry parsing.
Not one model, but a pipeline
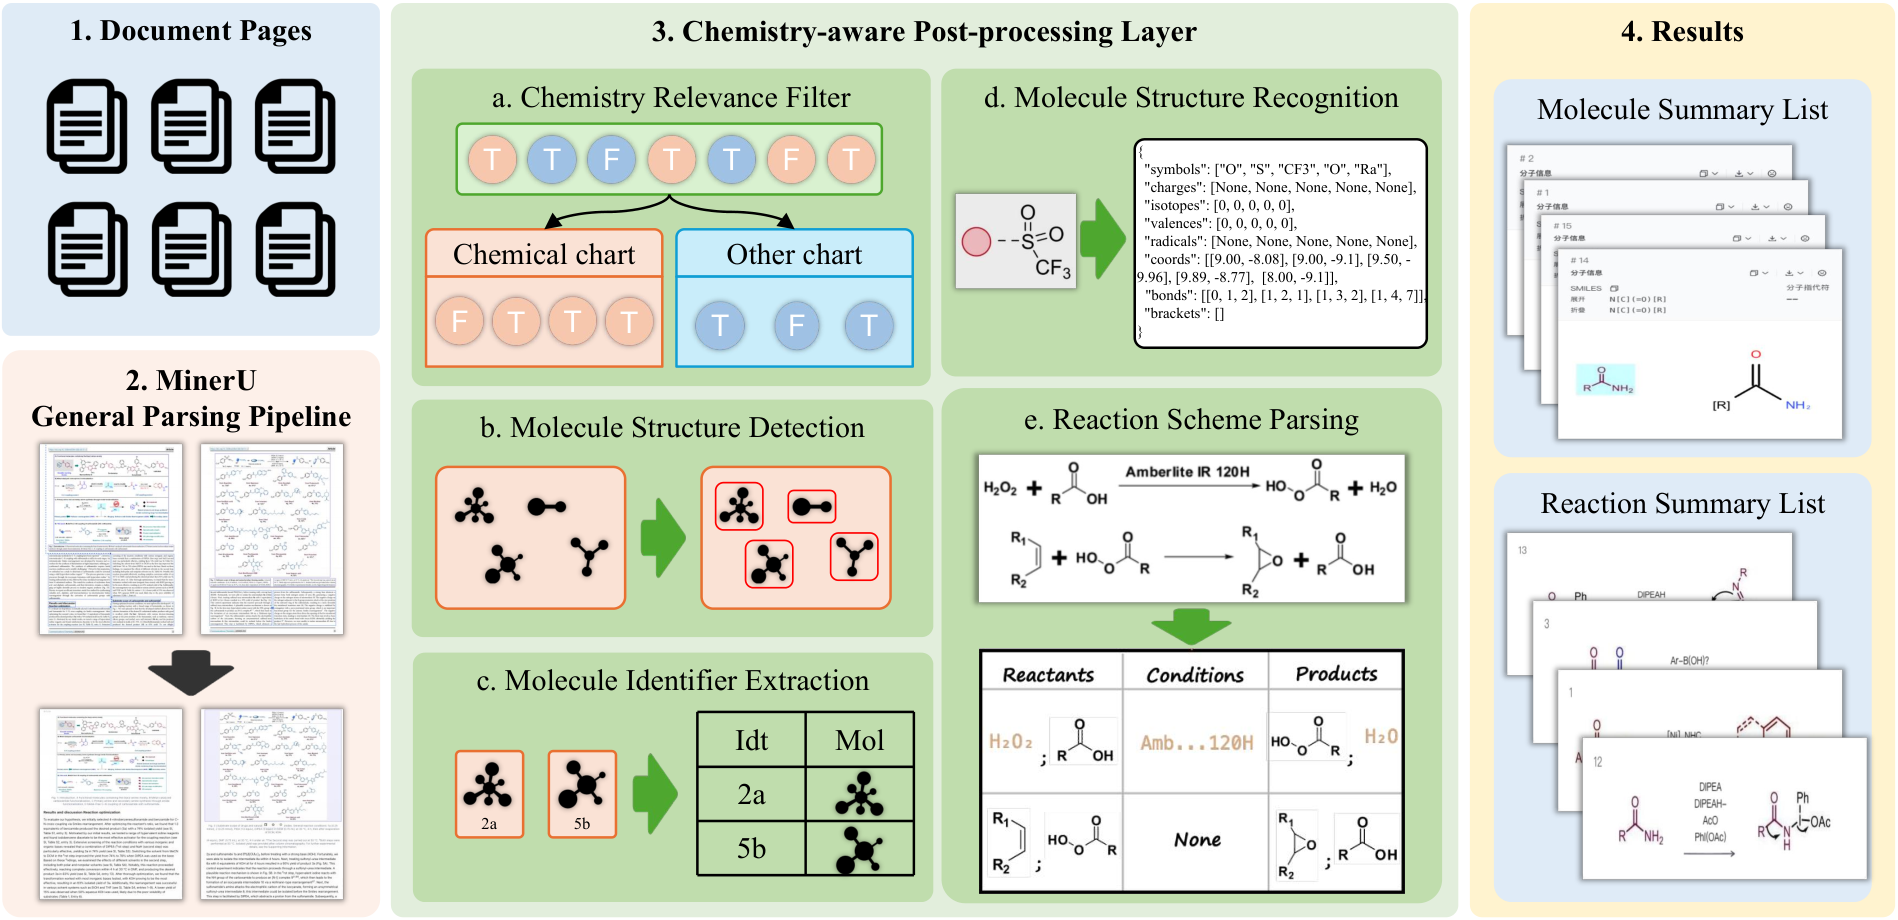
MinerU.Chem does not ask one model to jump from a whole PDF page to a reaction database. MinerU first parses the page; a chemistry-specific filter then decides whether a figure or table contains chemistry, keeping microscopy and ordinary charts away from more expensive specialist models.[S1]
The system then locates molecular drawings and nearby identifiers such as 1a, 2b or compound 7, linking visual structures to references in the paper. Only then does OCSR reconstruct a molecular graph and export machine-readable formats such as MolFile and SMILES.[S1]
Reaction-diagram parsing comes last: which molecules are reactants and products, whether text near an arrow is reagent, solvent or temperature, and how several arrows form successive steps. Together, the five modules turn image recognition into a document-to-data pipeline.[S1][S3]
A SMILES string without knowing whether the paper calls it 2b or 7c is hard to audit. A set of molecules without reaction relationships is still a stack of molecule cards, not a synthesis route.
02What changed
Workflow updateBottleneck updateMuch chemical knowledge stayed trapped in figure and scheme pixels; a general parser saw only a rectangular image block.
Chemistry parsing follows document parsing: filters, structures, IDs, drawings to structures, reactions, as one traceable chain.
Why SMILES alone is not enough
Real papers contain more than textbook SMILES: Ph, Et, Bu, Markush fragments, polymer repeat units, wavy bonds, coordination bonds and unusual valence. If the figure says Ph but extraction expands it into a full phenyl ring to produce a standard SMILES, the output may be chemically valid while no longer faithfully matching the source.[S2][S1]
CARBON preserves not only atoms and bonds but also 2D coordinates, abbreviations and complex properties that ordinary SMILES struggle to carry, then exports common formats from that richer intermediate representation. The principle matters more than the format name: first preserve what the paper actually shows; standardization comes second.[S2][S1]
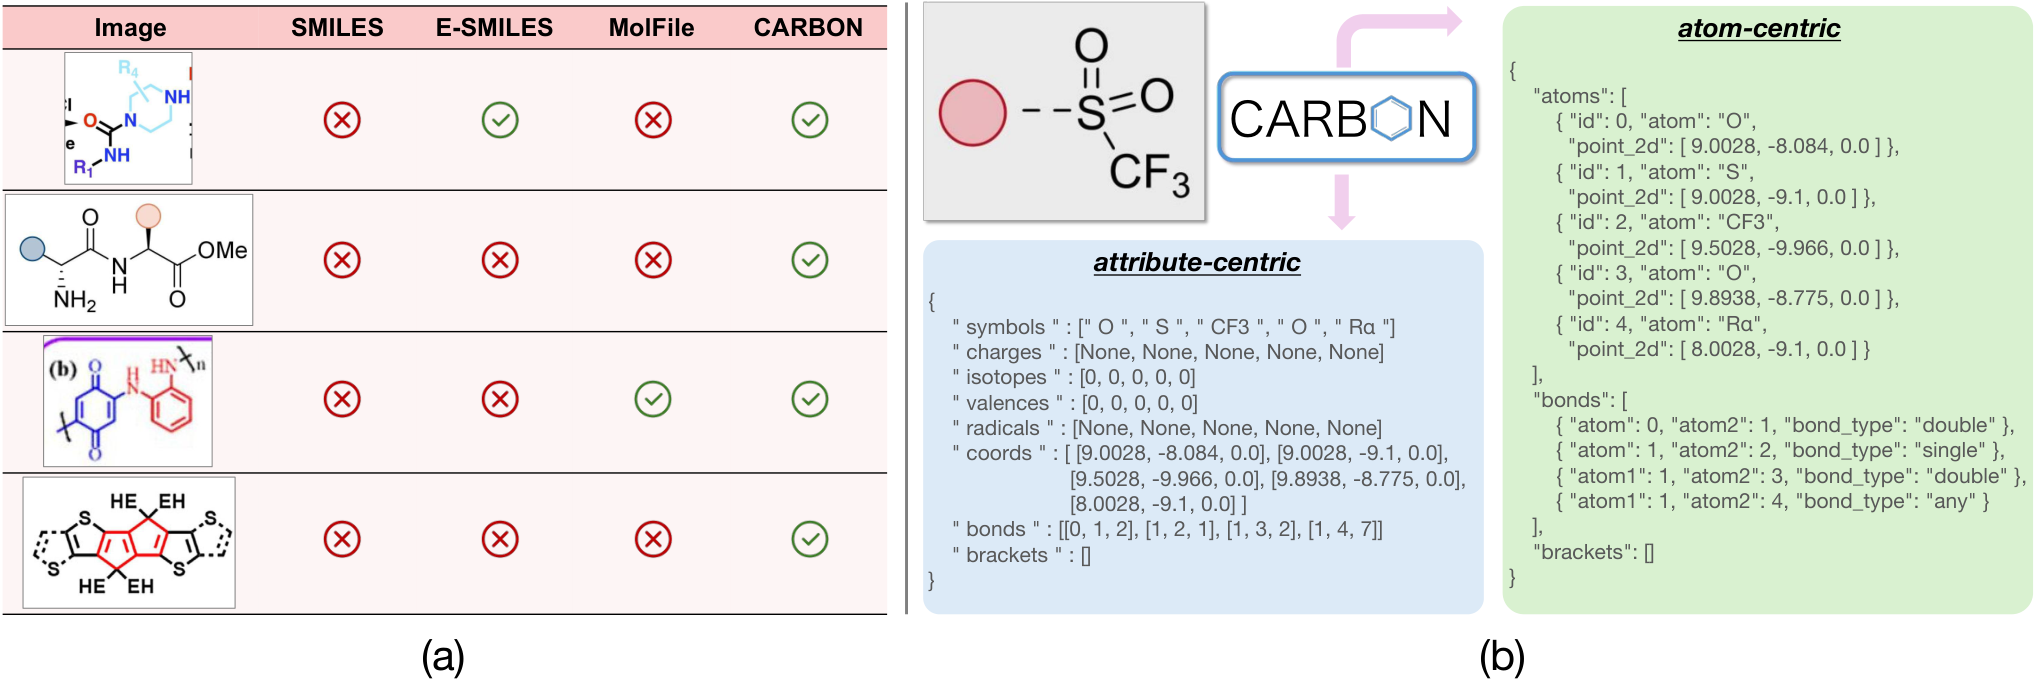
Paper Fig. 4. The left compares how representations handle Markush structures, unusual bonds and repeating units; the right shows how CARBON retains atoms, bonds, properties and 2D coordinates. Yang et al., arXiv (2026), CC BY-NC-SA 4.0. [S1]
03Why it matters
Where will the training and retrieval data for AI-for-chemistry come from?
- Decades of synthesis knowledge sit in drawings; as images, it is hard to feed into workflows needing structured molecule and reaction records.
- What to measure is not OCR points gained but how many correct, traceable records a paper yields.
The more interesting question is not how many points AI OCR gained, but where AI-for-chemistry training data will come from. Decades of synthesis knowledge live in papers, supporting information and patents, often in reaction schemes and molecular drawings. Multimodal models can look at images, but as long as the knowledge stays in images it is hard to feed directly into workflows that need structured molecule and reaction records, which is what reaction prediction, retrosynthesis, condition modeling and training data for new chemistry foundation models all require.
MinerU.Chem aims to shorten the distance from human-readable literature to machine-usable scientific data. The hard part is not merely running models at scale, but preserving extraction and provenance together.
04Evidence status and boundaries
Evidence rung 2 / 5 · Computed · Retrospective or simulatedEvidence status
Proven
- Public service (mineru.net); every record links back to its page
Boundaries
Suggested
- Papers become structured data at scale (modules validated only)
- CARBON holds complex structures SMILES/MolFile struggle with
Unknown
- Document-level end-to-end accuracy
- Variable-group structures, cross-page links, multi-step routes
ClaimA, B, C do not overlap; together they are the benchmark. A: few visual difficulties; B: more; C: chemical-semantic ones. Next best: GPT-5.6-Sol, 74.87%.
One module, restricted subset: SMILES exact match, convertible samples only
ReadingGraph accuracy, scored on all 5,024 images: 79.66%; 92.15, 80.11, 55.42% on A, B, C. The chemistry, not the image, is what breaks it.
A Molecule Summary List stores source location, compound identifier, structure representation and MolFile/SMILES for each molecule. A Reaction Summary List then organizes reactants, products and conditions and links them back to molecule records.[S1]
The part worth noticing is not JSON itself, but traceability. If stereochemistry is wrong, a reviewer can return to the page and original bounding box. A fluent summary is hard to debug; a structured record with source location can be sampled, relabeled and corrected.[S1]
A useful way to read MinerU.Chem is as a chemical evidence index layered over a PDF.
The easiest number to misread is 93.02%. It is not document-level extraction accuracy, nor a score over all 5,024 structure images, but the SMILES exact match of one structure-recognition module on the 2,392 samples that convert to valid SMILES. Detection and identifier matching come before it; reaction parsing and document-level linking come after it. End-to-end correctness is a different measure.[S1]
On the same benchmark the report also ran three kinds of comparison system: specialist OCSR tools and chemistry-tuned vision-language models, commercial chemical OCR services, and general multimodal models. The structure module leads all of them; the next best SMILES exact match is GPT-5.6-Sol at 74.87%, 18.15 points behind. The report then splits the benchmark by its MOSAIC difficulty labels into three mutually exclusive subsets of rising visual and chemical-semantic complexity: 98.28% SMILES / 92.15% graph accuracy on the easiest, 93.49% / 80.11% on the visually harder one, and 70.13% / 55.42% on the subset carrying chemical-semantic difficulty labels. The graph-accuracy margin over the next best system is printed as 43.25 points in the introduction and 42.1 in the results, so it is not quoted here.[S1]
The two metrics have different denominators. SMILES exact match can only be scored on samples with a valid SMILES annotation: 2,392 overall, and 1,219, 875 and 298 in A, B and C. Structures with, among other things, Markush fragments, unconventional abbreviations or bonds that break valence rules cannot become valid SMILES and are left out. Graph accuracy is scored on all 5,024 images: 1,987, 1,976 and 1,061 in A, B and C. The three subsets do not overlap and together make up the whole benchmark. The versions differ too: the first MolRecBench-Wild paper reports 5,029 structures from 820 papers; MinerU.Chem uses the latest revised version, 5,024 images all with graph annotations; 2,392 is the subset of those convertible to SMILES.[S1][S2]
This is a technical report and deployed system, but its strongest quantitative results concern individual modules rather than end-to-end document extraction. A mismatched compound identifier or condition attached to the neighboring arrow can still yield a perfectly valid-looking but incorrect database record.[S1]
Complex Markush structures, R-groups, cross-page references and multi-step routes remain clear boundaries. MinerU.Chem is better understood as high-throughput first-pass processing and a doorway to human review. The critical metrics are how many correct records a paper yields and how much human time is needed to repair the rest.[S1]
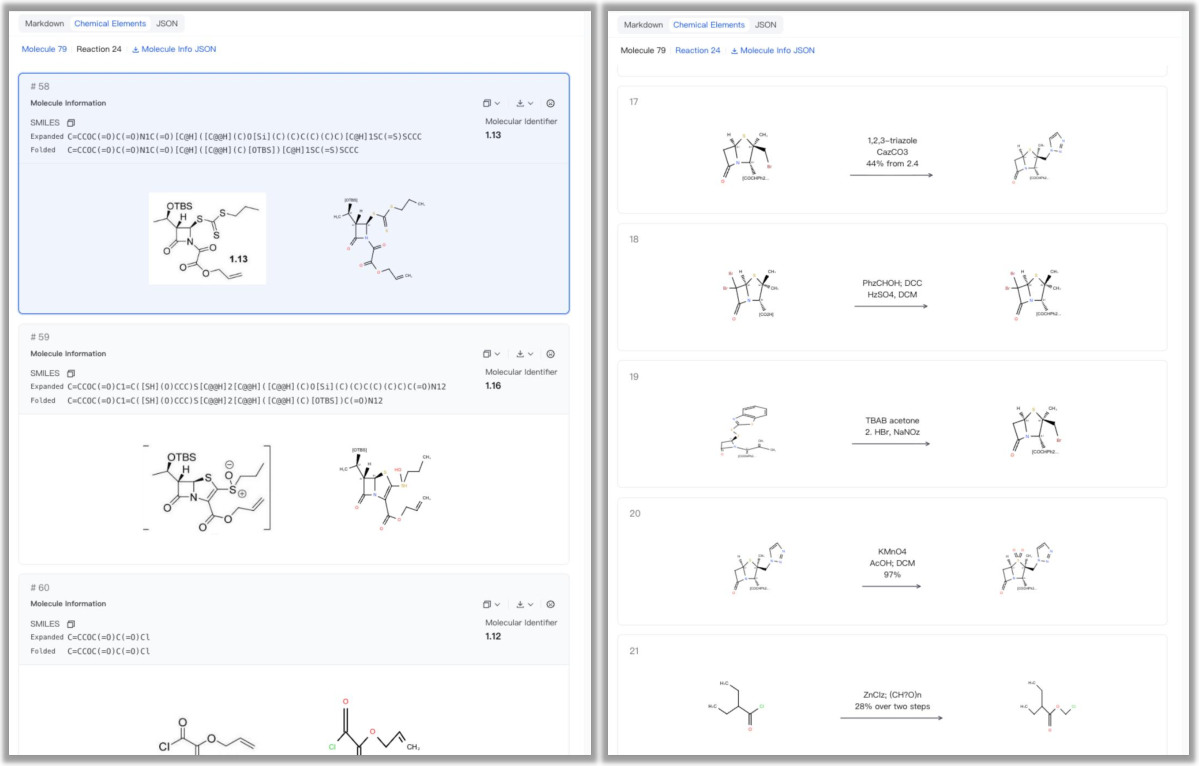
Paper Fig. 2. The output is a source-linked evidence index, not a summary: each record keeps its SMILES, identifier, source image and recognized structure, and successive reaction steps become auditable records; a wrong reading can be checked back at the page and bounding box. Yang et al., arXiv (2026), CC BY-NC-SA 4.0. [S1]
05What I learned
- Transferable insight
- Domain parsing begins where OCR ends: a general parser finds what is on the page; a domain system, what it means.
- Design heuristic
- For scientific data, provenance is product: page, bounding box, compound ID count like accuracy.
- Reading heuristic
- A module score is a module score: 93.02% is one stage's exact match on 2,392 SMILES-convertible samples, not '93% of the document is right'.
- Watch next
- End-to-end numbers: correct, traceable records per paper, and the human time to repair the rest.
Scientific document parsing begins where OCR ends
A chemistry reaction scheme is a graph; a materials paper may contain a phase diagram; a biology paper, a pathway. A general parser finds what is on the page. A domain system must understand what it means scientifically.
Scientific data needs provenance, not only accuracy
An incorrect stereocenter silently entering a training database is different from a chatbot making a verbal mistake. Source page, bounding box and compound ID may not look like AI, but they are core infrastructure.
The most useful automation is often not unattended
Large-scale machine extraction that focuses human time on difficult Markush structures, low-confidence cases and cross-page linking may be more valuable than insisting on full autonomy.
The literature remains a data mine not yet fully available to AI
As models improve, architecture is not always the bottleneck. A great deal of valuable scientific knowledge may simply remain unstructured.
As one imageTo save and share→Sources
Factual claims link to original announcements, project lists, trial records or journal papers where possible. Research plans are kept separate from completed results.