September 2026 edition
AI for Science is moving at once across proteins, genomics, materials, weather, mathematics, and laboratory automation. Each field has its own models, data, and scientific problems; viewed together, recurring patterns begin to emerge.
THE AI4S MAP is a continuously updated reading map for organizing those connections: what is becoming possible, where the evidence stands, and where the next bottleneck is moving.
ON THIS PAGE
01 / FRAMEWORK
MODEL · DECIDE · ITERATE · UPDATE
A mental model: from models to discovery
The easiest way to understand AI4S is not to memorize a list of models. Start with four questions:
MODEL → DECIDE → ITERATE → UPDATE
| Layer |
Core question |
Typical capabilities |
| MODEL |
What can we represent, predict, or generate? |
Representation learning, structure/property prediction, generative models, simulation |
| DECIDE |
Given what we know, what is most worth doing next? |
Search, ranking, experiment selection, hypothesis generation, planning |
| ITERATE |
Can we test the answer and run another round? |
High-fidelity computation, evaluation, synthesis, assays, robotic experimentation |
| UPDATE |
Does new evidence change the model, belief, or next-round strategy? |
Active learning, feedback, data return, closed-loop optimization |
This is the top-level coordinate system of THE AI4S MAP. Expanded, it becomes a more detailed scientific-discovery workflow:
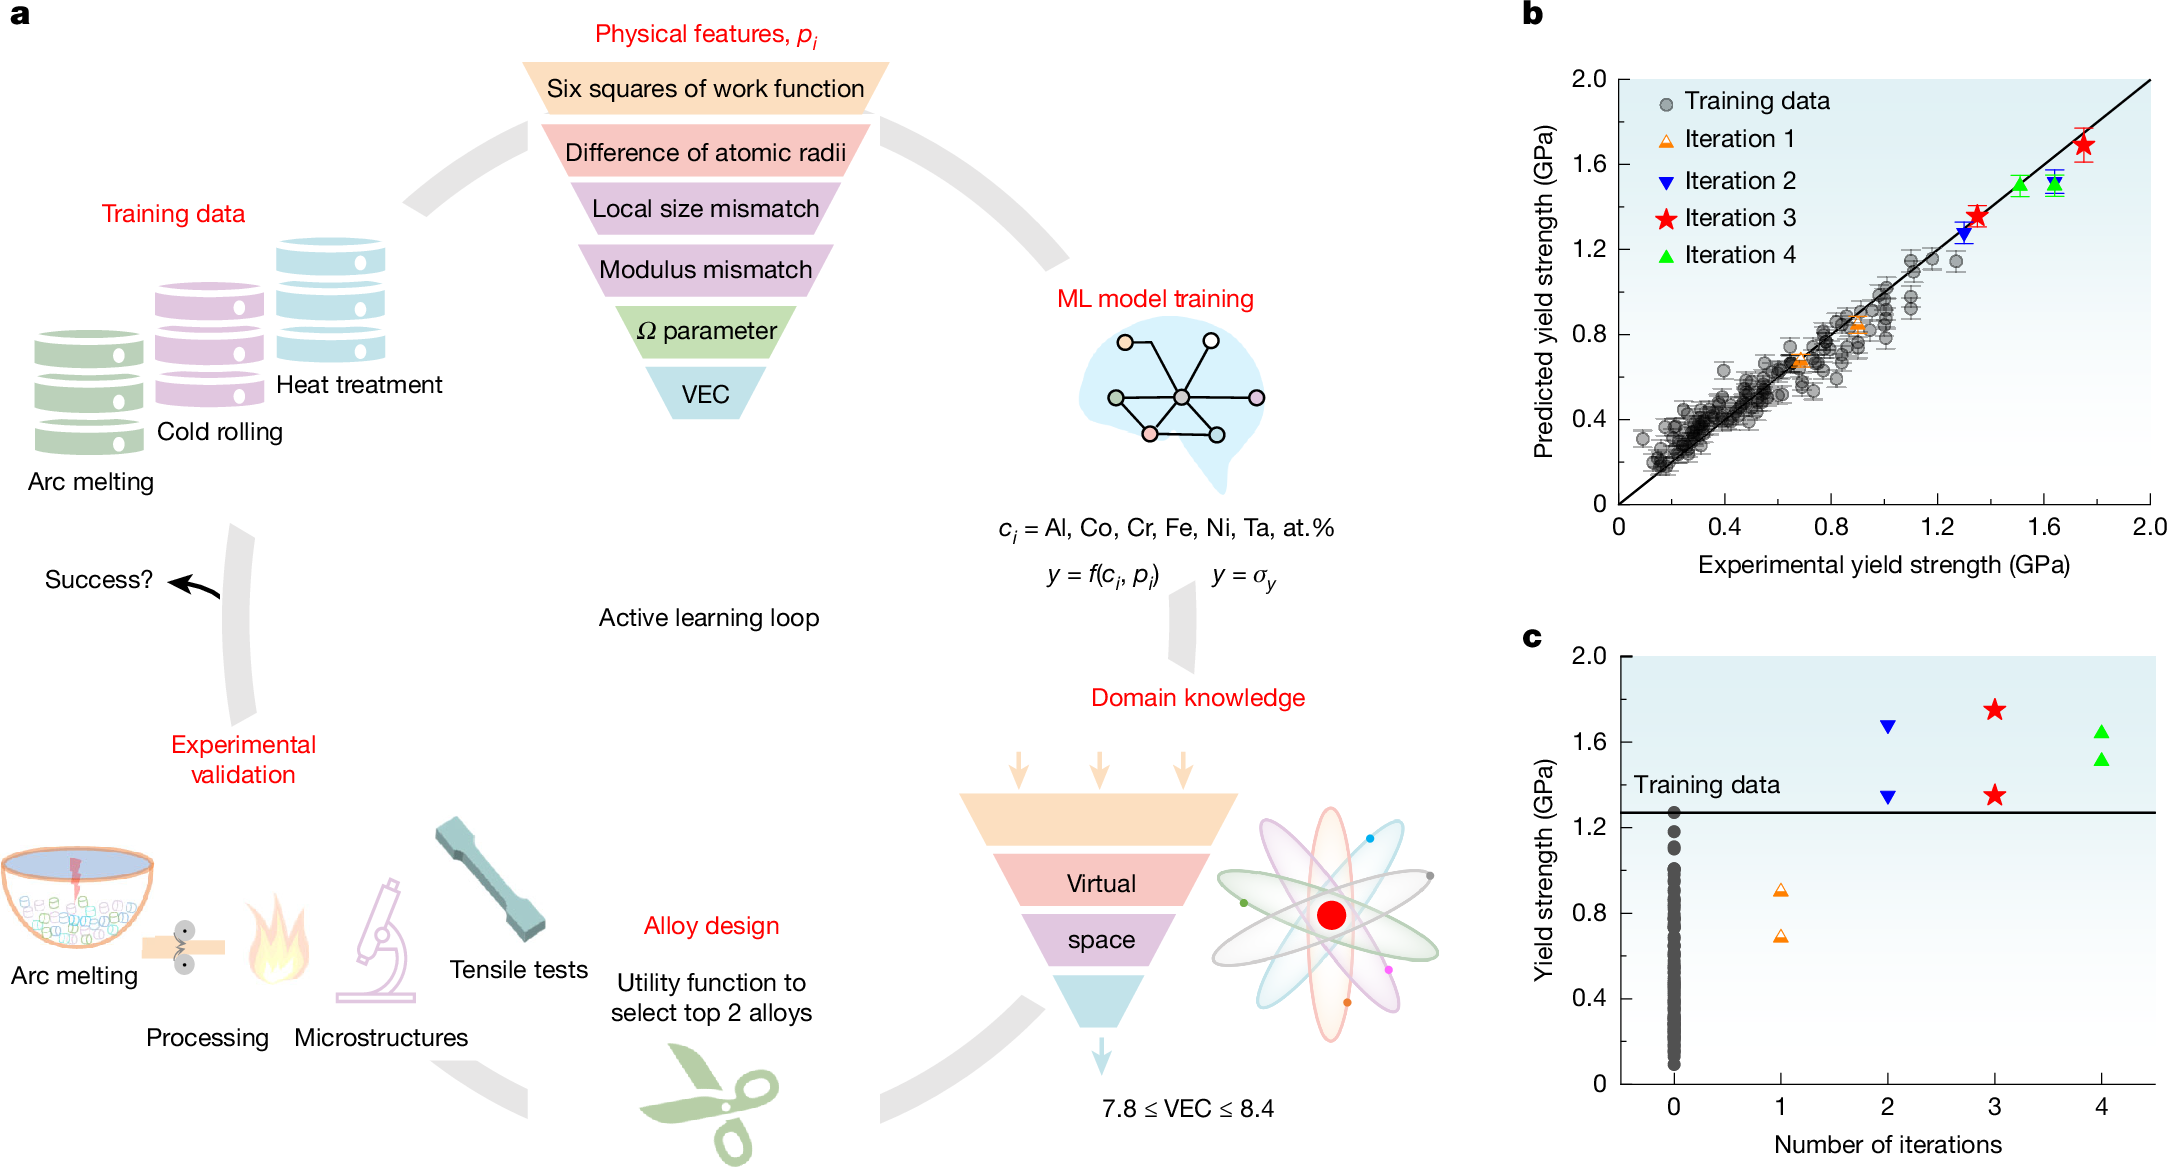
Knowledge → Representation → Model → Search → Validation → Experiment → Feedback → (back to Knowledge)
| # |
Stage |
What it does |
Top-level coordinate |
| 1 |
Knowledge |
Existing literature, data, and priors |
MODEL |
| 2 |
Representation |
Encode the world into objects a model can process |
MODEL |
| 3 |
Model |
Predict, generate, or simulate |
MODEL |
| 4 |
Search |
Explore hypothesis and candidate spaces |
DECIDE |
| 5 |
Validation |
High-fidelity computation, benchmarks, formal proof |
ITERATE |
| 6 |
Experiment |
Measurements in the physical world |
ITERATE |
| 7 |
Feedback |
Return results to change the next decision or model |
UPDATE |
Different systems connect different parts of this loop. AlphaFold primarily pushed MODEL; GNoME connected modeling with search and computational feedback; MatterGen turns target properties into generated candidates; Co-Scientist and AlphaEvolve place generators inside explicit search-and-evaluation loops; A-Lab connects decisions to real instruments; Robin goes further by returning experimental results to later analysis and hypothesis updating.
Organizing by discovery stage, rather than only by discipline, is the core principle of this map. Disciplinary categories can hide structural similarities across fields: diffusion models appear in both protein design and crystal generation, while active learning recurs in materials discovery, experiment selection, and self-driving laboratories.
When 21 representative works are mapped across discovery stages, one asymmetry becomes hard to ignore:
Knowledge        ███            3
Representation   █████          5
Model            █████████████ 13
Search           ██████████    10
Validation       ███████        7
Experiment       ███            3
Feedback         ██             2
Among these 21 curated works, 13 touch the model layer, while only 3 touch physical experiment and 2 touch feedback.
This is not a statistical estimate of the AI4S literature. The 21 works were manually curated, not randomly sampled. But it exposes an asymmetry worth tracking: as you move from model capability toward a full experimental loop, the number of representative systems drops quickly. The full list and annotation rules are published with the map so the counts can be checked directly.
The full interactive map can be filtered by MODEL / DECIDE / ITERATE / UPDATE and by the finer-grained discovery stages, with notes on which bottleneck each system moved and how far its evidence extends.
This explains a theme that appears throughout the map: prediction is not discovery. A model can perform extremely well on a benchmark and still be far from producing a new scientific result. A generated molecule still has to be synthesizable; a predicted material has to survive finite temperature, defects, and processing; a biological hypothesis still needs an experiment sensitive enough to tell whether it is right.
The reliability of a discovery loop is often constrained by its weakest evaluation and feedback step.
02 / START HERE
1. Start here
If you are new to AI4S, start with these. You do not need a complete technical background; together they give a useful mental model of the field.
- The Fourth Paradigm: Data-Intensive Scientific Discovery (Jim Gray, 2009): One of the classic starting points for data-intensive science. Gray argued that after experiment, theory, and computational simulation, data-intensive exploration was emerging as another scientific paradigm. Much of today’s AI4S conversation makes more sense in this longer history.
- Scientific discovery in the age of artificial intelligence (Nature, 2023): A review by Hanchen Wang and coauthors spanning biology, physics, chemistry, and materials. If you read only one review, read this one; it does an unusually good job of separating where AI enters the scientific workflow.
- AlphaFold: The making of a scientific breakthrough (DeepMind documentary) + John Jumper’s Nobel lecture: The documentary is about the team and the competition; the Nobel lecture is about technical choices and tradeoffs. Together they are a useful case study of what makes a scientific problem tractable for AI: deep accumulated data (PDB), relatively clear experimental ground truth and blind evaluation (CASP), and architectures aligned with domain structure.
- AI for Science: An Emerging Agenda (2023): A Dagstuhl workshop report with a broader and more neutral lens than most corporate narratives. It explicitly discusses incentives, peer review, data infrastructure, and other non-model bottlenecks.
- The Bitter Lesson (Rich Sutton, 2019): A useful coordinate for a recurring AI4S debate: how much domain prior should be explicitly encoded into a model—symmetry, conservation laws, physical constraints—and how much should be learned through scale. Read this before the next section and the tension between the two routes becomes clearer.
03 / METHODS
MODEL
2. Methodological foundations: where AI4S diverges from general AI
If one major storyline of general AI can be summarized by Transformers and scaling laws, AI4S repeatedly encounters another set of structures that cannot simply be ignored: symmetry, physical constraints, inverse problems, sparse data, and out-of-distribution generalization.
Atoms rotate, molecules translate, crystals repeat periodically, physical systems conserve quantities, measurements are noisy, experiments are expensive, and many scientific goals sit outside the historical data distribution. The key question becomes:
Which structures of the world should we force a model to respect, and which should we let it learn?
Explanations and tutorials
- Geometric Deep Learning (Bronstein, Bruna, Cohen, Veličković, 2021): An attempt to unify CNNs, GNNs, and equivariant networks through group theory. Molecules, crystals, and proteins are geometric objects with symmetries; this language is foundational for understanding many scientific models. The book manuscript, lectures, and course materials are free.
- e3nn documentation and tutorials: What E(3)-equivariance looks like in engineering practice. Hard to avoid if you work on atomistic modeling.
- A Hitchhiker's Guide to Geometric GNNs for 3D Atomic Systems (2023): A useful bridge from “I know equivariant networks exist” to “I understand how SchNet, DimeNet, NequIP, and MACE differ.”
- NequIP (2022): One of the cleanest demonstrations of what symmetry can buy you: E(3)-equivariant representations delivered order-of-magnitude improvements in data efficiency and became an important ancestor of later equivariant interatomic potentials.
- Physics-Informed Neural Networks (Raissi et al., 2019): Writes PDE residuals directly into the loss. PINNs remain controversial in engineering performance (see Section 8), but they are the best-known representative of “put physics into the network.” The broader principle is more important than PINNs themselves: scientific models do not have to choose between data and physics.
- Fourier Neural Operator: A different route from PINNs—not fitting one solution, but learning the solution operator. The value of the idea in one sentence: learn the simulator, not the simulation result. This has become important in fluids, climate, and seismic modeling.
- Bayesian optimization and active learning: In ordinary ML, the dataset usually exists before training. In science, choosing which data to collect is itself part of the problem. Exploration–exploitation tradeoffs recur across materials discovery, catalyst optimization, protein engineering, and self-driving laboratories.
- Diffusion models: One of the most important method transfers from image generation into molecules and crystals. For the general method, read Lilian Weng’s What are Diffusion Models?; for the scientific transfer, go directly to RFdiffusion and MatterGen.
Courses
04 / DOMAINS
MODEL · DECIDE
3. Deep dives by domain
3.1 Structural biology and protein design
One of the most mature AI4S subfields, and a template other domains repeatedly borrow from.
- AlphaFold2 (Nature, 2021) and AlphaFold3 (Nature, 2024): AF2 transformed single-chain protein structure prediction; AF3 extended the system to protein–ligand, protein–nucleic-acid, and antibody–antigen complexes. AF3’s initial release without simultaneous code and model access triggered a major openness debate, followed quickly by open alternatives such as Boltz and Chai.
- Boltz-2 (2025, preprint): An open model for joint structure and binding-affinity prediction and one of the easier options for researchers who want to deploy and experiment themselves.
- ESM3 (Science, 2025): EvolutionaryScale’s multimodal protein language model jointly modeling sequence, structure, and function. It generated esmGFP, which had only 58% sequence identity to the nearest known fluorescent protein—roughly 96 residues different.
- RFdiffusion (Nature, 2023): The Baker lab’s de novo protein-design diffusion model. AlphaFold reads structure; RFdiffusion writes structure. Baker shared the 2024 Nobel Prize in Chemistry with Hassabis and Jumper for the broader line of work.
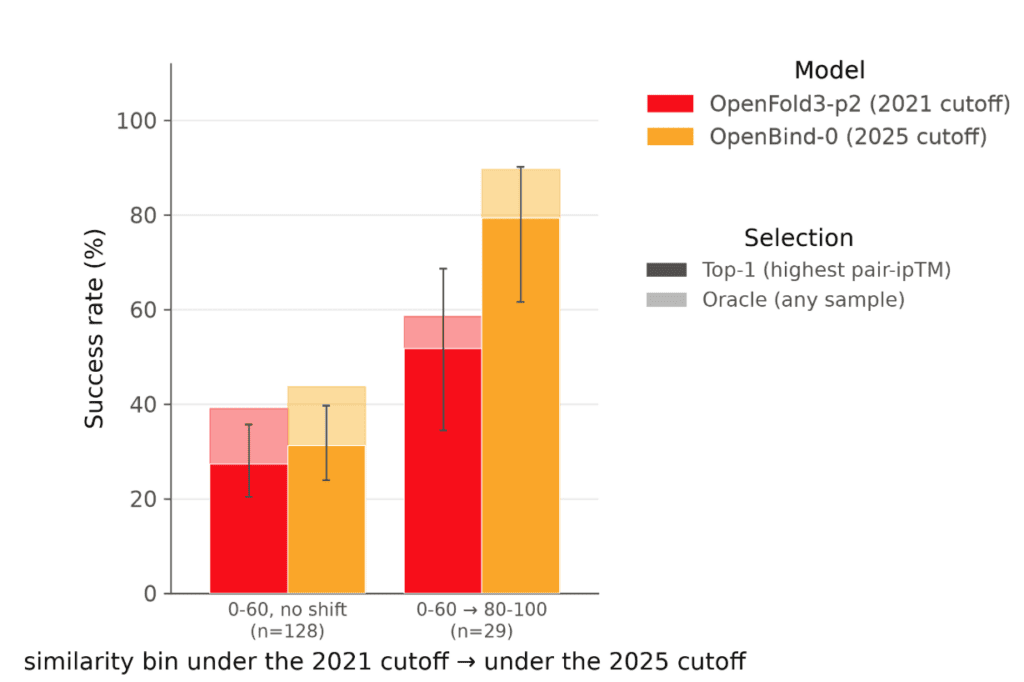
- BindCraft (2025): An open one-shot de novo binder-design pipeline reporting experimental hit rates of 10–100% across tested targets, with an average of 46.3%. It makes an important point explicit: to judge whether an AI4S direction is mature, do not only ask whether it can generate; ask what fraction survives the lab.
The progression can be summarized as a chain of arrows, each one a distinct scientific problem:
Sequence → Structure → Interaction → Function → Design
3.2 Genomics and the “virtual cell”
After structure prediction, a harder frontier is modeling how cells respond to perturbations.
- Evo 2 (Nature, 2026): A 40B-parameter genomic foundation model from Arc Institute and NVIDIA with a one-million-token context and training on roughly nine trillion bases across eukaryotes and prokaryotes. Without task-specific fine-tuning, it can predict functional effects including BRCA1 clinical variants. The accompanying sparse-autoencoder interpretability work is also worth reading.
- AlphaGenome (Nature, 2026): DeepMind’s unified DNA sequence-to-function model, advancing prediction of regulatory activity and variant effects—particularly important because many disease-associated variants lie in noncoding regions.
- Arc Virtual Cell Initiative (State, Stack, and Virtual Cell Challenge): Turns “predict cellular response to perturbation” into an open, benchmarkable problem and is one of the most important pieces of public infrastructure in the virtual-cell direction.
- Perturb-seq00597-9): A core data foundation for virtual-cell models. Read it to internalize a broader lesson: how perturbation data is generated and which biological states it covers can be as important as the model architecture.
3.3 Chemistry and materials
- GNoME (Nature, 2023): Reported roughly 2.2 million predicted candidates, with about 380,000 in an updated stable set. The more durable idea is its data flywheel: the model screens candidates, DFT generates expensive labels, and those results improve the next model. Pair it with Cheetham & Seshadri’s critique (Chem. Mater., 2024). Together they are an excellent lesson in how slippery the word “discovery” can be in AI4S.
- MatterGen (Nature, 2025): Microsoft Research’s conditional generative model for generating crystal structures to target desired properties, including physical synthesis validation. Screening asks “which candidate is better?” Inverse design asks “what candidate should exist?” That difference is fundamental.
- MACE-MP-0 / MatterSim / UMA / GRACE: Universal machine-learning interatomic potentials (uMLIPs). Their value sits at the MODEL ↔ ITERATE interface: approximate energies and forces at far lower cost than first-principles methods, expanding the scale of simulation and candidate evaluation. They should not be treated as automatic DFT equivalents, especially for finite temperature, surfaces, defects, interfaces, and out-of-distribution systems—the exact issues newer benchmarks such as MOFSimBench, CHIPS-FF, and UniFFBench are probing.
- Six Open Questions in MLIP Foundation Models (2026): Read this after the success stories. It asks what “foundation model” should even mean here, how transfer should be evaluated, where models fail, and what evidence is still missing.
- Open Catalyst Project (OC20 / OC22 / OMat24): Meta-led open datasets and competitions that helped define the evaluation culture of this subfield.
- A-Lab (Nature, 2023; corrected in 2026): Berkeley’s autonomous synthesis lab ran 353 experiments in 17 days and realized 36 of 57 targets. GNoME asks “what materials might exist?” A-Lab asks “can we actually make them?” The gap between computational possibility and physical realizability is one of AI4S’s defining problems. It should also be read alongside community critiques of its characterization conclusions.
3.4 Earth systems and climate
One of the AI4S areas with the strongest evaluation infrastructure and the most continuous real-world verification, because rigorous forecasting standards existed long before modern AI entered.
- GraphCast (Science, 2023): A graph neural network for medium-range forecasting that outperformed ECMWF’s HRES deterministic system on roughly 90% of 1,380 verification targets, while producing a 10-day forecast in under a minute.
- GenCast (Nature, 2025): Moves from deterministic forecasting to diffusion-based ensembles, outperforming ECMWF’s ensemble system on 97.2% of 1,320 verification targets. We never wanted one future; we wanted a distribution of possible futures. In that sense this step may matter more than GraphCast.
- WeatherNext 2 and WeatherNext Cyclones (2025–2026): The engineering/deployment stage. The 2026 Nature cyclone model achieved three-day forecasts with the accuracy that previously required two days—roughly one extra day of warning—and was developed with partners including the National Hurricane Center and Met Office. Code was released under Apache 2.0 and other materials under CC BY 4.0.
- NeuralGCM (Nature, 2024): A hybrid route: keep a differentiable dynamical core and learn parts of the physical parameterization. It is an important response to the concern that purely data-driven systems may fail to extrapolate into unseen climate states.
- Aurora (Nature, 2025): Microsoft’s atmospheric foundation model spanning weather, air quality, and ocean waves.
- WeatherBench 2: A crucial public benchmark, illustrating how mature, standardized, reproducible evaluation can improve the credibility of model comparison.
3.5 Mathematics and algorithm discovery
One of the fastest-moving areas in 2025–2026.
- AlphaProof (Nature, 2025): Combines reinforcement-learning-style proof search with formal Lean verification and reached silver-medal-level performance on IMO 2024 problems. The key is not only generating answers; candidates receive machine-checkable formal feedback.
- AlphaProof Nexus (2026): A frontier LLM + Lean verification + search system that solved 9 of 353 open Erdős problems and proved 44 of 492 OEIS conjectures. The strongest system can cost hundreds of dollars per hard problem. Notably, a simpler “LLM generation ↔ Lean verification” loop reproduced all nine Erdős successes, though at higher cost on the hardest problems. This changes how we should think about specialized search systems versus general models, but is not enough to conclude that general models will replace specialized methods.
- FunSearch (Nature, 2024) and AlphaEvolve (2025): Instead of generating proofs, they evolve programs. AlphaEvolve improved a 4×4 matrix-multiplication algorithm for the first time in 56 years and optimized Google data-center scheduling. The common pattern is a strong machine-readable evaluator: do not ask another model whether the idea sounds right; run it and see whether it works.
- Terence Tao’s blog and interviews: One of the most useful ongoing views from a top mathematician. His item-by-item discussion of AI math results is especially valuable for distinguishing “formally verified” from “mathematically meaningful.”
- Lean and mathlib: Why is mathematics unusually fertile for verifiable AI search? Once a problem is formalized, Lean provides cheap, deterministic step-by-step checking. Formalization itself is not free, but strict automated rejection is far cheaper than many physical experiments.
3.6 Other directions worth tracking
- Fusion control: Magnetic control of tokamak plasmas through deep RL (Nature, 2022), where reinforcement learning directly controls a real plasma system.
- Astronomy: Gravitational-wave detection, exoplanet screening, galaxy morphology classification—large datasets and relatively clean labels made astronomy an early target for deep learning.
- Neuroscience and connectomics: FlyWire’s whole-fly-brain connectome (Nature, 2024), an AI segmentation + human proofreading collaboration at massive scale.
05 / AGENTS & LABS
DECIDE · ITERATE · UPDATE
4. Agents, autonomous labs, and “AI scientists”
Domain foundation models operate on molecules, genomes, materials, and physical fields. A second class of systems operates on something different: the research process itself.
- Co-Scientist (DeepMind, Nature 2026) and Robin (FutureHouse, Nature 2026): Two independent multi-agent systems published the same day. Co-Scientist turns hypothesis generation from a one-shot output into search over an idea space—generation, critique, ranking, evolution. One of its strongest validations came from Imperial College, where a group used it on a bacterial-genetics problem they had recently solved but not yet published, and it independently produced the correct hypothesis. Robin connects literature, hypothesis, experimental strategy, data analysis, and later hypothesis updating; critical physical experiments were still performed by humans and then returned to the system.
- Kosmos (Edison Scientific, 2025): Targets long-horizon coherence. A Kosmos run can last up to 12 hours, using a structured world model to coordinate literature search and data analysis. The paper reports roughly 200 agent rollouts, 42,000 lines of code, and 1,500 papers read per run. More interesting is how it asks whether a “discovery” is just a restatement of something already seen: three of seven reported findings independently reproduced preprints or unpublished results that Kosmos had not accessed during the run, serving as a useful check against memory and retrieval leakage.
- Empirical Research Assistance (DeepMind, Nature 2026): Narrows the target to scoreable empirical software. An LLM rewrites code while tree search and automated evaluation iterate toward better scientific-computing solutions. It is not a full “hypothesis → experiment” scientist; it is a deliberately narrower task with more objective feedback.
- The AI Scientist and v2 (Sakana AI, 2024–2025): End-to-end automated paper writing. Highly controversial, but useful as a probe of the upper bound of full automation.
- Coscientist (Nature, 2023) and ChemCrow: Earlier examples of LLMs integrated with chemistry tools and robotic hardware.
- Self-driving laboratories (SDLs): Start with the 2026 Nature Reviews Chemistry review The past, present and future of self-driving laboratories, then look back at the 2023 Self-Driving Labs review and Canada’s Acceleration Consortium. The newer review summarizes the next-stage challenge in three terms: scalability, generalizability, provenance-complete experimentation. Hardware reliability, cross-lab transfer, and complete experimental provenance are becoming bottlenecks on the same level as algorithms.
A distinction worth carrying around:
Automation: automatically execute a pre-specified experiment.
Autonomy: decide which experiment should happen next.
The second is much closer to scientific discovery.
The boundary conditions are equally clear: when evaluators are reliable and cheap—code, mathematics, some simulations—AI can search much more aggressively. When evaluation requires long-cycle synthesis, animal studies, or scarce large instruments, the same search logic is strongly constrained by feedback delay, cost, and noise.
06 / PRACTICE
5. Practical guide: how to actually build
- Hugging Face model ecosystem: ESM, Boltz, some atomistic models, and biological foundation models are often released through Hugging Face or project repositories. There is no single complete “AI4S” filter; models are spread across tasks and organizations.
- DeepChem / ASE / PyTorch Geometric / JAX MD: Cover chemistry workflows, atomistic-simulation interfaces, graph neural networks, and differentiable molecular dynamics respectively.
- Materials Project / PDB / ERA5 / UniProt: Four representative pieces of public scientific data infrastructure. Signature AI4S successes often appear where standardized data has accumulated for years: PDB for AlphaFold and ERA5 for learned weather forecasting are not incidental background conditions.
- A practical tutorial on fine-tuning uMLIPs: A general model is often not accurate enough for a specific material system. How to fine-tune without catastrophic forgetting is a common real-world engineering problem.
- Tool protocols and instrument integration: MCP (released November 2024) represents a class of open protocols for allowing models to call external data and tools through standardized interfaces. It can inspire the software/instrument tool layer, but it is not a lab-hardware safety protocol. Real equipment still needs permissioning, state management, fault recovery, auditing, and safety interlocks.
07 / EVALUATION
ITERATE
6. Evaluation and benchmarks
AI4S has an evaluation problem. Language models can be tested on questions with known answers. Scientific discovery is harder because the most interesting answer may not exist yet.
Before discussing specific benchmarks, it helps to build an evidence map. AI4S evidence should not be collapsed into one score, because “how deep is the validation?” and “how independent is the validation?” are different dimensions.
Dimension A: Validation depth
| Depth |
Evidence |
What it answers |
| 1 |
Benchmark |
How does it perform on a fixed test set or established task? |
| 2 |
High-fidelity computation |
Does it pass higher-precision computation, formal verification, or a strong evaluator? |
| 3 |
Prospective prediction |
Can it correctly predict something not yet measured or not yet observed? |
| 4 |
Physical experiment |
Can it be measured in a real physical or biological experiment? |
| 5 |
Real-world use |
Is it being used continuously in real research, business, or engineering workflows? |
Dimension B: Evidence independence
| Status |
Meaning |
| Internal |
Validation performed by the same team and pipeline |
| External benchmark |
Tested on external data, public benchmarks, or third-party settings |
| Independent replication |
A separate group or laboratory obtains a consistent result |
These dimensions cannot substitute for each other. Passing a learned stability model is not the same as passing DFT; passing DFT is not the same as being synthesizable; one sample synthesized by the originating team is not the same as independent replication.
For example, MatterGen reaches Physical experiment, but the physical validation is primarily within the originating research chain. GNoME’s million-scale candidate set is mostly at High-fidelity computation, while the paper also reports 736 structures matching later independent experimental realizations. AlphaFold combines long-running external blind evaluation, independent use, and broad adoption in real research workflows. Different subsets of the same project can have different evidence depth; that is exactly why they should not be forced into one 1–6 score.
Scientific reasoning and knowledge
- FrontierScience (2025): Expert-level scientific reasoning benchmark across physics, chemistry, and biology, with Olympiad and Research tracks. The Research track deliberately looks more like PhD research work, but the authors explicitly note that it still does not cover new-hypothesis generation, multimodal experimentation, or real physical systems.
- GPQA: PhD-level physics, chemistry, and biology questions designed to be “Google-proof.” The Diamond subset is a common frontier-model benchmark.
- Humanity's Last Exam: Extremely difficult cross-disciplinary closed-form questions designed to resist benchmark saturation.
- FrontierMath: Research-level mathematics problems kept private to reduce contamination.
Research execution
- LAB-Bench and BixBench: Realistic biology research tasks including literature reasoning, sequence manipulation, protocol debugging, and data analysis.
- MLE-bench / PaperBench / CORE-Bench: Evaluate machine-learning engineering, paper replication, and computational reproducibility respectively.
- SciCode: Scientific-computing programming tasks extracted from real papers.
Domain-specific
- CASP: The biennial blind test for protein-structure prediction, the stage on which AlphaFold became famous and one of the gold standards for AI4S evaluation culture.
- Matbench Discovery: Materials-stability prediction benchmark designed specifically to expose uMLIP failure modes in realistic discovery workflows.
- WeatherBench 2: Weather forecasting.
- Virtual Cell Challenge: An open competition for predicting cellular perturbation responses.
A recurring lesson: when a subfield lacks CASP-style blind testing, standardized benchmarks, or independent replication, the evidence threshold for claiming a “breakthrough” should be higher. The contrast between materials and weather evaluation infrastructure is a useful example.
08 / INDUSTRY
7. Industry and market analysis
- Isomorphic Labs: Alphabet’s AI-first drug-discovery company founded by Demis Hassabis. Its $2.1B Series B in 2026 makes it one of the most important capital and industry cases to watch for whether AI4S can become large-scale R&D and commercial value.
- Periodic Labs, Lila Sciences, Radical AI, and Orbital Materials: A group of companies combining AI with automated experiments, new scientific-data generation, or closed-loop discovery in materials and biology. One emerging industry thesis is that as foundation-model capability diffuses, proprietary experimental data, experimental throughput, and closed-loop execution may become more important sources of differentiation. That remains a business hypothesis, not yet a settled fact.
- Edison Scientific × Incyte collaboration (2026): Incyte announced that Kosmos will be used in discovery and development workflows, initially around target discovery/validation and translational biology. It is a real enterprise-deployment case worth tracking, but still too early to infer actual scientific output from the collaboration announcement alone.
- MIT Technology Review: AI for science needs reasoning, not just data (2026): Frames structural AI4S barriers through experimental-data quality: cell-line drift, reagent differences, and environmental variation make biological and chemical experiments much harder to standardize than structural databases or weather reanalysis. A good lens on why AlphaFold-style success cannot simply be copied into every experimental science.
- Stanford HAI AI Index and State of AI Report: Annual reports with dedicated science sections.
- The macro productivity question: Read the economics literature on the long-run decline in research productivity, including Bloom et al., Are Ideas Getting Harder to Find? One of AI4S’s largest claims is that it can bend this curve. We still do not have enough mature aggregate evidence to know whether that is happening.
09 / CRITIQUE
8. Criticism, controversy, and failure cases
- The debate over GNoME’s “2.2 million new materials”: Cheetham & Seshadri (2024) systematically questioned the chemical novelty, realizability, and meaning of “discovery” behind generated structures. Related debate emerged around A-Lab characterization. The core issue: “new” computationally does not automatically mean “new” scientifically.
- The withdrawn MIT materials-AI preprint (2025): A widely cited study claiming large productivity gains from AI tools for materials scientists was withdrawn from arXiv and its QJE submission after MIT lost confidence in the data and conclusions. It was not a journal retraction after peer-reviewed publication; it was withdrawn at the preprint/submission stage. The episode matters because it had been one of the strongest empirical claims for AI-driven science productivity. Evidence about the impact of AI4S should itself be held to scientific standards.
- PINN performance gaps: Can Physics-Informed Neural Networks beat the Finite Element Method? (2023)—for many standard PDE problems, the answer is no. A method can be elegant conceptually and still lose in engineering practice.
- Benchmark contamination and memorization: As training corpora absorb more papers and preprints, “the model solved X” becomes harder to distinguish from “the model saw X’s answer.” Kosmos’s controls and FrontierMath’s private questions are direct responses to this problem.
- Biosecurity: A 2025 Science paper from Microsoft and collaborators showed that generative protein design can produce highly sequence-divergent variants of proteins of concern that evade some homology-based nucleic-acid synthesis screens; the work helped motivate screening patches. Important distinction: this is evidence of screening evasion and possible functional retention, not proof that the designed variants experimentally match the original toxin’s function.
- Reproducibility and openness: Open and Sustainable AI in the life sciences (2025) reviews trust problems caused by closed weights, inaccessible data, and unreconstructable environments. The initial AlphaFold3 release controversy is one example of a broader structural issue.
10 / MILESTONES
9. Milestone research results
This is not a complete bibliography. It is a list of “why this work is worth keeping in your head.” Years are included mainly to help orient technological progression; for preprints, online-first papers, and works that span publication years, the linked primary version takes precedence over strict bibliographic chronology.
Foundations and methods
| Year |
Work |
Why it belongs |
| 2017 |
Neural Message Passing for Quantum Chemistry |
Established the GNN paradigm for molecular-property prediction |
| 2019 |
Physics-Informed Neural Networks |
Canonical example of “writing physics into the loss”; useful in both success and failure |
| 2020 |
Fourier Neural Operator |
Learn the simulator rather than one simulation result; opened a major route for learned simulation |
| 2021 |
Geometric Deep Learning |
Gave graphs, symmetry, and equivariance a unified conceptual language |
| 2022 |
NequIP |
Demonstrated the data-efficiency gains of equivariance and became a key ancestor of later atomistic potentials |
Life sciences
| Year |
Work |
Why it belongs |
| 2021 |
AlphaFold2 |
Learned inference overwhelmed a scientific bottleneck that had stood for decades |
| 2023 |
ESMFold / ESM-2 |
Protein language models showed that useful structure prediction can work without MSAs |
| 2023 |
RFdiffusion |
Shifted from predicting structure to generating it; a watershed for protein design |
| 2024 |
AlphaFold3 |
Extended structural prediction to complexes and connected directly to industry needs |
| 2024/26 |
Evo → Evo 2 |
Brought foundation modeling down to genomic sequence itself, with million-base contexts |
| 2025 |
ESM3 |
Joint multimodal modeling of sequence, structure, and function |
| 2025 |
BindCraft |
Raised de novo binder experimental hit rates and made “lab hit rate” a first-class capability metric |
| 2026 |
AlphaGenome |
Unified sequence-to-function prediction across regulatory readouts and advanced noncoding variant-effect prediction |
Chemistry and materials
| Year |
Work |
Why it belongs |
| 2021 |
Open Catalyst 2020 |
Helped define evaluation culture through open datasets and competition |
| 2023 |
GNoME |
Connected model screening, DFT data generation, and an iterative expensive-label flywheel |
| 2023 |
A-Lab |
Connected computational candidates, experimental planning, robotic synthesis, XRD, and active learning in one loop |
| 2023 |
Coscientist |
One of the first LLM systems to directly drive chemistry hardware |
| 2024– |
MatterSim / UMA / GRACE |
Push universal potentials across broader chemistry and reduce the cost of energy/force evaluation |
| 2025 |
MatterGen |
Shifted from screening toward inverse generation conditioned on target properties |
Earth systems
| Year |
Work |
Why it belongs |
| 2022/23 |
FourCastNet / Pangu-Weather |
Early demonstrations that data-driven forecasting could compete with operational systems |
| 2023 |
GraphCast |
Clear evidence that learned forecasting can compete on mature operational benchmarks |
| 2024 |
NeuralGCM |
A hybrid route addressing the question of extrapolation to unseen climate states |
| 2025 |
GenCast |
Moved from deterministic prediction to probabilistic ensembles and better matched the real shape of the problem |
| 2025 |
Aurora |
One model spanning weather, air quality, and waves |
| 2026 |
WeatherNext Cyclones |
Roughly a day of additional forecast lead time on 2023–2025 cyclones, with public code and weights |
Mathematics and algorithms
| Year |
Work |
Why it belongs |
| 2022 |
AlphaTensor |
Found matrix-multiplication algorithms better than known human solutions |
| 2024 |
FunSearch |
Let an LLM evolve programs, paired with an executable evaluator |
| 2024 |
AlphaGeometry |
Neural–symbolic hybrid performance near gold-medal level on Olympiad geometry |
| 2025 |
AlphaProof |
Reinforcement learning + Lean brought formal proof to medal-level performance |
| 2025 |
AlphaEvolve |
A general generator + evaluator + search pattern that transferred across domains |
| 2026 |
AlphaProof Nexus |
Solved 9/353 open Erdős problems; a simpler LLM ↔ Lean loop reproduced the successes at higher cost |
Agents and automation
| Year |
Work |
Why it belongs |
| 2023 |
ChemCrow |
Early pattern for linking LLMs to chemistry tools |
| 2024/25 |
The AI Scientist / v2 |
A probe of end-to-end automation; the controversy itself is informative |
| 2025 |
Kosmos |
Long-horizon coherence plus a useful design for checking memory contamination |
| 2026 |
Co-Scientist |
Turned hypothesis generation into explicit search, debate, and ranking |
| 2026 |
Robin |
Connected agents, experimental strategy, real biological measurement, and later analysis into a continuous chain |
| 2026 |
Empirical Research Assistance |
Narrowed the target to scoreable empirical software so large-scale search can receive objective feedback |
Physics and other areas
| Year |
Work |
Why it belongs |
| 2022 |
Tokamak plasma RL control |
Reinforcement learning directly controlling a real physical device |
| 2024 |
FlyWire whole-fly-brain connectome |
AI segmentation + human correction at enormous collaborative scale |
11 / PATTERNS
UPDATE
Conclusion: patterns in the map
1. Success depends heavily on reliable, standardized evaluators that generate clear feedback. Mathematics has Lean, weather has tomorrow’s observed reality, and protein structure has decades of PDB accumulation, mature structure measurement, and CASP blind tests. These differ radically in cost—crystallography is certainly not cheap—but they share one property: there is a relatively clear way to know when the model is wrong. Materials and cell biology are more contentious precisely because feedback is slower, noisier, and lacks a single accepted referee. If you are choosing an AI4S direction, ask first: how long until you know you were wrong?
2. Data infrastructure is systematically undervalued. PDB was built gradually by the global structural-biology community over decades; AlphaFold’s model breakthrough occurred on a much shorter timescale. That gap should change how we think about “where the next AlphaFold will happen.” It may depend on a field that has already accumulated standardized data, evaluation, and experimental truth—not just on a new architecture.
3. Domain knowledge is moving from “written into the architecture” toward “written into tools, data, environments, and evaluators.” The AlphaProof Nexus ablation—where a simpler agent also solved all nine problems but at higher cost—and the shift from specialized potentials to universal potentials in materials point in the same direction. This does not mean domain knowledge is no longer useful; it may simply be injected elsewhere. Existing evidence is not enough to conclude that general models will replace specialized models wholesale.
4. There are visibly fewer candidates on the right half of the loop. Among the 21 curated works here, 13 touch “model,” while only 3 touch “experiment” and 2 touch “feedback.” This is a curated map rather than a literature sample, so the counts should not be treated as field statistics. But the directional asymmetry is hard to ignore. The next bottlenecks increasingly sit at interfaces: can a molecular generator understand synthesis constraints before proposing candidates? Can an interatomic potential know when it is out of distribution? Can an agent distinguish a genuinely new hypothesis from one that simply failed retrieval? Can an autonomous experiment preserve enough provenance for another lab to reproduce it?
5. The “AI scientist” systems in this map still operate inside a larger human loop in which people define goals, perform critical experiments, or make final judgments. The important 2026 shift is not that a fully autonomous scientist already exists; it is that the “hypothesize → validate → revise” loop is becoming much faster. The distinction matters. A model that can read your data is a useful tool. A model that can say “synthesize this compound; I predict it is thermodynamically stable,” and be right often enough that the prediction is worth scarce lab time, changes the economics of discovery. The latter is beginning to appear—but a human still signs off.
The long-term opportunity is therefore larger than “AI that helps scientists.” It is a system in which knowledge, computation, and experiment continuously improve one another.
If you know a piece of work that belongs here, or spot something that should be corrected, I’d be glad to hear from you.